# Dreamerland

All in one AI art generator

Dreamerland is an advanced AI art generator that empowers users to create unique and breathtaking pieces of art using the power of artificial intelligence. In this tutorial, we will guide you through the steps on how to effectively utilize Dreamerland and unlock your creative potential.

1. <mark style="background-color:orange;">**Choose the model you want**</mark>

We provide several models for you to choose from. Different models are fine-tuned for different purposes. Some models are designed for generating Anime art, some for generating artistic images, while others are specifically tailored for creating photorealistic images.

![](https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FpA0dtQVZdd31zqyrN7Br%2FIMG_7772.jpg?alt=media\&token=6a4fa71f-b9be-4021-af82-796453fd53fb)![](https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FOVFG3W77XgFhh8IhxERN%2FIMG_7771.jpg?alt=media\&token=68022701-8715-44d5-b031-fc43d23be0fb)

**Anime:** Anime Diffusion V2, Anime Diffusion, Meina's, Dark Sushi Mix, RealCartoon3D, Galaena REDUX, Mistoon Anime

**Photoreal:** Dreamer Photoreal V2, Dreamer Photoreal, majicMIX realistic, Realistic Vision, XXMix 9realistic, epicRealism

**Artistic/General purpose:** Dreamerland, DreamShaper

2. <mark style="background-color:orange;">**Write your prompt**</mark>

Your prompt is where you will begin writing about what you dream of seeing in the art you want to generate. Please describe your idea clearly. The more descriptive you are in your prompt, the more vibrant and unique the output will be.

The sequence of words matters. Words near the front of a prompt are weighted more heavily than the words at the back of a prompt. You can usually follow this order to write your prompt:

1. Start with the subject and art style.
2. Provide a detailed description of the subject.
3. Describe the background, including the location and time.
4. Specify the lighting and angle.
5. Include any additional details you would like to add.

To adjust the weights of words, you can increase the weighting by using parentheses "()," or decrease the weighting by using square brackets "\[]". You can even use multiple parentheses like (((white hair))) to further emphasize certain words.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fib6UWrePu0QMzRr4joOJ%2FIMG_7774.jpg?alt=media&amp;token=c314ba0a-97a5-4767-b679-8071d7e59716" alt="" width="375"><figcaption></figcaption></figure>

3. <mark style="background-color:orange;">**Select preset styles you want to add into your art (optional)**</mark>

We offer a wide selection of hundreds of preset styles for you to choose from. You have the freedom to mix and match different styles to create your unique art. You can select up to a maximum of 12 styles to incorporate into your artwork.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F9LZLsfvuYxbijzwAMnQ3%2FIMG_7775.jpg?alt=media&amp;token=e3a55e7f-9799-4ec6-b81a-96e32b9afea6" alt="" width="375"><figcaption></figcaption></figure>

You can click on the selected style to adjust its weight, which will affect how much influence the style has on your art.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FoBaBGu7UWnUaz3fXlnmu%2FIMG_7776.jpg?alt=media&amp;token=91c445b7-b3f7-4a95-8e05-0766615d5962" alt="" width="375"><figcaption><p>Click on your selected style</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FHDWRgz0JlkGc0As97iaW%2FIMG_7777.jpg?alt=media&amp;token=145703cc-928c-442d-93b3-6a0910a27286" alt="" width="375"><figcaption><p>Adjust style weight with slider</p></figcaption></figure>

4. <mark style="background-color:orange;">**Negative prompt and negative embedding**</mark>

The inclusion of a negative prompt is crucial. Please specify something you do not want to appear in your art. Providing a precise negative prompt will significantly enhance the quality of the output.

Additionally, you have the option to choose from our preset negative embeddings. This can be helpful if you're unsure about what to write in the negative prompt, as it provides a simple and convenient alternative.

For further information on negative embeddings, please refer to the following resource:[Negative embeddings](/basic-terms/negative-embeddings)

5. <mark style="background-color:orange;">**Other settings**</mark>

We provide users with a great deal of freedom to customize their experience. You can adjust the settings according to your specific needs. In another section, we will explain the various settings and how they work in detail.

6. <mark style="background-color:orange;">**Start Drawing Now!**</mark>

Click the yellow 'Start Drawing' button to begin. You are now ready to create your first AI art masterpiece.


# Hires. fix

High Resolution Fix - Upscale the image and fix details

High-Resolution Fix (Hires. Fix) is a process that involves upscaling an image and subsequently redrawing it based on the original image. Hires Fix is essential for achieving high-quality images as it can enhance the characters' faces and add additional details. However, it is worth noting that this process may alter the images to some degree, depending on the strength value applied.

<mark style="background-color:orange;">**How does it work?**</mark>

We create a image with prompt "a woman wearing tee shirt walking on a street, full body". The resulting image is in a good composition but the face of the woman is obviously deformed.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FHBQUUi7njUMe0C20XN8A%2FIMG_7780%202.JPG?alt=media&amp;token=6efc36d6-eaba-4e95-88d7-3243f552668e" alt=""><figcaption></figcaption></figure>

We can use the 'High-res Fix' feature, which allows us to upscale and enhance the image, focusing specifically on improving the face. To access this feature, simply click on the 'High-res Fix' button located at the bottom of the page. It will provide you with a range of settings to adjust for the high-resolution fix.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FKYvsnUc9V3LDlUha3y0B%2FIMG_7782.jpg?alt=media&amp;token=3d8d9e0a-454b-4627-8bb8-dc8b7abbcbdf" alt="" width="375"><figcaption><p>High resolution fix button</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FyEmtJAgmqG3XnVbPIloO%2FIMG_7785.jpg?alt=media&amp;token=9d6ef70e-3efa-4fec-a1e8-84094958ea41" alt="" width="375"><figcaption><p>High resolution fix setting</p></figcaption></figure></div>

If you are unsure about the various settings, you can leave them at their default values and simply click the 'Fix Now' button to initiate the high-resolution fix process.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FHBQUUi7njUMe0C20XN8A%2FIMG_7780%202.JPG?alt=media&amp;token=6efc36d6-eaba-4e95-88d7-3243f552668e" alt="" width="256"><figcaption><p>Before</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F6OJtBZHf2ipJwJijJabA%2FIMG_7781%202.JPG?alt=media&amp;token=5d08045c-5fd6-4db4-be23-e8ccbce8c8e2" alt="" width="563"><figcaption><p>After high res fix</p></figcaption></figure></div>

After the high-resolution fix process, you will notice a significant enhancement in the face, as well as improved details on the hands and shoes. The overall image quality is greatly improved, and it is upscaled to 2X its original size.


# Hires. fix with different model

High resolution fix in different styles

Building upon the previous example, during the high-resolution fix process, you have the option to utilize different models. By selecting different models, you can achieve distinct styles in the final output, providing you with a range of possibilities to explore.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FsrRRxwdVCyodkbT2J3VY%2FIMG_7786.jpg?alt=media&amp;token=f7219727-7f97-4af2-959a-f20555e7b821" alt="" width="375"><figcaption><p>We changed the model from Photoreal V2 to Anime V2</p></figcaption></figure>

When you look at the final image, you will see that it has transformed into an anime style while keeping the original composition and details intact. The high-resolution fix process has also corrected and improved the appearance of the face and hands.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FHBQUUi7njUMe0C20XN8A%2FIMG_7780%202.JPG?alt=media&amp;token=6efc36d6-eaba-4e95-88d7-3243f552668e" alt="" width="256"><figcaption><p>Original image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FUKYh67JAsDQeb7LNfLek%2FIMG_7791.JPG?alt=media&amp;token=71f00e3f-0250-426b-9251-0a8fb598b69d" alt="" width="563"><figcaption><p>High resolution fix with Anime model</p></figcaption></figure></div>


# Optical illusion

A image appear as one thing from a distance, but up close they reveal something completely different

<mark style="background-color:orange;">**What is optical illusion?**</mark>

Optical illusion is an illusion caused by the visual system and characterized by a visual percept that arguably appears to differ from reality.

<mark style="background-color:orange;">**How does it work?**</mark>

Here is a demonstration on how to generate an image that makes a landscape look like a woman.

1. Go to the shortcut page and click on "Optical illusion."
2. Select a reference image.&#x20;
3. Write down the prompt for the illusion. We will use a simple prompt such as "river, sky, forest."
4. You can click on the control layer to adjust the conditioning scale. The higher the value, the more the resulting image will follow the reference image, but it will be less creative.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FDPcMFOOuCHYNI2DpBY6p%2FIMG_7748.jpg?alt=media&amp;token=f04ad695-002c-45e8-aeab-cf545e9f276b" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FDZT6tejleyeg7VeOJalU%2FIMG_7749.jpg?alt=media&amp;token=8399198d-6b31-415a-af7f-e545d32e93a2" alt="" width="375"><figcaption></figcaption></figure></div>

After everything is set, click the button to start generating. Wow, the result is amazing. Can you see the woman in the landscape picture?

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FvOT4Ak9rD7KwwddcBXNL%2FIMG_7751.JPG?alt=media&amp;token=41702378-6c99-435a-9977-2fdc60a2a3f5" alt=""><figcaption></figcaption></figure>


# Inpainting

Inpainting is a technique used to modify or restore masked areas in an image. Depending on the strength of inpainting, it can serve two purposes. Firstly, it can be employed to create entirely new content within any region of an existing picture. Secondly, it can be used to subtly restore deformed parts of an image.

Let's look at a simple example of inpainting. We will use this image as a base image.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FmIUwvVaBkUkdll6O1wEh%2FIMG_1405.JPG?alt=media&amp;token=5c0eb284-fdc6-42ef-aa73-def6c43a2514" alt="" width="375"><figcaption><p>A girl with black hair, wearing school uniform, in classroom</p></figcaption></figure>

We will try to change her hair color by inpainting function. Follow the steps below:

1. Choose Inpaint Mode
2. Select a source image from your phone
3. Mask the hair area in the image
4. Enter "1girl, pink hair" in prompt

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FS5R9ADnhQBwIkjvjt9Za%2FIMG_1404.jpg?alt=media&amp;token=78839867-0d65-4ec2-95c0-00d171861c3a" alt="" width="375"><figcaption><p>Select inpaint mode</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FupbFZKL8n7DLW5LGAQNy%2FIMG_1403.jpg?alt=media&amp;token=a4b45038-d238-425b-a134-b3b9bb1bd398" alt="" width="375"><figcaption><p>Mask hair area</p></figcaption></figure></div>

Now we can hit Start drawing button to see the result. The final output is absolutely awesome.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FQ3qhY1F9j390J9Jw9wxc%2FIMG_1402.JPG?alt=media&amp;token=0d4e8277-1a9d-41e7-9fb8-b60c94c774d5" alt=""><figcaption></figcaption></figure>


# BrushNet

BrushNet is a novel image inpainting model hat focuses on preserving image details and structures while filling in missing or masked regions. Unlike traditional inpainting methods that may distort original content, BrushNet ensures high-fidelity reconstruction by incorporating multi-stage fusion and reference feature injection.

Version 1.34.1 introduces the BrushNet option for inpainting, **currently available exclusively for SDXL models**.

<mark style="color:yellow;">**For subtle image edits, it's better to use low-strength inpainting (around 0.4-0.6) without BrushNet, as BrushNet tends to make more noticeable changes to the inpainted area.**</mark>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FlpcsQu6u3vlk875ZZlTQ%2FScreenshot_20250330_034219.jpg?alt=media&amp;token=e14eea39-c26a-43cc-981e-4b829798742b" alt="" width="375"><figcaption><p>Check the box next to BrushNet to enable this BrushNet feature.</p></figcaption></figure>

Let’s take a look at the examples below to see the difference between inpainting with and without BrushNet.

In this example, we’ll add a beer to the table in the photo by masking the region for inpainting.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FwvwS1xsGNLqvzNNgBjdK%2FScreenshot_20250330_032442~2.jpg?alt=media&amp;token=72438e4a-1adb-4199-ac44-c2909f34ca2e" alt="" width="375"><figcaption><p>Prompt: A beer on the table</p></figcaption></figure>

Let's see the result with and without BrushNet:

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FuAj5zDAaMr5n0kBw26Su%2F1743277362681.jpg?alt=media&amp;token=8df2f932-9c50-413d-91ab-d66cdd92d450" alt="" width="375"><figcaption><p>With BrushNet</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FGUZPLqrTC7S0GHOOwPx6%2F1743277379343.jpg?alt=media&amp;token=8bc21b26-c8b8-4ab7-a1cc-f1bea7e907c6" alt="" width="375"><figcaption><p>Wihtout BrushNet, 0.8 strength</p></figcaption></figure></div>

The results clearly show that BrushNet preserves the original image structure while seamlessly adding the beer to the table.


# Inpaint not masked

We have introduced the fundamental inpaint function, and now we will discuss the concept of "inpaint not masked" in this section.

There are instances when you may want to preserve a specific small area, typically a face, while redrawing or modifying the rest of the image.

Let's see how this work with a simple example. We will use this image as base image in this section

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FO7fftfZNONIc02vnOPxc%2FIMG_1396%202.JPG?alt=media&amp;token=644feac2-ee27-4f4c-8060-96089779b07a" alt="" width="563"><figcaption><p>a young girl, wearing schcool uniform, in classroom</p></figcaption></figure>

Similar to the normal inpainting process, we begin by selecting the inpaint mode and proceed to draw a mask. However, in this case, we draw the mask specifically on the area that we wish to preserve.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FVxC8AxE658yLvJmg8v4L%2FIMG_1399.jpg?alt=media&amp;token=1f9a0727-43f8-43cf-ac81-3ccab07edc0f" alt="" width="563"><figcaption><p>Draw a mask on the face</p></figcaption></figure>

After drawing the mask, remember to check the "Inpaint not masked" option. To maintain accurate body composition, it is advisable to utilize a control layer in conjunction with the inpainting process. In this case, we will employ Pose control with the base image.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FoJnanJJtDgQlZVL23GEM%2FIMG_1400.jpg?alt=media&amp;token=3741e8b1-1ba4-4f75-9df0-23abe440a951" alt="" width="563"><figcaption><p>Check "inpaint not masked", employ Pose control layer</p></figcaption></figure>

Lastly, input the desired prompt. In this case, let's use the following prompt: "1 girl, wearing bodysuit, pink hair, long hair, in cyberpunk city."

Now, click on the "Start drawing" button. Below is the resulting image we obtained:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FBrzRQxo1VvBQdGIbZtOR%2FIMG_1401.JPG?alt=media&amp;token=36236026-7e99-413e-a5b8-3be665f9eec0" alt="" width="563"><figcaption></figcaption></figure>


# Regional Prompt (1.40.0)

The regional prompt has been upgraded in version 1.40.0. This new regional prompt is more powerful and easier to use, enhancing the user experience significantly.

### <mark style="color:yellow;">**What's the update**</mark>

1. **Base prompt**

* The base prompt is now consistently applied across all regions of the image, ensuring uniformity and coherence in output.

2. **Isolate Lora style by region**

* You can now use Lora style specific to each region without interference. This resolves the previous issue where styles would affect other areas unintentionally, providing more control over regional styling.

3. **Color map grid editor**

* You can utilize the color map grid editor to customize your color maps effortlessly. This tool allows you to modify colors and patterns without starting from scratch, ensuring efficiency and precision in your design process.

### <mark style="color:yellow;">How It Works</mark>

#### Example: Creating Three Anime Characters in One Image

To create a cohesive image featuring three distinct anime characters using the styles and color map grid editor:

#### Step-by-Step Guide

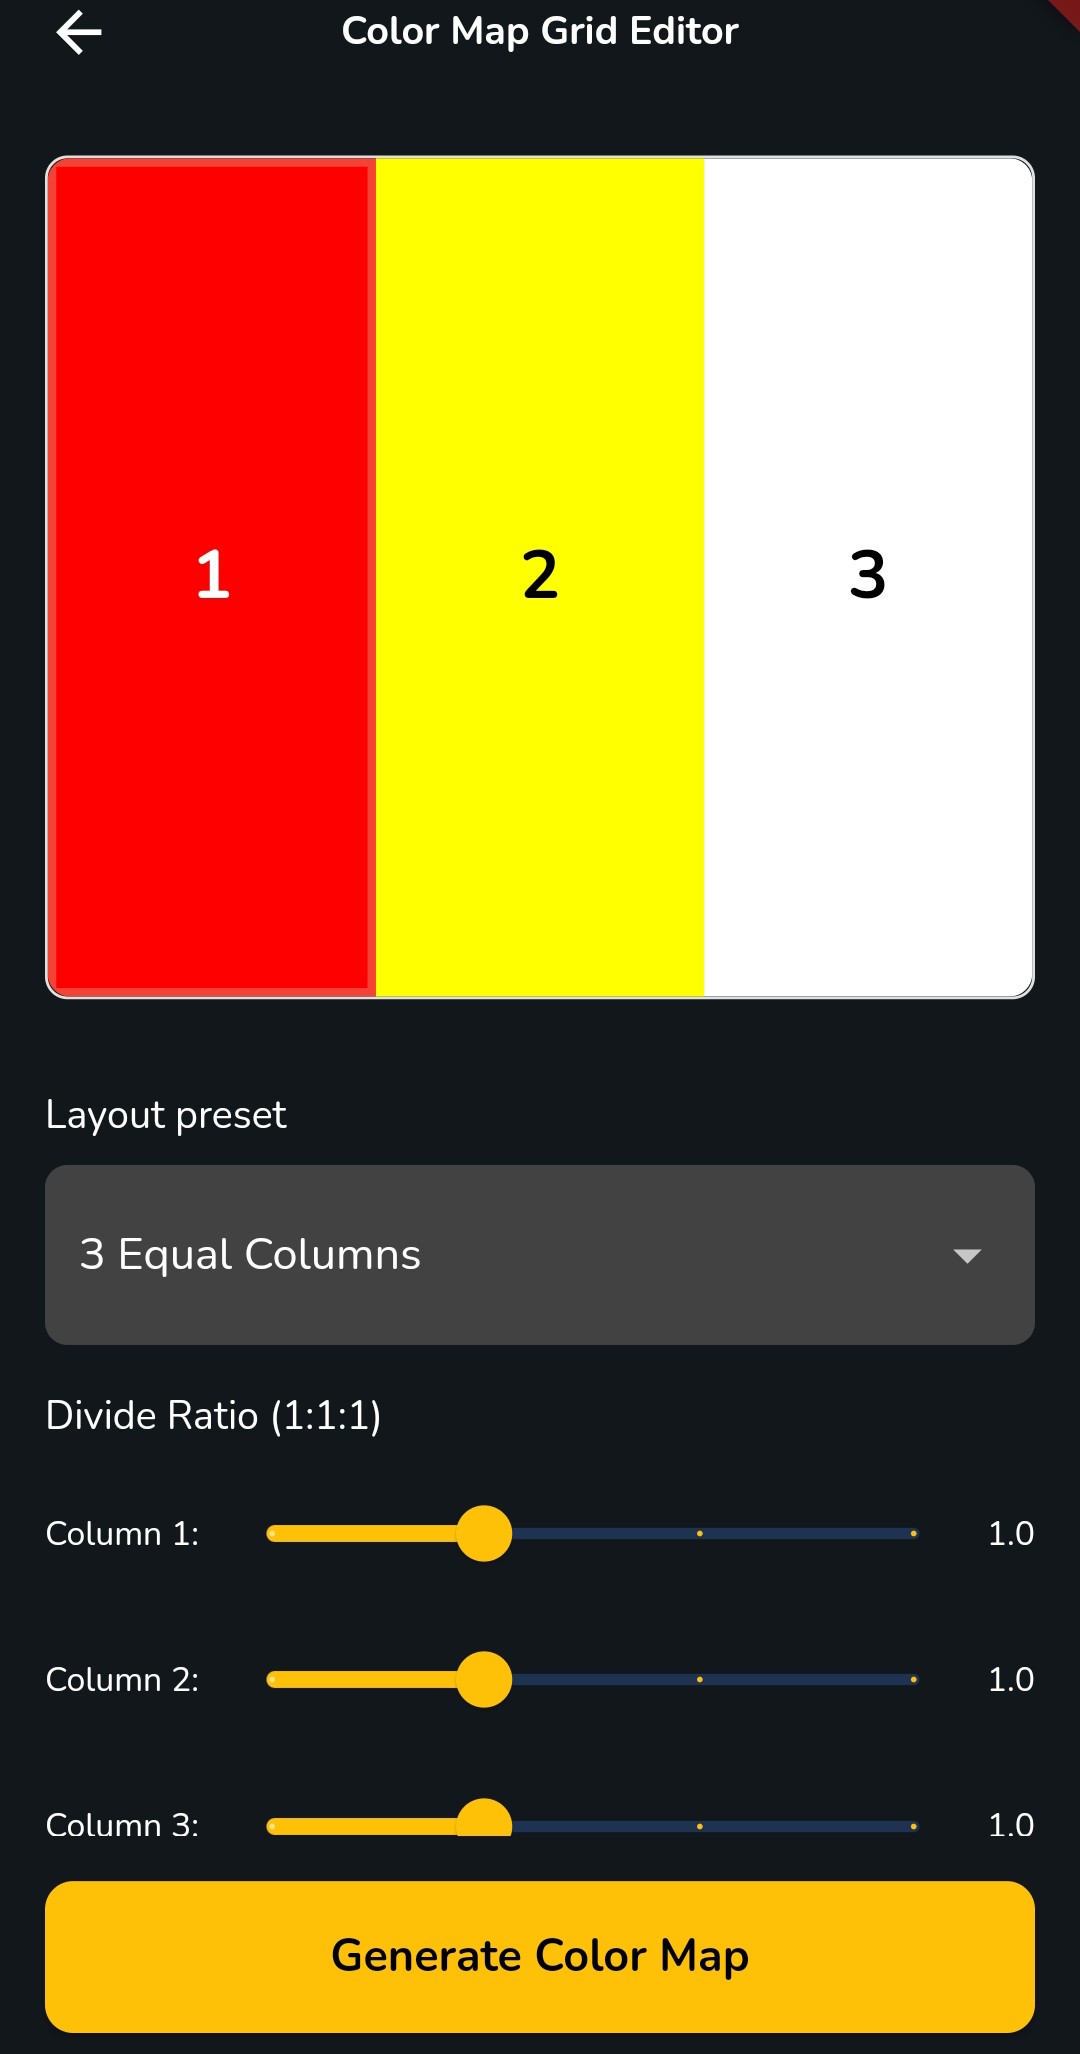
1. **Create a Color Map**: Utilize the grid color editor to create a color map. Select three equal columns and click "Generate Color Map" to establish the color palette for your image.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNFFWvvqavGONQMahDOE1%2FScreenshot_20250729_024644.jpg?alt=media&amp;token=b7bd7706-102b-42d9-bdc0-cd2e4495bfe4" alt="" width="375"><figcaption></figcaption></figure>

2. **Write a Base Prompt**: Next, we'll need to draft a base prompt for the entire image as base concept. Given that we have three girls as characters in the image, a suitable prompt might be: "3girls, standing in a living room."

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FMyiGhmvQp2LQEkITMty5%2FScreenshot_20250729_024057.jpg?alt=media&amp;token=daa6d728-a205-46cb-b99a-fffe880696ca" alt="" width="375"><figcaption></figcaption></figure>

3. **Craft Area-specific Prompts**: Write prompts and apply styles for each area. You should write a prompt specifically for each distinct area.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FownT6L9F4RxlfVYN13in%2FScreenshot_20250729_024106.jpg?alt=media&amp;token=b8b4a2f5-7b44-4667-bf4a-41b7209e79b8" alt="" width="375"><figcaption></figcaption></figure>

4. Hit the create button to check the result.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FznKVfBgRyxQBZCsB2pj4%2FTYqZO1P0IOgYkys0tV6v_0.png?alt=media&amp;token=72dc5fa9-8e12-4282-9c00-a489a2b5d456" alt=""><figcaption></figcaption></figure>

5. Bonus

You can use the control layer to adjust the poses of all three characters in the image.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPguSplnW0esXxzY10Wrw%2FScreenshot_20250729_033330.jpg?alt=media&amp;token=02117967-35d3-413e-96dd-eabe96053c62" alt="" width="375"><figcaption></figcaption></figure>

Here is the final result:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F2IJHJInLy1iwRZsc4ykf%2FehV8bIbZWnO2nOOjVT8a_0.png?alt=media&amp;token=d45d429a-6e3b-4ebb-8fcc-4279504b05da" alt=""><figcaption></figcaption></figure>


# Regional Prompt (color mask)

Control image composition in one generation

<mark style="background-color:orange;">**What is regional prompt?**</mark>

It is a tool that allows you to specify different prompts for different regions.

<mark style="background-color:orange;">**Why use a regional prompt?**</mark>

Have you ever found it difficult to create multiple subjects in a single image? Here is an example:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FCxwbVyrVwxpC3rfxPZfd%2FIMG_7736.jpg?alt=media&amp;token=d227d834-369f-4e25-8355-9e6565973bcf" alt="" width="375"><figcaption><p>try to generate a image with 2 girls. one girl with school uniform on the left. another one with bikini on the left</p></figcaption></figure>

You will probably get the result below with the above prompt. The resulting image is definitely not what we are thinking of.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FMc9hInBTW2Zoh4tAt0dH%2FIMG_7735.JPG?alt=media&amp;token=c5c4c102-c89d-43e4-ad9d-2ddf2bcbfc3d" alt="" width="375"><figcaption></figcaption></figure>

Regional prompt is your helper. We can specify different prompts for the girl on the left and the girl on the right using the regional prompt.

<mark style="background-color:orange;">**How does it work?**</mark>

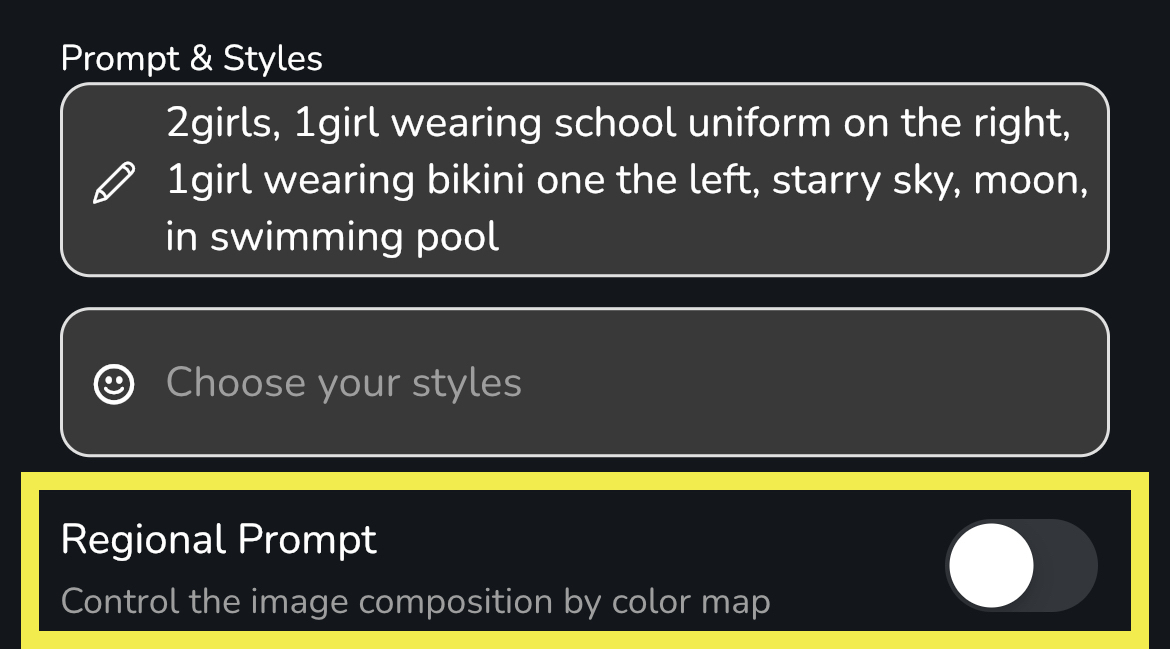
Enable the regional prompt feature with the toggle. It will take you to a color map page.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F4YTpPvPSLpHI5VtD0smk%2FIMG_7736%202.jpg?alt=media&amp;token=c6413207-aff3-4942-940e-a428ac53bd4f" alt="" width="375"><figcaption></figcaption></figure>

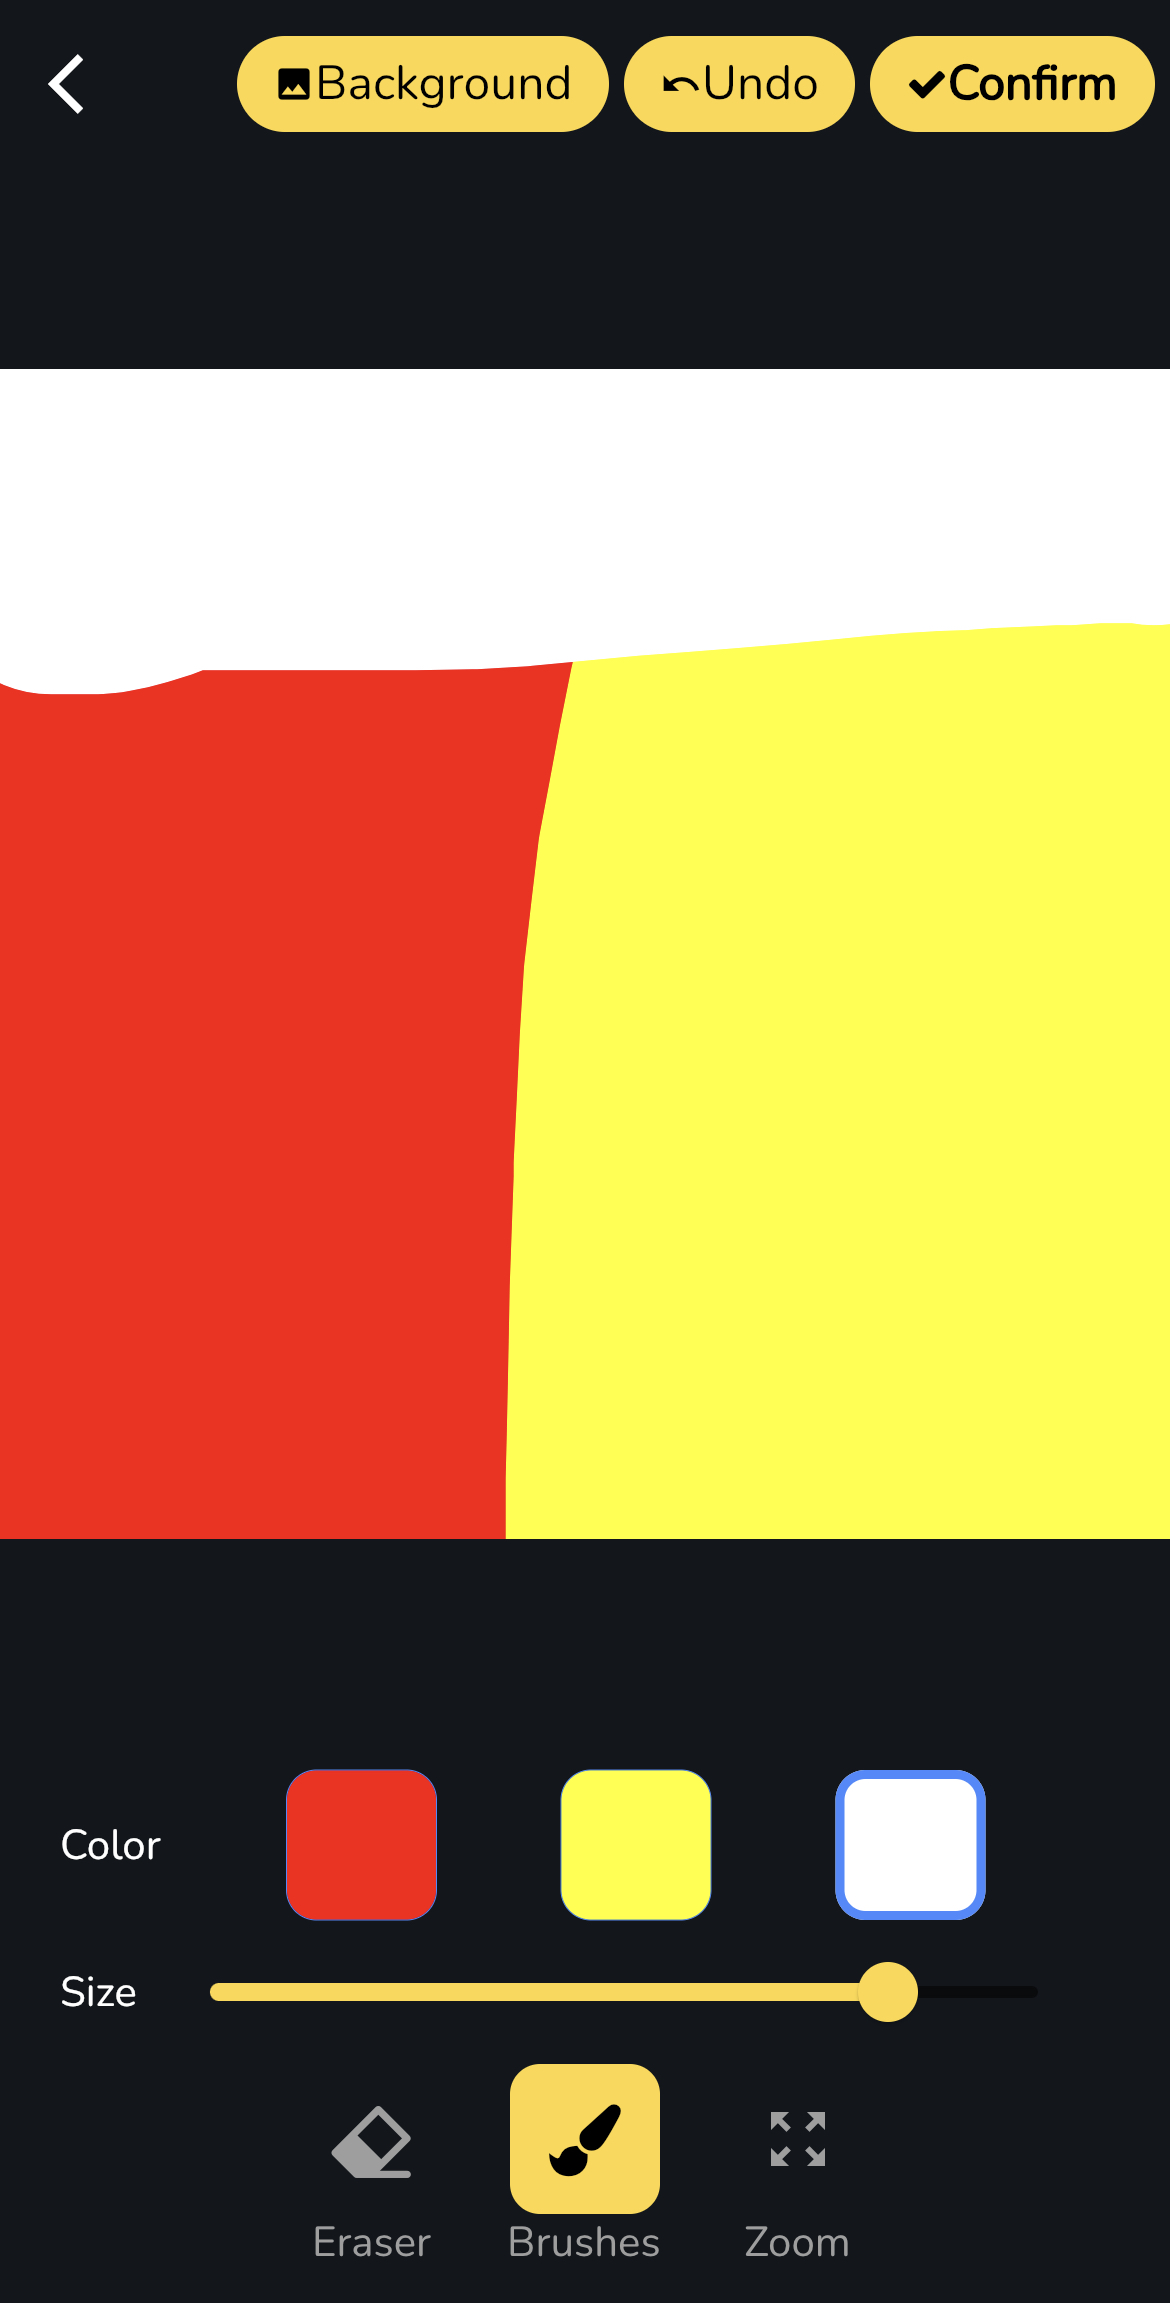
Draw a color map for image composition. For example, we want a girl with a school uniform on the left in the <mark style="color:red;">red</mark> area, a girl with a bikini on the right in the <mark style="color:yellow;">yellow</mark> area, and a starry sky on top in the white area. Here is the color map we drew:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FkJAY2V76czSIR1WZzdLW%2FIMG_7737.jpg?alt=media&amp;token=f1e40605-96dd-4f82-bc8f-89f18f1ce02a" alt="" width="375"><figcaption></figcaption></figure>

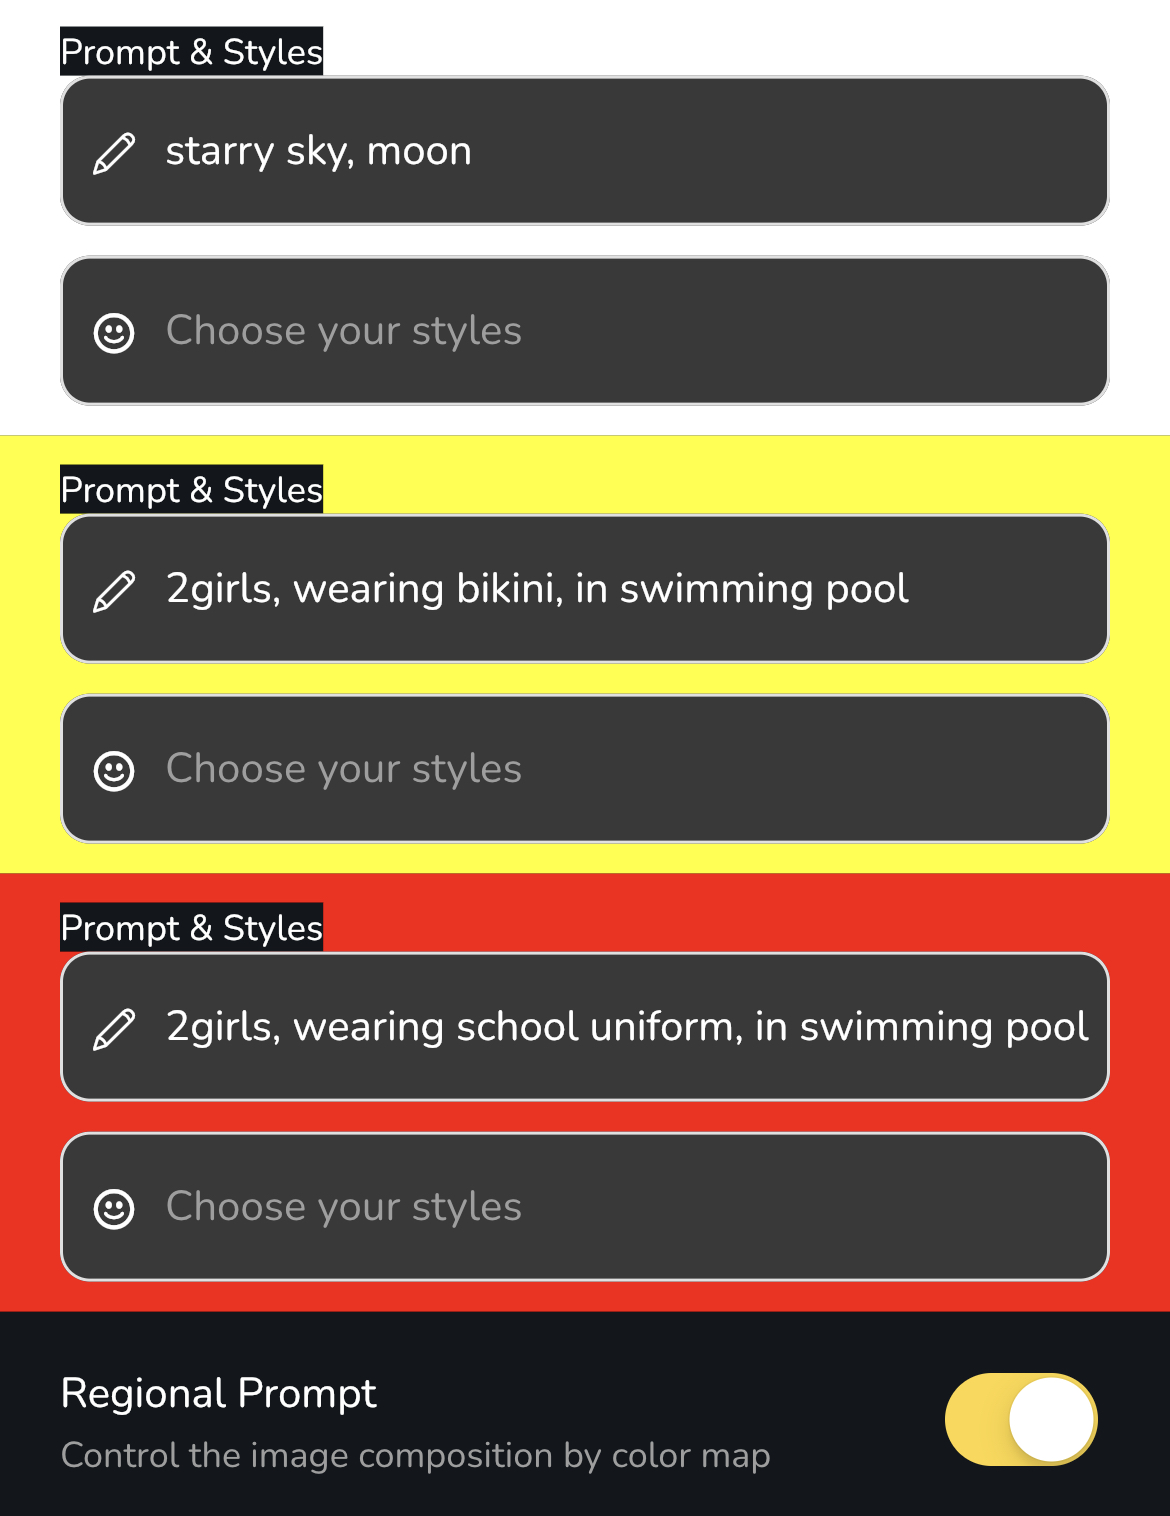
Great! We have a color map now. Let's create a prompt for each area. We enter the prompt for each area as shown below. \**Remember to specify "2 girls" in the prompt; otherwise, it will become "1 girl" wearing half a school uniform and half a bikini.*

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FkI1xvRXGrlbPd9Ex0HDu%2FIMG_7739.jpg?alt=media&amp;token=d566ae52-3b18-4f59-9107-2a9f482397da" alt="" width="375"><figcaption></figcaption></figure>

Start generating! We have a great image with the correct composition!

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FVsta9dFfsb1GXbg1DD4G%2FIMG_7738.JPG?alt=media&amp;token=090b8543-1832-48eb-bd26-ebea83054b9f" alt="" width="375"><figcaption></figcaption></figure>


# Regional Prompt with Reference Image

Control the image composition with control layer

You may want to have more control while using a regional prompt. Here, we bring you a demonstration of using a reference image to draw a color map and using the reference image in the control layer.

<mark style="background-color:orange;">**How does it work?**</mark>

In this example, we want to generate an image of a woman with half white hair and half black hair.

First, open the color map drawing canvas. Click the "Background" button to select a reference image.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FBwws9fUm5HryFSTfNN7l%2FIMG_7740.jpg?alt=media&amp;token=604c98cb-4b82-4f05-b073-d1a99d1be760" alt="" width="375"><figcaption></figcaption></figure>

Now, let's draw a color map on the reference image. We want the woman to have half white hair on the left and half black hair on the right. We'll use the color <mark style="color:red;">red</mark> for the left part of her hair and <mark style="color:yellow;">yellow</mark> for the right part.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FtFcWF31kU0UQrHJeNBQh%2FIMG_7741.jpg?alt=media&amp;token=23f5a0b5-1451-4759-b04b-a8ce4a15b514" alt="" width="375"><figcaption></figcaption></figure>

Here is a final color map we have. Next step is to write prompts for each area.&#x20;

<div align="left"><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FD2rPm45MdNkSegKwUYUS%2FIMG_7742.jpg?alt=media&amp;token=231884da-84aa-4087-b883-064b875b9fcd" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FN0Ewsbi6dl0LZTweMbVs%2FIMG_7747.jpg?alt=media&amp;token=f60dc780-d1bb-4fa5-a580-f1d54c786357" alt="" width="375"><figcaption></figcaption></figure></div>

Don't forget to add a control layer with the reference image. We used a depth control here.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fyj6MAvJwFotncUnxODIZ%2FIMG_7743.jpg?alt=media&amp;token=ff29af75-f9cb-48d8-ac04-11675d72ece6" alt="" width="375"><figcaption></figcaption></figure>

Okay, now we can click a button to generate images! Below are the resulting images of this configuration in both the realistic model and anime model.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FkTRAiCeXzVilnJKlqp7B%2FIMG_7745.JPG?alt=media&amp;token=2d3413f0-a827-4380-a101-a22180b7aea7" alt=""><figcaption><p>Dreamer photoreal V2 model</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FgKRRejRMGBjk4zQmWRcV%2FIMG_7746.JPG?alt=media&amp;token=98b410be-2e95-4dd9-bcf7-74fd2855a120" alt=""><figcaption><p>Anime Diffusion V2 model</p></figcaption></figure>


# Regional Prompt (prompt mode)

<mark style="background-color:orange;">**Why use a regional prompt?**</mark>

Have you ever found prompt bleeding in your image (one part of prompt effecting another part)? Let's see the below example:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FQvfbSuG1SbUw77feyVrk%2FIMG_7959.jpg?alt=media&amp;token=5b69d1c0-c736-4a66-b50c-3ff8474d176d" alt=""><figcaption></figcaption></figure>

We want to create a image with a Spanish woman wearing a forest printed tee shirt with Japanese temple around. We get the results below with this prompt.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FD76XxDRebck4kyHmSfHm%2FIMG_7952.JPG?alt=media&amp;token=cff3ad71-9be7-48bf-9567-df5dfb217758" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FiD2D8aqDYAYh6ATnWT2h%2FIMG_7958.JPG?alt=media&amp;token=32a81efb-4169-4f38-9b5a-72362b7f841f" alt="" width="375"><figcaption></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fi5jB78nDdWfOEmE8kqeT%2FIMG_7961.JPG?alt=media&amp;token=26b8ec48-668a-4704-a5d7-69f71f322a9c" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FGLf4yK50TdWPzqF5ZAo1%2FIMG_7960.JPG?alt=media&amp;token=71d23182-f1a2-42ce-9630-ceca216b22a3" alt="" width="375"><figcaption></figcaption></figure></div>

The tee shirt print is influenced by "Japanese temple". The skirt is affected by "printed" to be a printed skirt. Additionally, even the woman's face is affected by "Japanese" and "Japan" and she looks like an asian woman.

The regional prompt is designed to prevent prompt bleeding.

<mark style="background-color:orange;">**How it works?**</mark>

Let's try to move some descriptive words to regional prompt like this.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FLTlccfn4BPNHeRM4hgHN%2FIMG_7963.jpg?alt=media&amp;token=14209dbd-fc8c-4bee-8106-1337f2e4c6ee" alt="" width="563"><figcaption><p>edit in regional prompt mode</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FF9u4oyTYt1Y4hpViWnth%2FIMG_7968.jpg?alt=media&amp;token=ec52252c-8f5c-4f27-9ea9-3f5f0ea9c5ad" alt="" width="563"><figcaption><p>The final input</p></figcaption></figure></div>

Below are the results of the above setting

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FSuEjNxG70rlp7cxSo9eR%2FIMG_7964.JPG?alt=media&amp;token=c62a5521-16e8-44cb-a503-ead053f9bedb" alt=""><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F7AUNlpL94tANgjNL4txj%2FIMG_7966.JPG?alt=media&amp;token=50c6bd3b-040e-48a9-b4ee-28be36e642b6" alt=""><figcaption></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNizAxJk0WvCDW4Q6Xn2W%2FIMG_7967.JPG?alt=media&amp;token=11281681-067c-4e81-8e8c-30aac63cebdf" alt="" width="563"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fnmm2uxvTcGL7ECwXIEPD%2FIMG_7955.JPG?alt=media&amp;token=4b011282-0e12-42da-85cc-fd57ebd66f4c" alt="" width="563"><figcaption></figcaption></figure></div>

The result appears to be perfect, which precisely aligns with what we aimed for in our prompt.


# Outpainting


# Image prompt

An image as part of the prompt to influence the output image

[<mark style="background-color:orange;">**What is image prompt?**</mark>](#user-content-fn-1)[^1]

Image prompting is a technique used in AI image generation where an image is provided as an additional input to the text prompt. This image influences the composition, style, and colors of the output image. Both the text prompt and the image prompt act as conditioning factors, guiding the AI in generating an image that aligns with the desired visual elements and characteristics. By incorporating an image prompt, users can exert more control over the creative process and achieve specific artistic effects or styles in the generated images.

<mark style="background-color:orange;">**How it works**</mark>

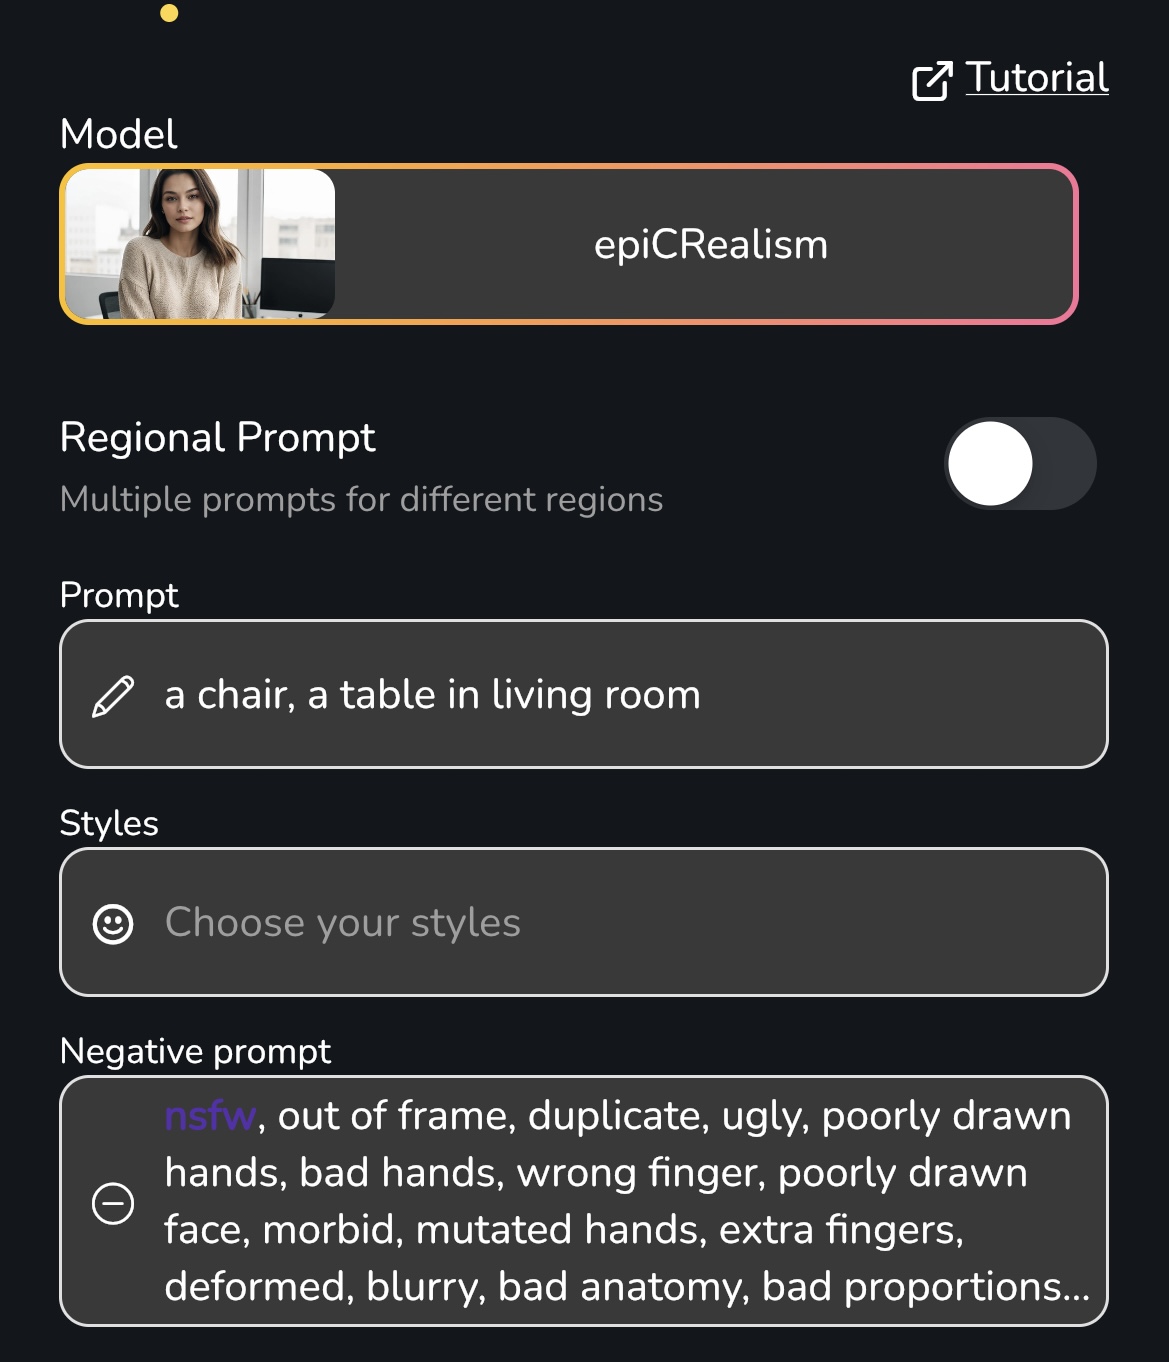
We would like to create an image featuring a golden chair and a golden table. To begin, we select a model and input a text prompt.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FKtOiDfcdef7cn9teAqWp%2FIMG_7901.jpg?alt=media&amp;token=47e4f4d9-b7ce-4fe7-bd9c-920b0933851f" alt="" width="375"><figcaption></figcaption></figure>

Let's observe how it looks without an image prompt.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FV2Qby1m0uoLsZ2oqkkRG%2FIMG_7903.JPG?alt=media&amp;token=ded5a24a-593a-4940-90b6-a73748cf89aa" alt="" width="256"><figcaption><p>a chair, a table in living room</p></figcaption></figure>

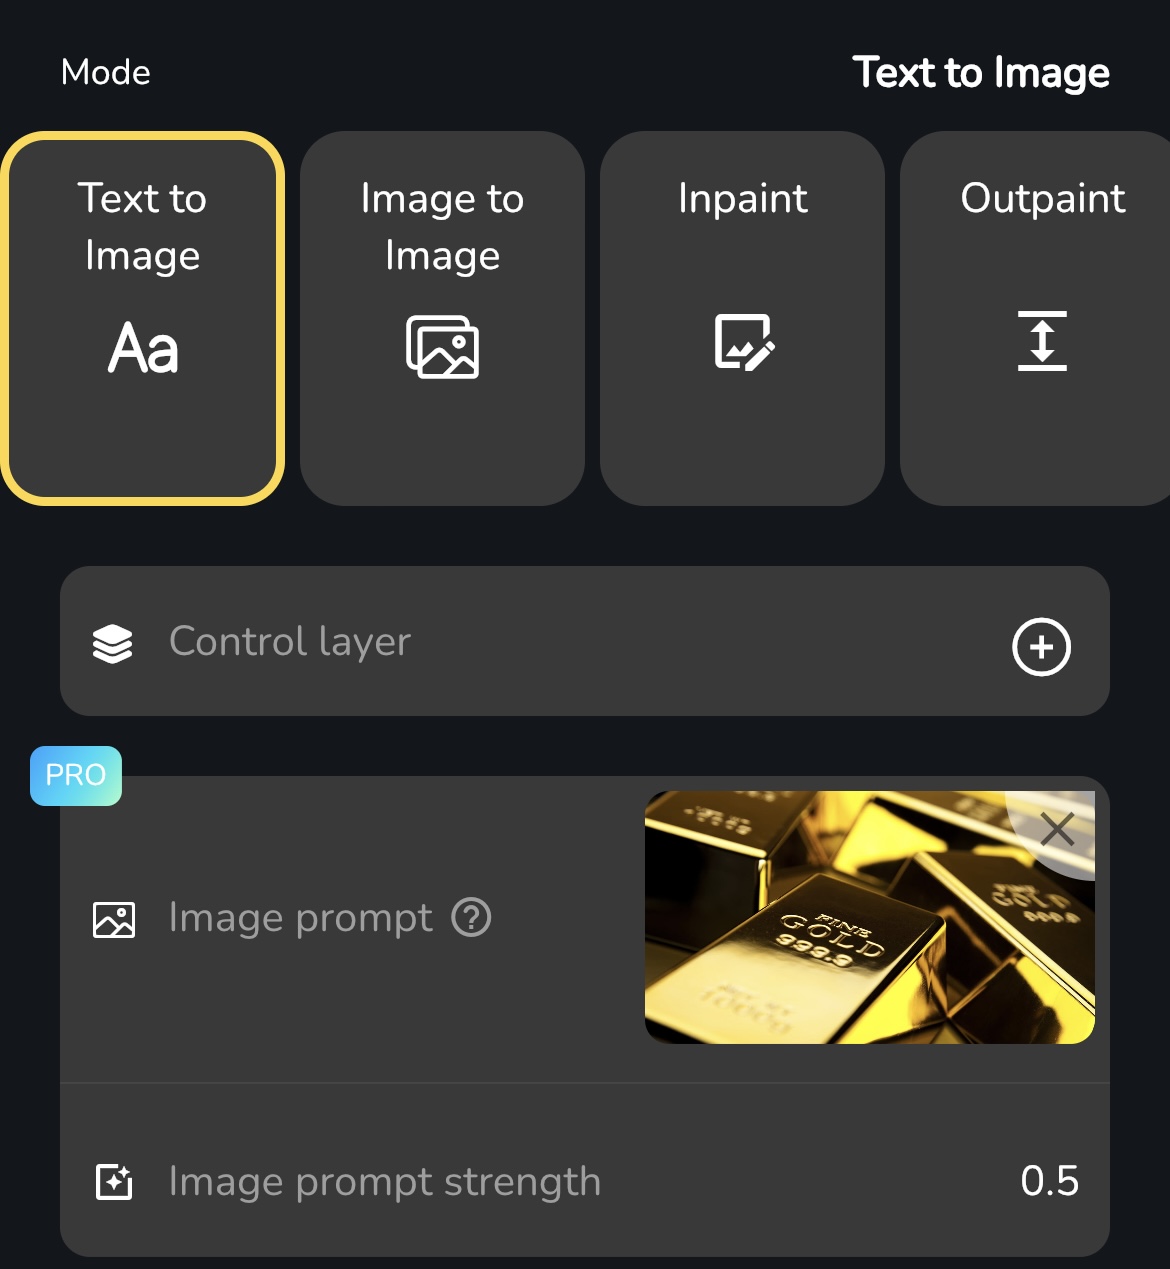
Next, we incorporate an image prompt into our generation process. We have discovered an image featuring gold that will serve as our prompt. In this instance, we only desire the gold color and texture, so we set the strength to 0.5 to prevent the AI from extracting the gold's shape.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FAkuVNUFKSOZzSwRTFWXH%2FIMG_7902.jpg?alt=media&amp;token=b5f51b6d-7754-4c83-96db-554c9d43062c" alt="" width="375"><figcaption></figcaption></figure>

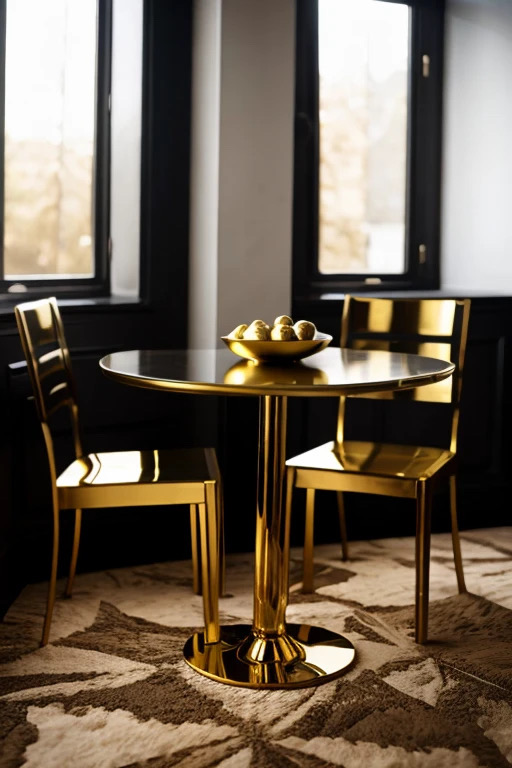
Once more, we click the "Start drawing" button and see the final result. That's perfect.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FblOrqukUJ3Nn9D5fmf3l%2FIMG_7904.JPG?alt=media&amp;token=aeaf438f-133f-479f-aa33-536e516fdce3" alt="" width="256"><figcaption><p>a chair, a table in living room</p></figcaption></figure>

Read more about image prompt on&#x20;

{% content-ref url="/pages/xAfo7n5yT5ibObFFdPKQ" %}
[Consistent face](/image/image-prompt/consistent-face)
{% endcontent-ref %}

{% content-ref url="/pages/375lgr6Sv9qnwIUYM8g4" %}
[Consistent anime character](/image/image-prompt/consistent-anime-character)
{% endcontent-ref %}

{% content-ref url="/pages/YQK7m7qdzXZG8w6Wll12" %}
[Style](/image/image-prompt/style)
{% endcontent-ref %}

[^1]:


# Consistent face

We can achieve consistent faces using an image prompt with just one image. Let's take a look at this example. (Please be aware that this feature does not involve face swapping. It may look similar but It will not replicate the face exactly as it appears in your input image.)

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FDNNZBgVcSD7I2G0eqwgk%2FIMG_7909.jpg?alt=media&amp;token=515e3625-daf7-4507-84f1-85d781417eb1" alt="" width="563"><figcaption></figcaption></figure>

Below are the results we can obtain with various text prompts.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FCr0nUvib1rvkoxLoyesE%2FIMG_7906.JPG?alt=media&amp;token=6f22b915-a6a7-4c6d-9066-ba4b1d9ec5db" alt="" width="384"><figcaption><p>a woman, wearing business suit, in office</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FUuGIibtp6DnDGlHSoBJV%2FIMG_7907.JPG?alt=media&amp;token=541642a3-c83f-4b80-b466-913354957f7a" alt="" width="384"><figcaption><p>a woman, wearing night dress, in party</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F0Ah44VKMDNbo1FNNoMgp%2FIMG_7908.JPG?alt=media&amp;token=fe0ecc14-2604-4f4f-8c90-a09f6a63d194" alt="" width="384"><figcaption><p>a woman, wearing lace bra, in bedroom</p></figcaption></figure>


# Consistent anime character

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FQRBTM66bMPYBHawP828t%2FIMG_7915.jpg?alt=media&amp;token=b7b6c8c9-39a8-4dd7-b261-772535d94abc" alt="" width="563"><figcaption></figcaption></figure>

Below are the results we can obtain with various text prompts using the image prompt setting above.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FA3ja2KrP1tOumjVyQiO2%2FIMG_7911.JPG?alt=media&amp;token=3d90d604-e577-43c2-9fc6-bb2414ce6c33" alt="" width="375"><figcaption><p>1boy, wearing school uniform, in classroom</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FptwftIbh0ssioi6ODtQ4%2FIMG_7912.JPG?alt=media&amp;token=8852a664-9fca-496c-8158-2952bda86980" alt="" width="375"><figcaption><p>1boy, topless, pants, on beach, sunlight</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FjAiEXCLP3V8liYj9OK6Q%2FIMG_7914.JPG?alt=media&amp;token=d51ea6b6-54c8-4709-ad2c-7f01807c96c4" alt="" width="375"><figcaption><p>1boy, wearing spacesuit, in space</p></figcaption></figure>


# Style

We can apply different styles to the image with image prompts. Let's draw a anime girl with control layer.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FmhYdZdhm2DMpzz8yU2EC%2FIMG_7939.jpg?alt=media&amp;token=ee182656-2474-4278-8e74-d27e392192e4" alt=""><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fl0mgrN89afYRqDTQcjCf%2FIMG_7923.jpg?alt=media&amp;token=c400727f-44be-40e1-a58d-50bcb785b158" alt=""><figcaption></figcaption></figure></div>

Next, while keeping all the settings the same, we apply different image prompts to see the differences.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPu9nol4HPj03UxQs56xw%2FIMG_7925.JPG?alt=media&amp;token=452f2219-ae20-40a8-a088-66ea81326e3d" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FgYiInx5elfAAvVHvklOR%2FIMG_7928.JPG?alt=media&amp;token=9766ea4b-a6fb-4152-93ba-a2064c4aa2e8" alt="" width="375"><figcaption></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FgCyQhnfwyMo89umqdCKz%2FIMG_7932.JPG?alt=media&amp;token=a74bec35-f0b7-4ac3-9588-773733b1d515" alt="" width="174"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FKGk0E1W6S6n1fHK8NVIl%2FIMG_7933.JPG?alt=media&amp;token=9d10f739-9568-45f3-9b4f-5872ecf6a73c" alt="" width="375"><figcaption></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FtxBI1ilecIPVPIc5DYtk%2FIMG_7920.JPG?alt=media&amp;token=415b7ee1-20e4-4ccb-87c9-c2fe8c153f6e" alt="" width="180"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FwBYbDZPPrgbKeqEtL5Rc%2FIMG_7929.JPG?alt=media&amp;token=8f66cd81-5975-4b03-ac40-14090b1e206a" alt="" width="375"><figcaption></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FyK6ANukEKOpmcs3u6HiM%2FIMG_7916.JPG?alt=media&amp;token=e8d89ad5-dd3c-43a5-96ae-510b9c583f0c" alt="" width="215"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FeevqD1N3OXJ0PHP7ieVd%2FIMG_7930.JPG?alt=media&amp;token=29e9a983-1830-4f13-b732-1c6f76b7284c" alt="" width="375"><figcaption></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FlR0fDjiZpHvgAWLZqe0b%2FIMG_7936.JPG?alt=media&amp;token=27893710-0201-4446-898b-76b1d819f3d0" alt="" width="182"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FUhRTEqFBnzGDYfFqopmV%2FIMG_7938.JPG?alt=media&amp;token=8ab1e03f-17ec-4ecb-b91a-9e8354ad5f0d" alt="" width="375"><figcaption></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPWhra2ctKdOgBmHc7hYQ%2FIMG_7934.jpg?alt=media&amp;token=d3168a10-f5bf-4c47-84c8-504329f3e637" alt="" width="282"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F08NdvmzjtosrodC4rxsI%2FIMG_7937.JPG?alt=media&amp;token=f709ee95-ecb9-4763-b06f-7d5cb03c4ee4" alt="" width="375"><figcaption></figcaption></figure></div>


# Doodle

Doodle, a captivating feature that unleashes your creativity, allows you to draw and transform your sketches into magnificent works of art. With Doodle, the possibilities are endless as you effortlessly wield virtual brushes, pencils, and colors to bring your imagination to life.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FLnvpxDVxbyvkLafaAfxc%2FIMG_9200.jpg?alt=media&amp;token=fd9d3a19-248b-4148-bd1d-88c146d38fcd" alt="" width="375"><figcaption><p>Select doodle mode</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNnl1xVhz3SfPLbF8SNG3%2FIMG_9201.jpg?alt=media&amp;token=0d59e679-8981-4abc-9081-c0d8113468d7" alt="" width="375"><figcaption><p>Draw on the whiteboard</p></figcaption></figure>

Below is the result of our drawing

Remember to type prompt to describe your image:

1girl, red hair, wearing bikini, grass, blue sky, red moon, holding a sword

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FO5wW1XTun2bxrAdBA3v0%2FIMG_9146.jpg?alt=media&amp;token=402e9731-c4b7-4aff-b63e-041c29db7029" alt="" width="188"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPDfQljSLeCHM4LoojHFF%2FIMG_9145.JPG?alt=media&amp;token=b0c59f99-9890-4008-8c03-ab868c09843b" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FRvTFxc5xyBCxq81eCorl%2FIMG_9148.JPG?alt=media&amp;token=9f0c1f05-51d3-46be-a16e-edb9d8f8492b" alt="" width="375"><figcaption></figcaption></figure></div>

You can also add a image to your drawing like this example below. We add a sniper gun image to our drawing. Click the +Add button to add any image assets you want.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FhURPCiU1CVlCBP91J1lI%2FIMG_9149.PNG?alt=media&amp;token=553e6cb5-3cc0-47f5-97dd-af2bcbcd070d" alt="" width="375"><figcaption><p>Sniper gun image</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FrAZb7755fmJstIPXciyl%2FIMG_9151.jpg?alt=media&amp;token=6f86458c-2e27-4f3f-8200-d394881ba34f" alt="" width="375"><figcaption><p>1girl, holding a sniper gun, in swimming pool, wearing bikini, purple hair</p></figcaption></figure>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FtnTSDwcHCoDoCglPUvAO%2FIMG_9152%202.JPG?alt=media&amp;token=b48866d6-cd86-45c1-b5db-5b66e1266af9" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fo0bjyy0AEQXKSLgMt8YB%2FIMG_9150.JPG?alt=media&amp;token=b0354ca8-74ce-4790-aa03-ed48a7c431bd" alt="" width="375"><figcaption></figcaption></figure></div>

Doodle empowers you to express yourself visually and share your creations with the world.


# Inpaint with doodle

We have introduce a doodle feature. You can draw the image you want before inpainting. Take a look at below example.

1. go to inpaint page, we can click "Edit" to draw on the image

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FeW3A1kYVa28xQ7bQY7am%2FIMG_9215.jpg?alt=media&amp;token=7ee84786-c7e3-486d-91f5-51690595af7c" alt="" width="375"><figcaption></figcaption></figure>

2. Draw on the image. In this example, we want to draw a print on her tee shirt.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FQnooLHjqVpdnkqRnD0MA%2FIMG_9207.jpg?alt=media&amp;token=776054b8-e512-4303-82a0-dc09d1a1339f" alt="" width="375"><figcaption></figcaption></figure>

3. Mask the inpainting area that we want to modify. We should set the strength to something around 0.5 so it will follow our drawing.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F7XQGa74JiG0ovrVK9VWx%2FIMG_9210.jpg?alt=media&amp;token=b63c342b-9c23-400d-b7e1-3e44ceed9aaf" alt="" width="375"><figcaption></figcaption></figure>

This is the output of our work:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fe7PkPmVQWTVv0KEGToDY%2FIMG_9211.JPG?alt=media&amp;token=245d97f5-3282-4fa6-a9aa-184493bc9e5d" alt="" width="256"><figcaption></figcaption></figure>


# Area inpaint with doodle

For smaller area, we can go for area inpaint. It will give you a better result than normal inpaint.

1. Select area we want to inpaint

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FpcHc9SGGUxznWgvK8mCn%2FIMG_9218.jpg?alt=media&amp;token=c24402de-9976-4dd5-a655-414b70931535" alt="" width="375"><figcaption></figcaption></figure>

2. Click on the Doodle button. It will direct you to the drawing page

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FwCxG64hFABBGiDRO8Quo%2FIMG_9219.jpg?alt=media&amp;token=b733eb80-57d2-4f3c-aa62-105c6dbb6758" alt="" width="375"><figcaption></figcaption></figure>

3. Draw on the area. In this example, we want add a tattoo.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FZDoV5G776leaUhjprAJv%2FIMG_9220.jpg?alt=media&amp;token=aa82e2c8-7c62-4d3c-8738-cd952499ccc8" alt="" width="375"><figcaption></figcaption></figure>

4. Remember to edit the prompt to match our drawing. We add tattoo text "dream", tattoo red heart to the prompt. We should also adjust the strength to around 0.5. It will follow what we draw.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FgRM7F1FyiplPsS3mJnXW%2FIMG_9221.jpg?alt=media&amp;token=885cb6b6-6dc1-4a0f-852e-cee0a7585edc" alt="" width="375"><figcaption></figcaption></figure>

It is recommended to perform a hires fix after that. Here is the result of our work.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fyne4uQt6sH3lpGwmYLQZ%2FIMG_9222.JPG?alt=media&amp;token=9f6bcb23-959f-4c85-9588-1668aafc00e2" alt="" width="375"><figcaption></figcaption></figure>


# Relighting

Adjust the lighting of an image to create a more dynamic and visually appealing effect.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FZE9QygKO5RraFxGM8RzM%2Frelight.gif?alt=media&amp;token=ddc80df1-2e6e-4ee8-9247-45897bd09ba1" alt=""><figcaption></figcaption></figure>

This feature allows you to change the direction of the light source in an image. You can relight your image or upload a new one.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FJTlzpKJPLqIc1xlRBhYI%2FScreenshot_20240601_062627~2.jpg?alt=media&amp;token=ec82ffde-e667-4e57-a6e5-12a6c741ccc5" alt="" width="375"><figcaption><p>Upload a new image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FaZoz3iMrN8N99zTvJDJ1%2FScreenshot_20240601_063631~2.jpg?alt=media&amp;token=28cc91c1-dd9b-4c8b-9c15-31b95d1b3603" alt="" width="375"><figcaption><p>Relight existing image</p></figcaption></figure></div>

Next, enter prompt of the light. For examples, sunset / neon light / soft lighting / dark atmosphere / spot light etc

Adjust the light source direction:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F8uCgT5Tm856O1V4552aO%2FScreenshot_20240601_063011~2.jpg?alt=media&amp;token=2732b860-dce7-488b-a689-e726a6efb2c1" alt="" width="375"><figcaption></figcaption></figure>

Adjust the effect weighting:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FsYIzkVmxIZxokJodbTje%2FScreenshot_20240601_063655.jpg?alt=media&amp;token=e13b5329-939d-4484-8f8b-d1ae1def8332" alt="" width="375"><figcaption></figcaption></figure>

Hi the "Start now" button and check the results

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FpBRhqUX3lwa9XZ9UIZhI%2F3lBCTU8iX8a9PXuGE5T6_0.png?alt=media&amp;token=c91d9300-76cf-4833-b8eb-4c4c93592002" alt="" width="375"><figcaption><p>Input image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FWcEq9gRNY2FKfO7hdTeI%2F1717151449297.jpg?alt=media&amp;token=bcf21721-4c15-423d-ae1b-1f8cdbb5c017" alt=""><figcaption><p>result</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F2cbyHpQvZqYf5QFOP3wu%2F0iwL9igxJgN6It4NHIvB3nale0g1_gxh0bQWtultAoRqMv3CJ_0.webp?alt=media&amp;token=18fb572c-515a-46e8-9ae9-f18dc3ab98c9" alt=""><figcaption><p>result</p></figcaption></figure></div>

You can also relight anime image:

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FrPVyxN6T03ZKHrL3rQRD%2FUmRoHkSMzOq67dt5uinY_0.png?alt=media&amp;token=28dc926c-9a28-48f9-af8d-7e6f794153b0" alt="" width="375"><figcaption><p>Input image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FDfS9SmQ81MBWJVJ93Q6S%2F8aG554m0GMVfACBqx07H_0.png?alt=media&amp;token=c5a9eeee-7870-4267-881d-4273376f1a3b" alt=""><figcaption><p>result</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F2ywk4en9zzIc6Um0KGUh%2FK2SVidGP4wd5OID1B59P_1.png?alt=media&amp;token=ff6dd671-9b1c-401b-b9f7-e26af7b9cc26" alt=""><figcaption><p>result</p></figcaption></figure></div>


# Face Swap

Apply a facial feature from one image to another

This innovative tool allows users to seamlessly exchange faces in photos with just a few taps.

First, you will see a face swap buttons at the bottom in your artwork page

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FcD0hjR2K9Z1B3Fmt1v6t%2FIMG_0875.jpg?alt=media&amp;token=06dd37b7-bdbc-4377-8983-9dd5e904cf07" alt="" width="375"><figcaption></figcaption></figure>

Upload a face image and select the face that you want to apply. Then click "Swap now"

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FGmYrTD68jWqnpFyVJzsj%2FIMG_0876.jpg?alt=media&amp;token=81e5ba37-1b62-49a0-9fa7-dbcbe0362c17" alt="" width="375"><figcaption></figcaption></figure>

These are the result images by applying different faces.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FxoCoIatHBuEPXgTPwATb%2F77MDskBXtqjApQQ3dU91_0.png?alt=media&amp;token=063991ed-c8e6-436d-8d97-3df9e52344fe" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FXN2ntff6KXhVJstuI3II%2FAGrf4eYXgGoVmyjOlRTC_0.png?alt=media&amp;token=2da9b92a-0e23-448e-9ea4-b8359b968b94" alt="" width="375"><figcaption></figcaption></figure></div>


# 3D Parallax effect

Turn 2D images into 3D parallax effect video

Enhance your images with stunning 3D parallax effects! Follow these simple steps:

### Where to Find 3D Parallax

* Navigate to the **Tools Page** or scroll to the bottom of the **Image Page**.
* Choose an image from your device.
* Alternatively, use an image generated within the app.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FOUVN0065Kre9JRWyy33d%2FIMG_0993.jpg?alt=media&amp;token=c17e672f-8287-4f0d-af8d-faf1f64cb368" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F3gfjSkf40KwFCAmfYFbZ%2FIMG_0997.jpg?alt=media&amp;token=3cc99152-c913-4e0e-b676-1b0867814be1" alt="" width="375"><figcaption></figcaption></figure></div>

### Customizing Your Parallax Effect

1. **Select Camera Motion**:
   * Pick the camera motion style that appeals to you.
2. **Adjust Parameters**:

   * **Motion Strength**: Set how pronounced the effect will be.
   * **FPS (Frames Per Second)**: Adjust the speed of the motion.
   * **Loop**: Choose whether the effect should repeat.

   <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FjauS7UiocOSAxI2cTm4u%2FIMG_0998.jpg?alt=media&amp;token=7db66fb9-3df0-4c84-a841-9a5dfbf2aee2" alt="" width="375"><figcaption></figcaption></figure>

### Generating Your 3D Parallax

* Once you’ve set your preferences, click the **Start Now** button to generate your 3D parallax effect!

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FwcBHMmkrn0CU7MKSagi5%2Fef7415e0-875f-11ef-a315-bbd44ec19b94_1728603200254.GIF?alt=media&amp;token=e79678de-b0f0-4a70-9b39-9cf77bb085a8" alt=""><figcaption><p>The final result</p></figcaption></figure>


# In-context transfer

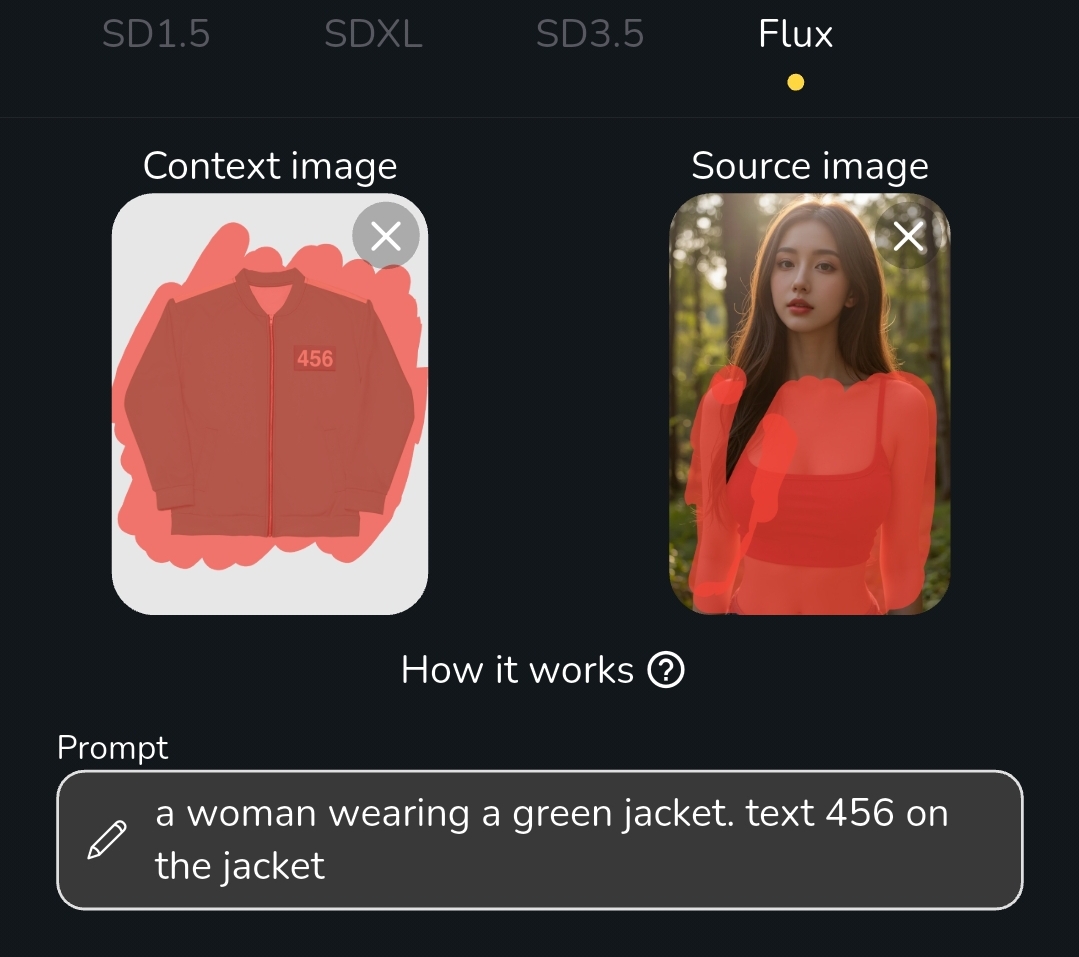
In-Context Transfer allows users to edit images intelligently by leveraging the context of existing visual elements. By using a reference image, users can seamlessly integrate new elements or modify existing ones, ensuring that changes are harmoniously blended into the overall composition.

### **How to use**

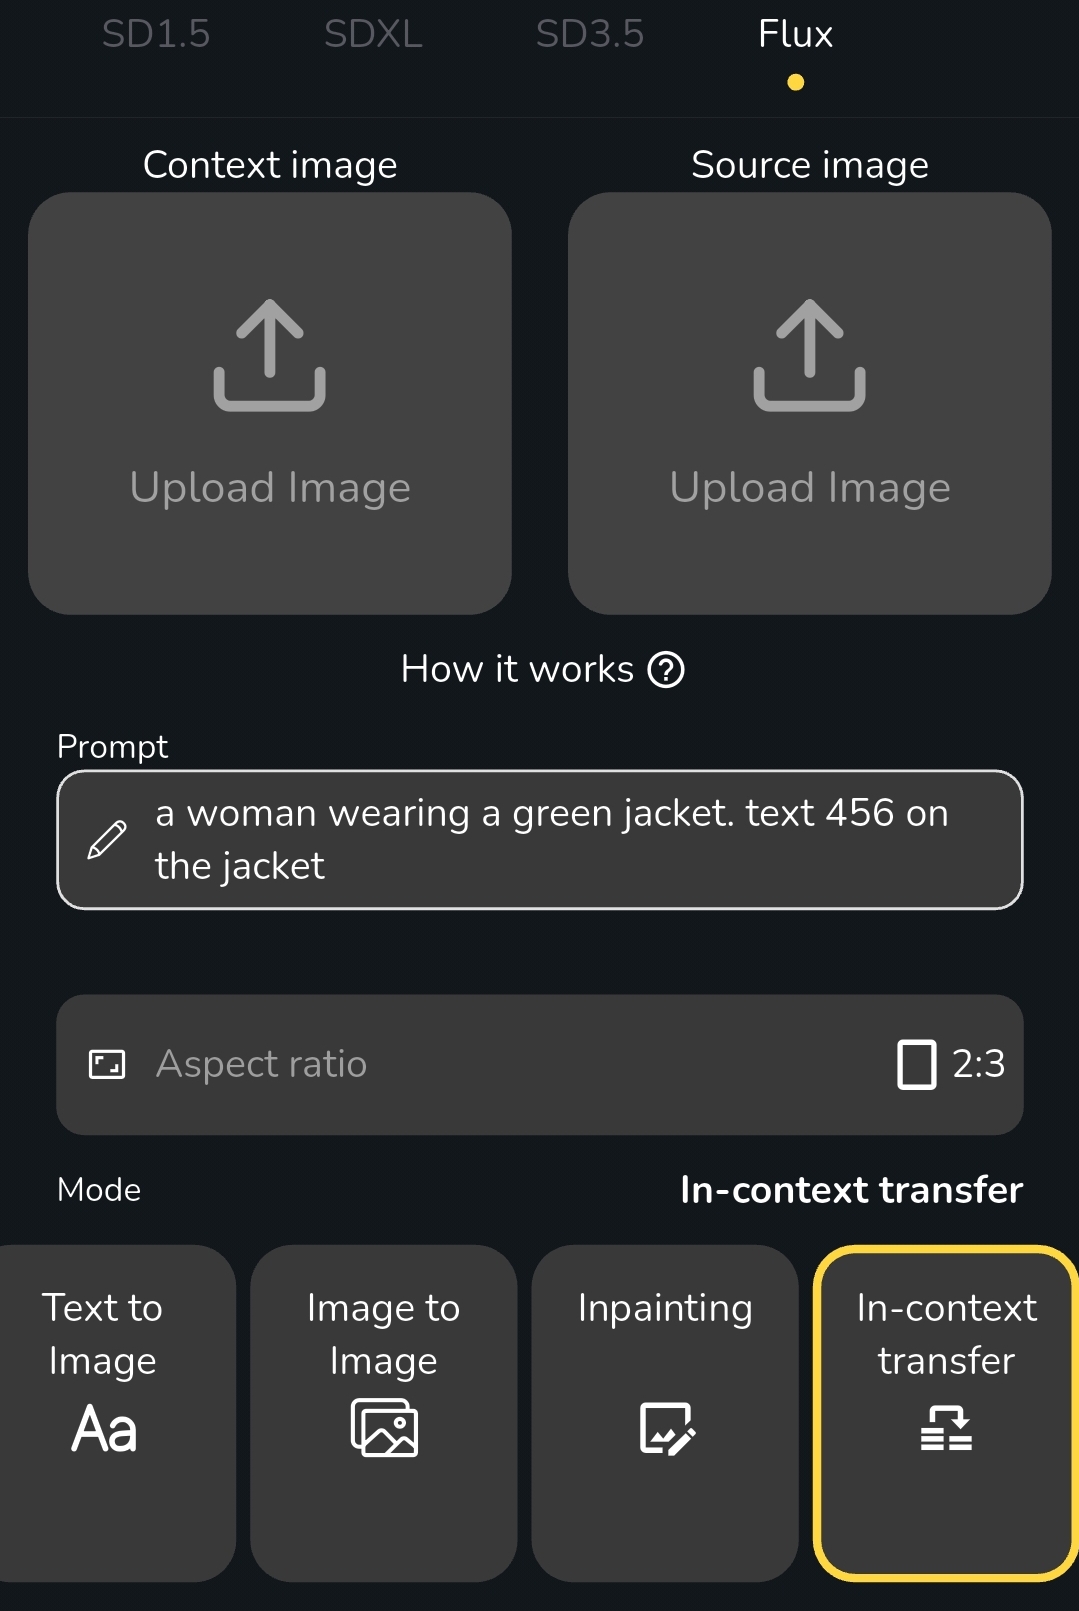
<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FdrI1bZWGTiTQp5BKtHGC%2FScreenshot_20250129_054934.jpg?alt=media&amp;token=c4fbaf1e-bc3b-432a-aa07-bd80fb1f4391" alt="" width="375"><figcaption></figcaption></figure>

* **Go to Flux model and select In-context transfer mode**
* **Upload Your Source Image**: Start by selecting the image you’d like to modify.&#x20;
* **Choose a Context Image**: Select an image that represents the style or elements you wish to incorporate.
* **Draw the Inpainting Area**: Highlight the section of your source image where you want to apply the inpainting.
* **Draw the area that you want to transfer:** Highlight the section of your context image where you want to transfer to the source image
* **Enter the prompt to describe your desired output, it also work if you leave it blank**

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FS3UGsq8S8AbSyr9uLUnW%2FScreenshot_20250129_055148.jpg?alt=media&amp;token=bb333de5-d96a-4eb1-b2d3-90bb51ec05e0" alt="" width="375"><figcaption></figcaption></figure>

Hit the Start Drawing button and wait for the result:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FO9WD3QjXBy6lOS5zkO6r%2F1738012370913.jpg?alt=media&amp;token=cfc669b8-5163-42c6-8b97-1e5caae2cdd6" alt="" width="375"><figcaption></figcaption></figure>

### Other examples

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FLVndCwAyiR4Y7yDmWWKJ%2Fezgif-5d4d91c5dd8eb.webp?alt=media&amp;token=3332d4b2-e8fa-4ab4-a354-69d5cd8470de" alt=""><figcaption></figcaption></figure>

It also work on anime image

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fn9j3Liyzpe9m6NMrXfUA%2Fezgif-54cbf1d9e4d9e.webp?alt=media&amp;token=c49831c4-26a1-44ab-8adf-e541140d8307" alt=""><figcaption></figcaption></figure>

You can transfer anything

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FcMCfUZmOQtur5UVtA2VV%2Fezgif-5ff1693a3c4a1.webp?alt=media&amp;token=20c8b677-9746-45aa-a936-3e02b240ff78" alt=""><figcaption></figcaption></figure>


# Elements

We’re thrilled to introduce **Elements**, our latest feature that empowers you to create truly unique visuals by blending and customizing different image elements.  This feature gives you the freedom to mix, match, and modify various elements—colors, textures, shapes, and more—to craft images that perfectly match your vision.

With **Elements**, you can:

* **Combine multiple image elements** to build dynamic compositions.
* **Adjust styles, effects, and layouts** for a personalized touch.

### **Subject**

Generate high-fidelity images of characters, objects, or animals while preserving key details. Perfect for consistent branding, character design, and product visuals, this feature ensures accuracy and identity retention.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNMpOvsHuA4QR4hRInwO1%2F1742580413186.jpg?alt=media&amp;token=3881a704-4b1f-4078-a9f6-1652a0c49ea3" alt="" width="375"><figcaption><p>Element image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FXvUMUVHV4mKKsJTsKkwb%2FScreenshot_20250608_024017.jpg?alt=media&amp;token=d182f114-739b-4847-9367-e4a909ede3d7" alt="" width="375"><figcaption><p>Subject mode</p></figcaption></figure></div>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FBeItiDoRqCDCZTh0rQ9k%2F8semTDeFO7oM7kabcJps_0.png?alt=media&amp;token=15e1baa9-96a6-427e-95fe-600ebc68eae3" alt=""><figcaption><p>A woman playing guitar on stage, neon text "Dreamer" in background</p></figcaption></figure>

### Face

This mode focuses solely on facial feature. Perfect for consistent face.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F22Hr3S5XzD9iy8l5k5dd%2Fbefunky-collage-2-1651824650.jpg?alt=media&amp;token=dd60a278-1729-45c5-ab42-e60a3a8054ac" alt="" width="320"><figcaption><p>Element image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FnqSwPuuYBYJdr9joRX1J%2FScreenshot_20250608_030005.jpg?alt=media&amp;token=9a519e12-b46c-449d-b2d2-cfb2648a2a0a" alt="" width="375"><figcaption><p>Face mode</p></figcaption></figure></div>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F2ug04FBwNGlMNs5FQu3H%2FtHQH8jpNnnWbiVJl4LYc_1.png?alt=media&amp;token=1e6479f0-9f30-403e-8102-2b14b8aa82df" alt=""><figcaption><p>portrait, made of sculpture, white color</p></figcaption></figure>

### Combine elements

Combine multiple elements image (maximum 3) into one image.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FD1RZLeSI9KNI5eKX4t65%2F1742580413186.jpg?alt=media&amp;token=4044054d-d5b5-405c-afad-d8e9c30449c0" alt="" width="375"><figcaption><p>Element image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FyDpaiD2EmdpuC0QttvlU%2F100_dfdf593d-bc73-4bb5-8d23-9181d510f628_480x480.webp?alt=media&amp;token=4ab7ee98-8ded-4203-a956-b3d171099360" alt="" width="240"><figcaption><p>Element image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FjI7aJwcVqjkP25AHa4xJ%2FScreenshot_20250608_030803.jpg?alt=media&amp;token=771054d1-de53-4f91-85a6-b06730b479e7" alt="" width="375"><figcaption><p>Multiple elements</p></figcaption></figure></div>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FCVKuIoonBT6NHKrbL1kb%2FMDzict1cA59YnSAANSyN_0.png?alt=media&amp;token=9766e3be-19bc-4e14-8058-59a73d70b356" alt=""><figcaption><p>a woman holding a doll with both hands in living room</p></figcaption></figure>


# Qwen Image Edit

Qwen Image Edit extends the capabilities of Qwen-Image into the realm of image editing.You no longer need to draw a mask to inpaint an image. Simply provide an instruction, and your image will be ready.

#### Key Features:

* **Semantic and Appearance Editing**: Offers both detailed visual edits—like adding, removing, or modifying specific elements while leaving other areas untouched—and broader semantic changes such as intellectual property creation, object rotation, and style transfer, ensuring semantic consistency even when pixels are altered.
* **Precise Text Editing**: Supports precise text manipulations in both Chinese and English, enabling direct text additions, deletions, and modifications while preserving the original font, size, and style of the image.

### Get start

<table data-view="cards"><thead><tr><th></th><th></th><th data-hidden data-card-target data-type="content-ref"></th><th data-hidden data-card-cover data-type="image">Cover image</th><th data-hidden data-type="content-ref"></th></tr></thead><tbody><tr><td>Single element</td><td>Edit 1 image with a prompt</td><td><a href="/image/qwen-image-edit#how-it-works">Qwen Image Edit</a></td><td><a href="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fj3n8jPtEPC5i4YMRmxKg%2FwEYoEM6eDY32VYhKnUvR_0.png?alt=media&amp;token=068514f7-5674-403c-ab65-7fabacf4aa07">wEYoEM6eDY32VYhKnUvR_0.png</a></td><td><a href="/image/qwen-image-edit#how-it-works">Qwen Image Edit</a></td></tr><tr><td>Multiple elements</td><td>Adding more than 1 image</td><td><a href="/image/qwen-image-edit/multiple-elements">Multiple elements</a></td><td><a href="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FXkE1vHjoIHrojD8xJJiE%2Fresult1.jpg?alt=media&amp;token=20aed5bd-1302-453e-9dce-09f60ff178c7">result1.jpg</a></td><td><a href="/image/qwen-image-edit/multiple-elements">Multiple elements</a></td></tr><tr><td>Blending elements</td><td>Placing elements on base image</td><td><a href="/image/qwen-image-edit/blending-elements">Blending elements</a></td><td><a href="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FOkJDhDWNILsBrcDYfUGX%2Fa5bjELqILBZyskdwSeh5_0.png?alt=media&amp;token=d998245d-8fb7-4d70-9223-4d51804b2bd6">a5bjELqILBZyskdwSeh5_0.png</a></td><td><a href="/image/qwen-image-edit/blending-elements">Blending elements</a></td></tr><tr><td>Generative fill</td><td>Fill the missing part</td><td><a href="/image/qwen-image-edit/generative-fill">Generative fill</a></td><td><a href="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F94jyP0eWefblYygRP2v5%2Fdl_1756841037283.jpg?alt=media&amp;token=27a04d1c-979d-4674-938a-913a9977cef9">dl_1756841037283.jpg</a></td><td></td></tr><tr><td></td><td></td><td></td><td></td><td></td></tr></tbody></table>

### How it works

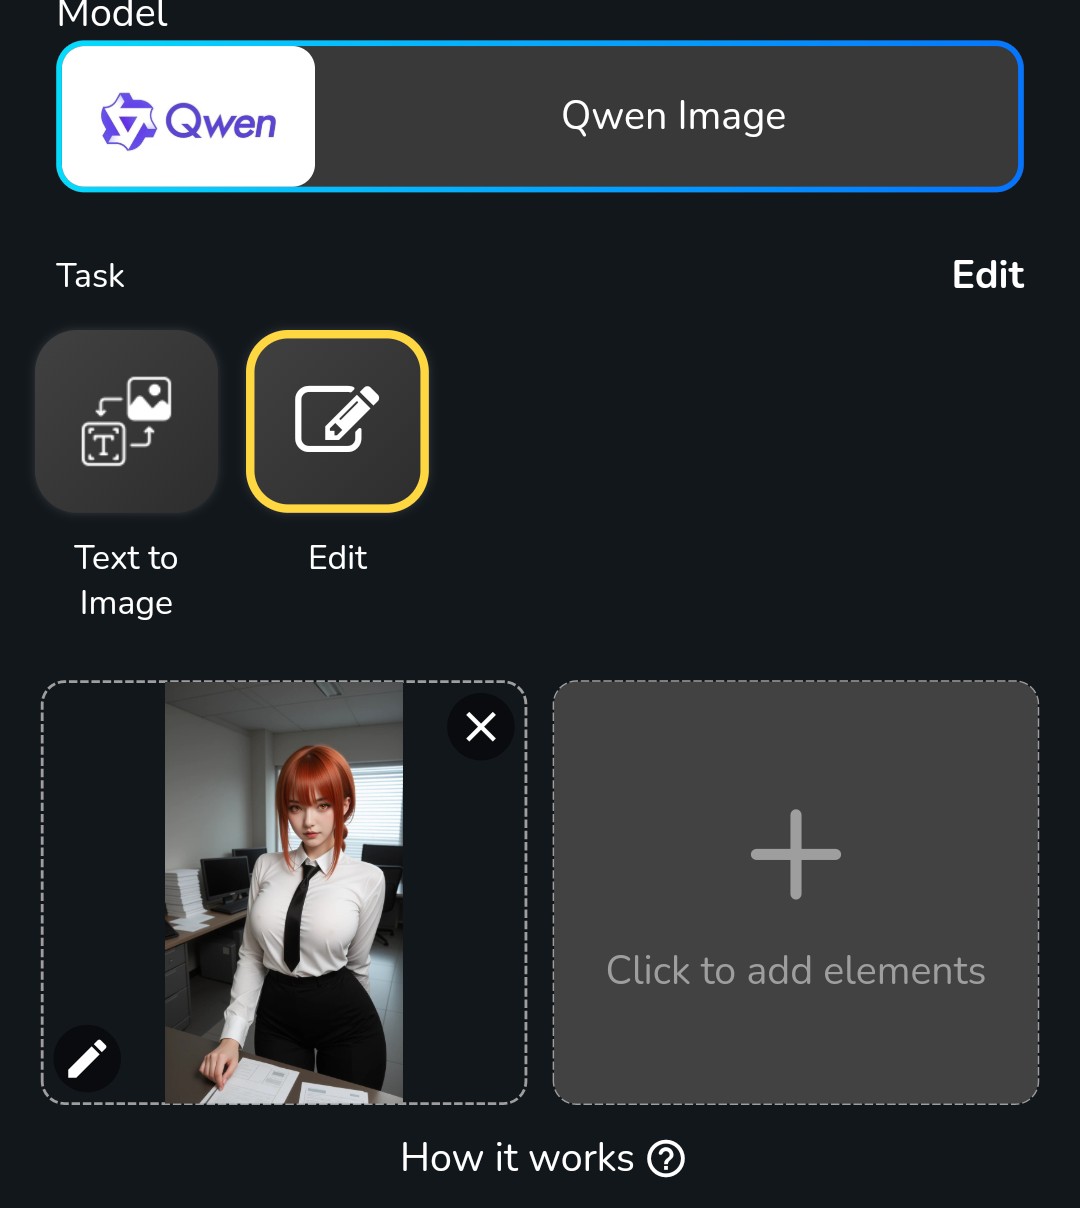
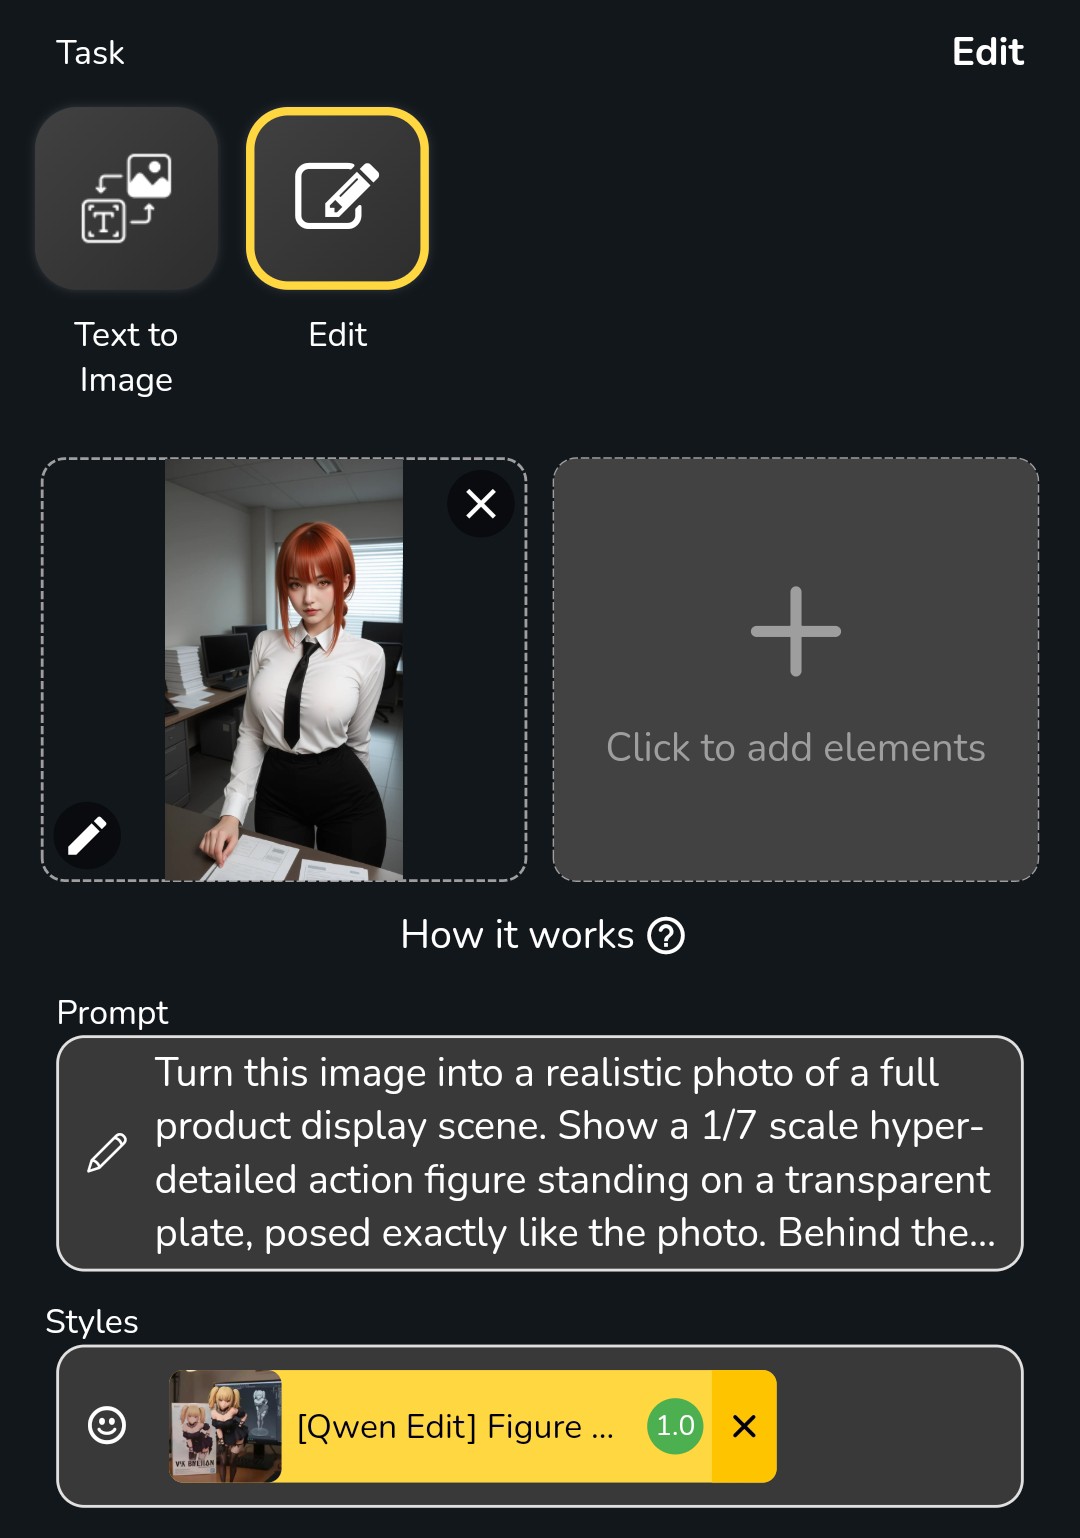
1. Upload a image that you want to edit
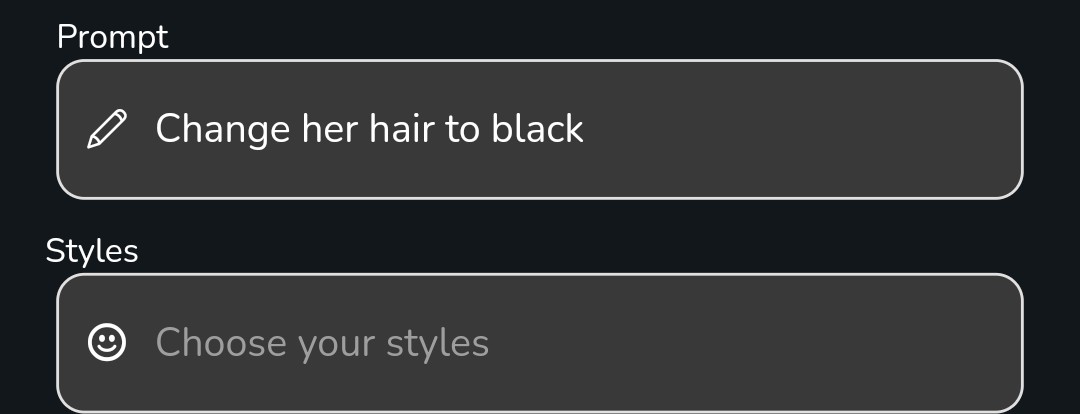
2. Enter a instruction prompt
3. Select styles (optional)
4. Wait for the output

Let's walk through an example:

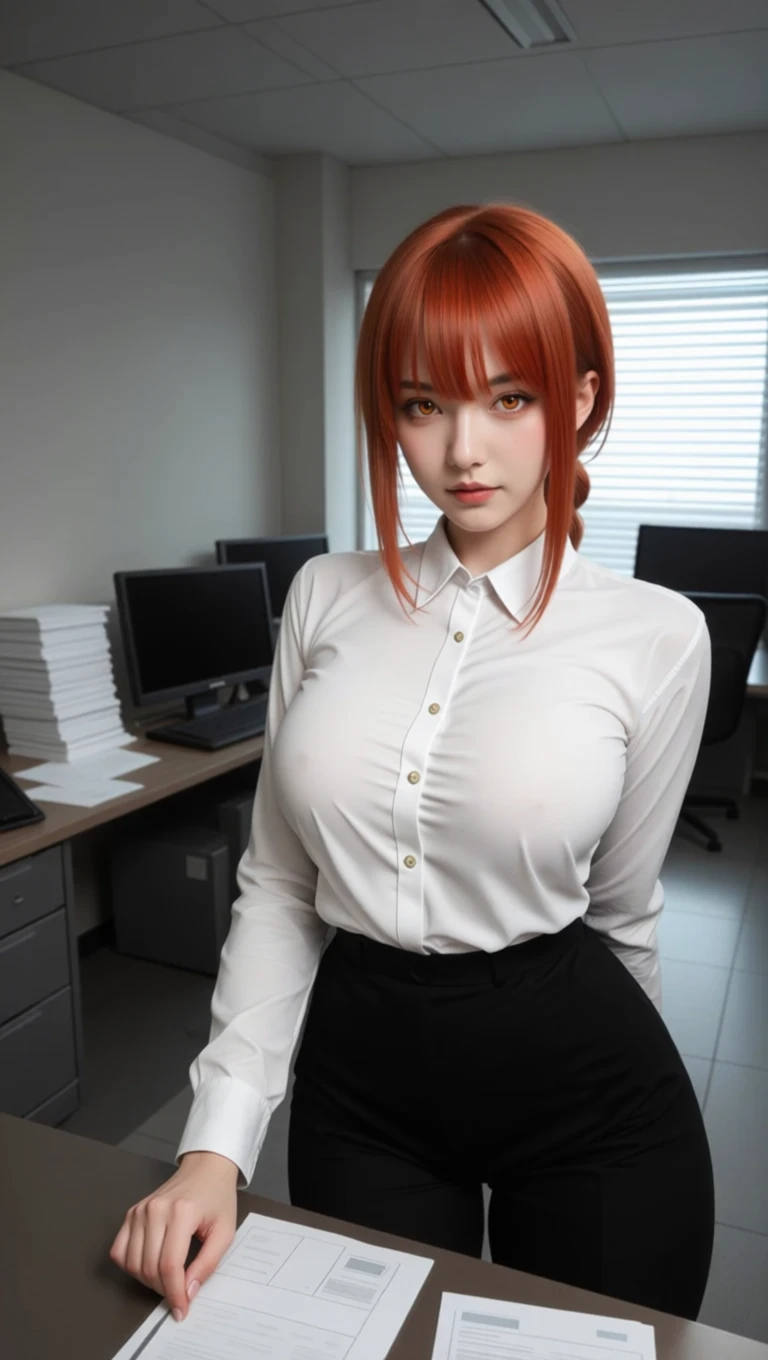
1. First we input this image for editing

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F3pTQ90bgEMbME1YYD51t%2FskwaGuY7zjFNyhO6Kvpj_1.png?alt=media&amp;token=1079ce49-0db9-42e0-85e9-e4727771fd06" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FFFP62hJJEFfCSCzNXqWM%2FScreenshot_20250901_045608.jpg?alt=media&amp;token=f7440fad-5198-4ca4-84ef-a48220add585" alt="" width="375"><figcaption></figcaption></figure></div>

2. Type the prompt as instruction

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FfVDZgIJf52sNEL3KvN3k%2FScreenshot_20250901_060306.jpg?alt=media&amp;token=62491ac7-c093-4327-80f9-476adb5f9caa" alt="" width="375"><figcaption></figcaption></figure>

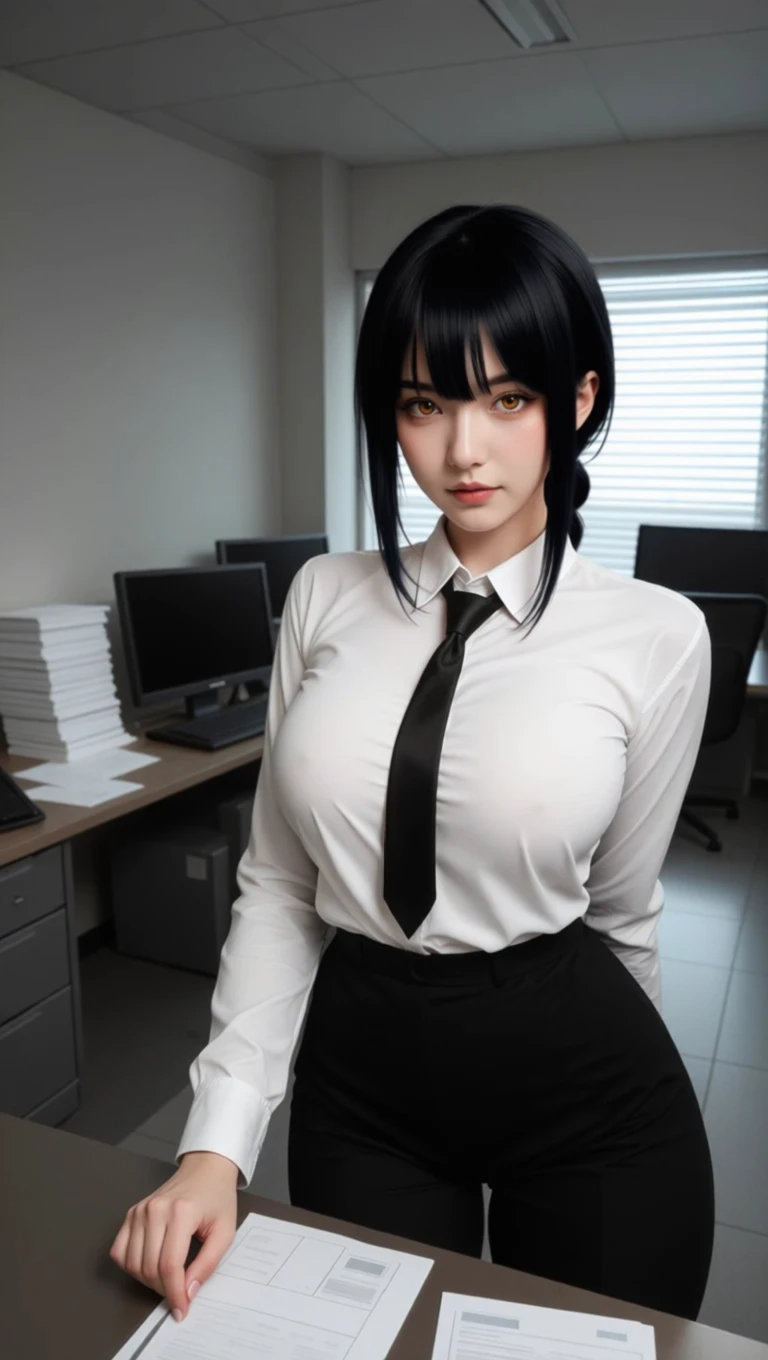
Below are the results of different prompt

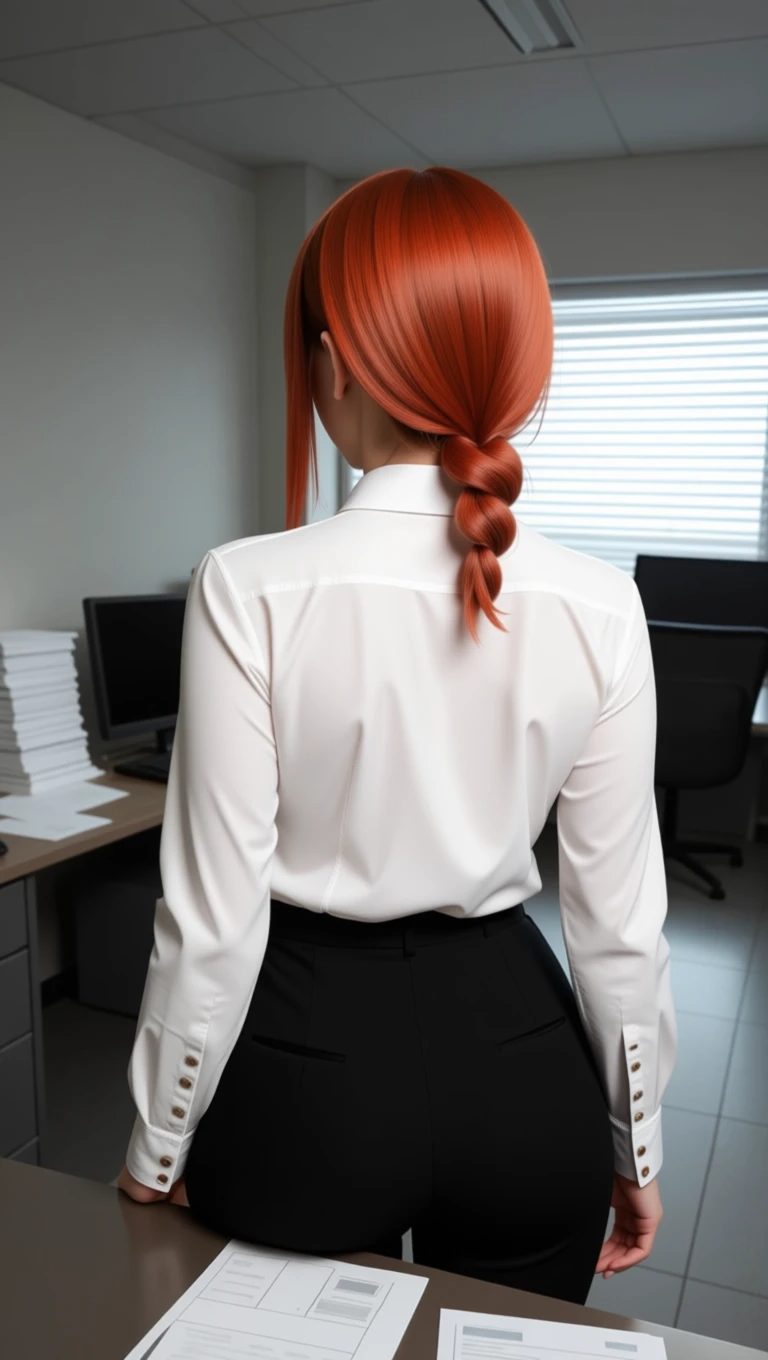
<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FlSpbfRRuZVkiI5cdfFM6%2FnvouG4NHmeRBRSzpTA2v_1.png?alt=media&amp;token=ec18d726-79f4-427b-a75a-b67531293974" alt=""><figcaption><p>Change her hair to black</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPR9aAIwUzRPh1leYorUf%2Fm44WDIYPtTsOVk0A6LeH_0.png?alt=media&amp;token=dddfbb82-6055-47a2-80ac-90726b93b9a8" alt=""><figcaption><p>Remove her necktie</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fkgo3qVDQwqeZSuTCNK1C%2FiIYhQeKE3upgbUT4ZJPL_0.png?alt=media&amp;token=42576699-22ad-4084-9fca-43feaa160113" alt=""><figcaption><p>Turn to her back view</p></figcaption></figure></div>

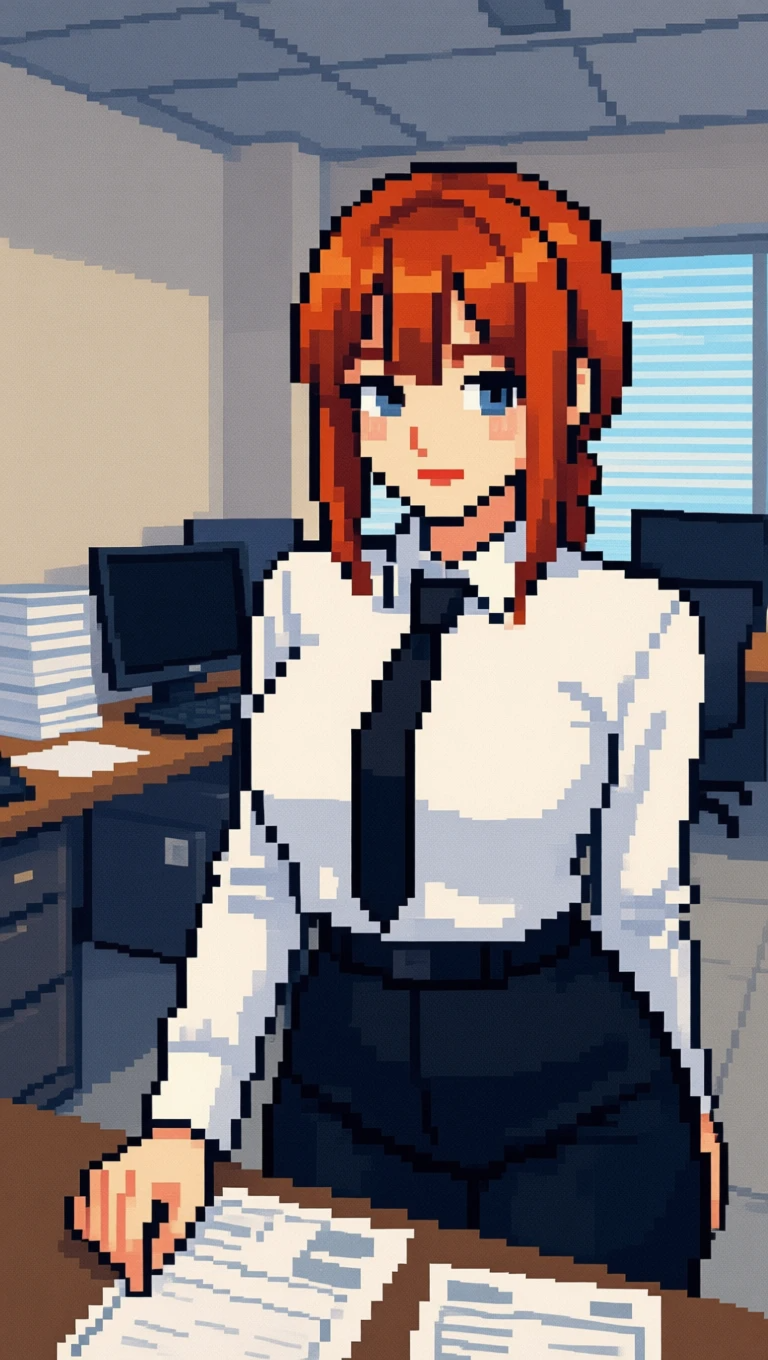
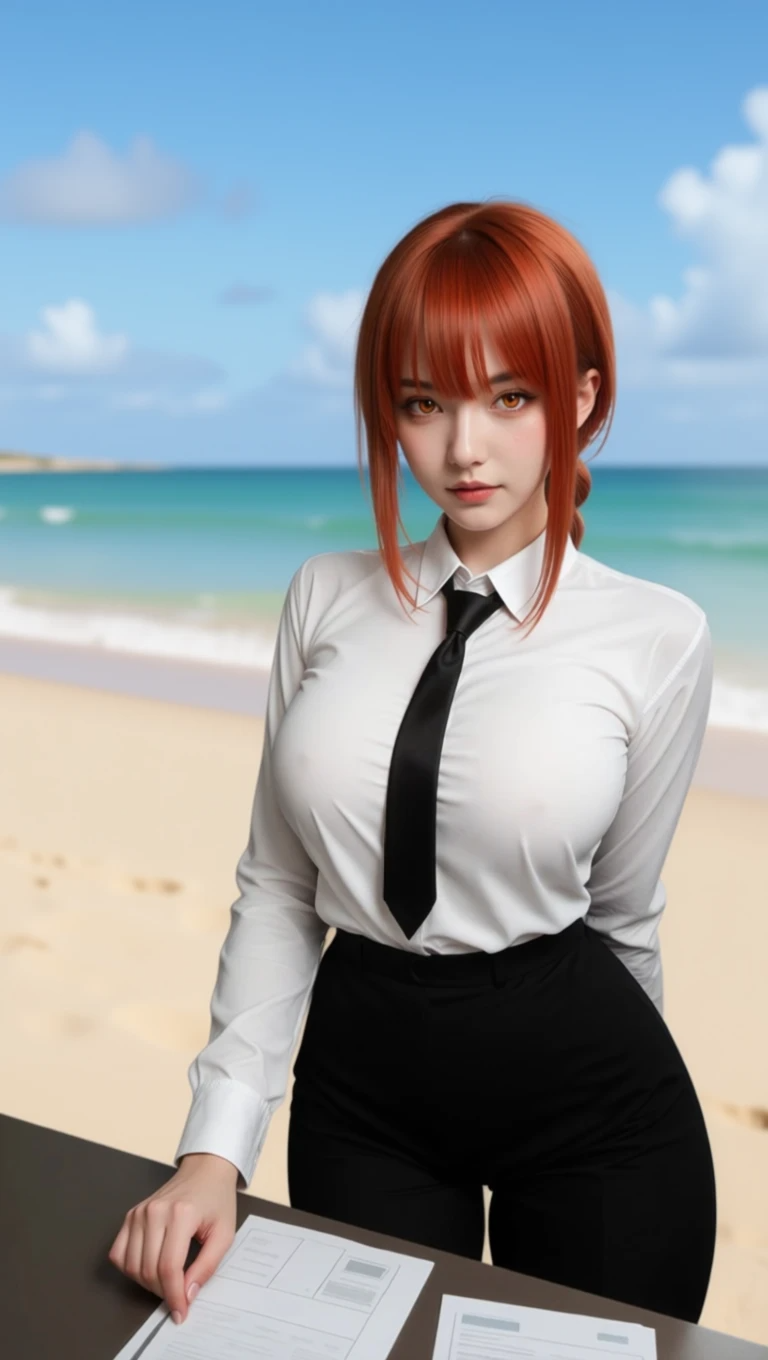
<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FLDc3qoxtU7553JNFintC%2FeMQPOgtgO7ccosuvFlal_1.png?alt=media&amp;token=95ecad3a-7224-4167-b109-89ebd25b9418" alt="" width="375"><figcaption><p>Turn into 8bit pixel style</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FvVwV1bq5TdoK06sFWfe3%2FH884b960x0Ao65fLmYrN_0.png?alt=media&amp;token=29c3e15e-6b76-4d7f-aa7c-bbe06007ac1e" alt="" width="375"><figcaption><p>Change the background to beach</p></figcaption></figure></div>

3. We can also select a community style for different concept

For example, we select the figure maker style. We used the default trigger prompt. Here is the result.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNEck8Vp8tXesyYdoVljL%2FScreenshot_20250901_061537.jpg?alt=media&amp;token=c5fe50d2-f1e9-4d61-8c42-71dd0fbb68b1" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fj3n8jPtEPC5i4YMRmxKg%2FwEYoEM6eDY32VYhKnUvR_0.png?alt=media&amp;token=068514f7-5674-403c-ab65-7fabacf4aa07" alt="" width="375"><figcaption></figcaption></figure></div>

Editing an image has never been easier. The result is impressive.


# Multiple elements

You can add more than 1 element in Qwen Image Edit.&#x20;

### How it works

1. Add two or three images in elements.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FIaOVblDy3DaRSMahjTe2%2FScreenshot_20251002_041623.jpg?alt=media&amp;token=88df3582-f5f2-4093-b8c4-22fd2c4a70c7" alt="" width="375"><figcaption></figcaption></figure>

2. Write a instruction prompt to tell AI how to combine two images.&#x20;

<mark style="color:yellow;">Tips of writing prompt:</mark>

* You should tell the AI what subject you are referring to. In this example, the girl is on image 1 and the sword is on image 2. so we write <mark style="color:yellow;">"make the girl on image 1 holding the sword on image 2"</mark>. If you have three elements, you can specify the subject on the image 1, image 2, or image 3.

3. That's it. Hit the Draw button and wait for the output. Below is the final output and it looks perfect

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FXkE1vHjoIHrojD8xJJiE%2Fresult1.jpg?alt=media&amp;token=20aed5bd-1302-453e-9dce-09f60ff178c7" alt="" width="375"><figcaption></figcaption></figure>


# Blending elements

Another usage is to use Lora to blend different elements.&#x20;

For better consistency, you can use "Put it here" Lora to do this.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FZjpNNhW8Z4rRHu5OvzyA%2Fimage.png?alt=media&amp;token=cb841ce2-ea1a-46e5-ad4c-a513e9472e5a" alt=""><figcaption></figcaption></figure>

### How it works

1. Upload a base image and click the edit button on the bottom left

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fd9ZvNbn7C8OIlgJWoxJs%2FScreenshot_20250901_175231~2.jpg?alt=media&amp;token=02f87225-b303-48bf-8654-383a5c45a11e" alt="" width="375"><figcaption></figcaption></figure>

2. Click the "Add Image" button to add elements on top of the base image. Position the elements where you want them to be applied. For example, we want to change her clothes to a bikini, so we place the bikini image on her body.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fisd1Toi6Nlvl0DTM9KTF%2FScreenshot_20250901_185915~2.jpg?alt=media&amp;token=3937f3ff-104b-4e44-aa49-efda946ec590" alt="" width="375"><figcaption></figcaption></figure>

3. Select "Put it here" style and write a instruction prompt.&#x20;

   <mark style="color:yellow;">Tips of writing prompt:</mark>

   1. You should tell the AI what to do. In this example,&#x20;

      we want to remove the white area of the bikini image

      we want to remove her clothes

      we want to replace her clothes to this flag bikini\
      so the prompt is "remove white area, remove her clothes, change her clothes to flag bikini"
   2. Describe the final output. In this example, The final output is a girl wearing bikini
   3. The "Put it here" style is to maintain consistency in image editing, although it is optional.&#x20;
4. That's it. Hit the Draw button and wait for the output. Below is the final output and it looks perfect. Details of the bikini and person remain consistent.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FOkJDhDWNILsBrcDYfUGX%2Fa5bjELqILBZyskdwSeh5_0.png?alt=media&amp;token=d998245d-8fb7-4d70-9223-4d51804b2bd6" alt="" width="375"><figcaption></figcaption></figure>

Here are output of with and without "Put it here" Lora. You can see the difference in consistency of the bikini.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FOkJDhDWNILsBrcDYfUGX%2Fa5bjELqILBZyskdwSeh5_0.png?alt=media&amp;token=d998245d-8fb7-4d70-9223-4d51804b2bd6" alt="" width="375"><figcaption><p>With lora</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNz1EQXVHxoDQ7u3ioCgW%2FEMr8xYJJ2tDuLv1Keeyq_0.png?alt=media&amp;token=3e138b26-3197-430e-8a13-b6153080211d" alt="" width="375"><figcaption><p>Without lora</p></figcaption></figure></div>


# Generative fill

You can inpaint and outpaint with Generative fill lora. It will fill the missing part of the image.

### Inpaint

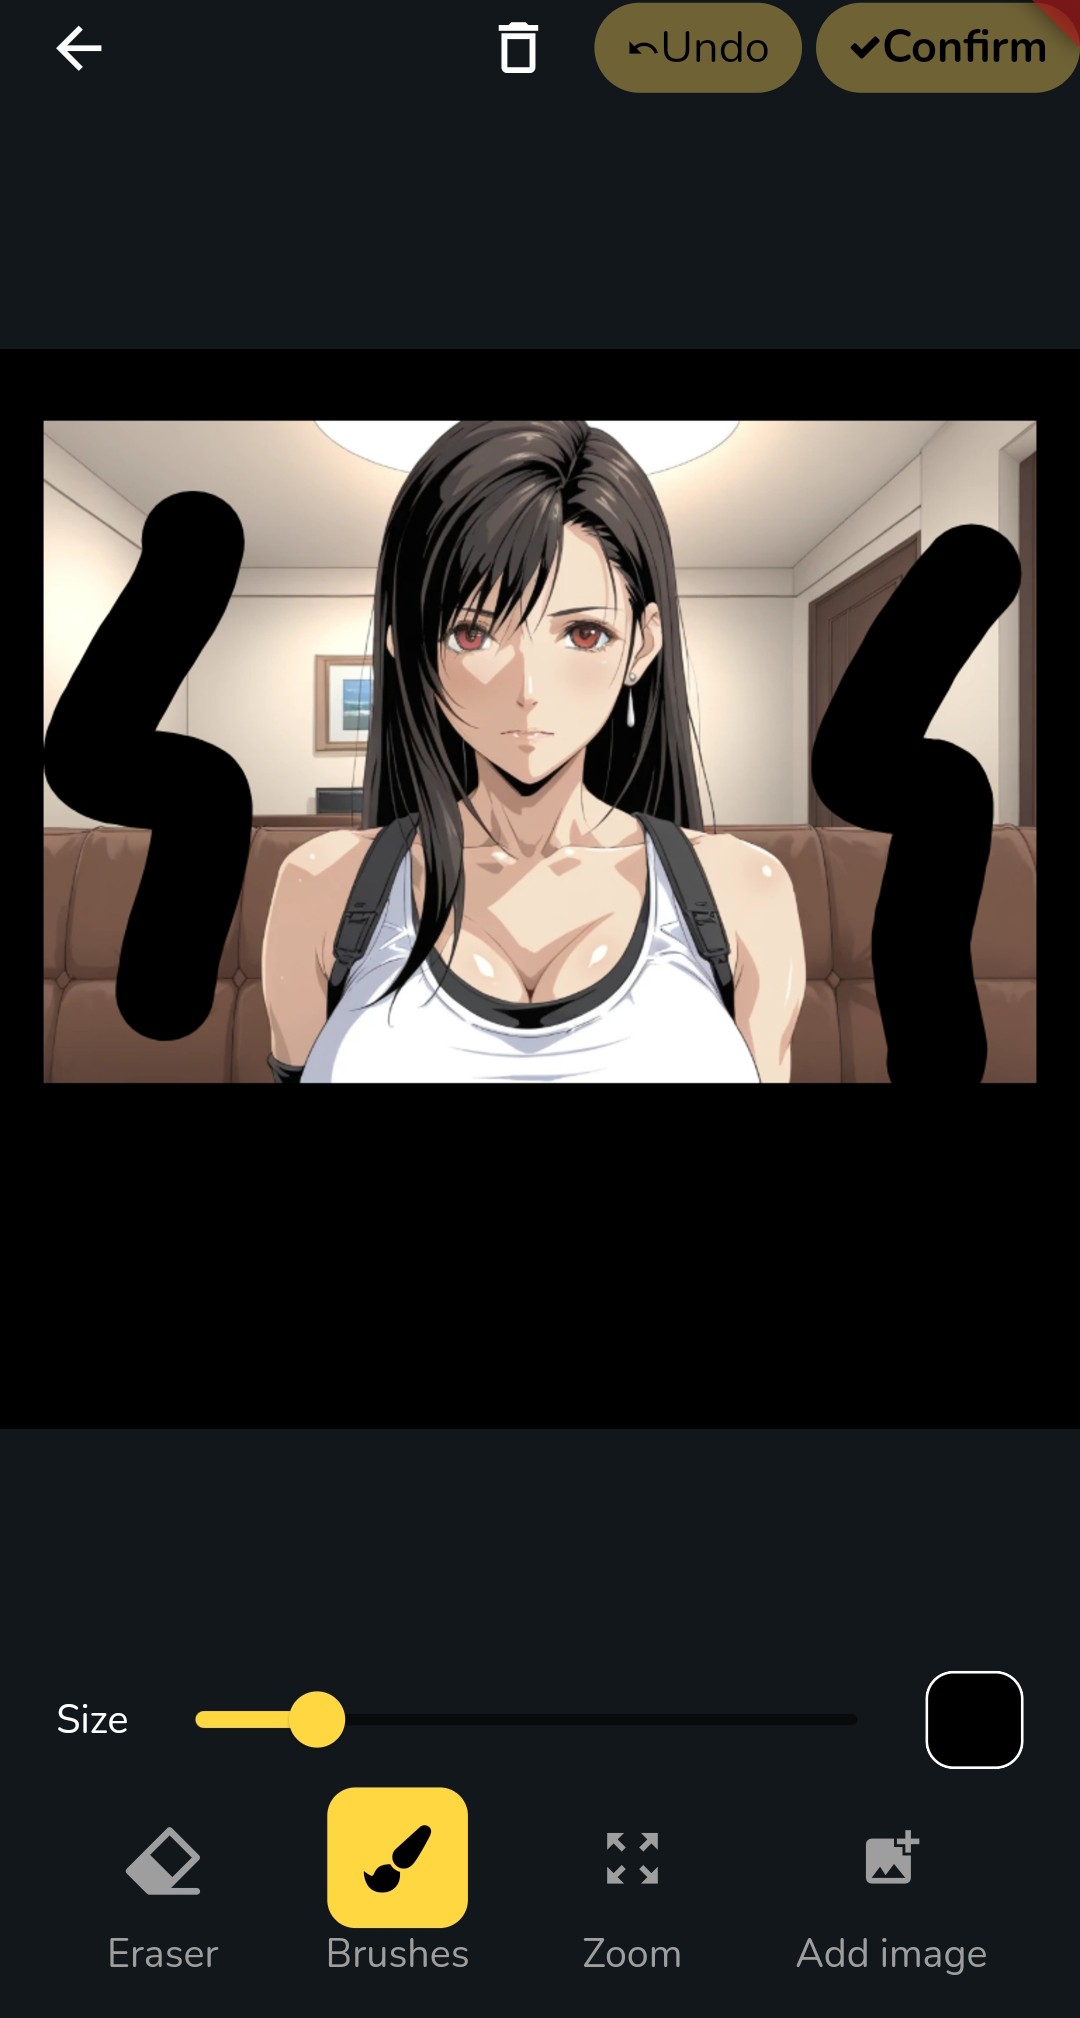
1. Upload a image and draw black color on area you want to inpaint. For example, we want to fix the hands of this image

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FK5AkWAmqencfbbRLcSty%2Fdl_1756767828011.jpg?alt=media&amp;token=d22094da-25dc-462d-a1e7-07337a64a334" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FmASj64sKmlxNBznBVVV1%2FScreenshot_20250903_030857~2.jpg?alt=media&amp;token=1a3374c0-52b9-4aa7-a8d5-c7b68df87810" alt="" width="375"><figcaption><p>Click the edit image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FbadMfynfBkHXwOQK5Q0V%2FScreenshot_20250903_030633.jpg?alt=media&amp;token=c9fd8960-cf2c-465c-bd4e-ee78cbafce0e" alt="" width="375"><figcaption><p>Draw on the image</p></figcaption></figure></div>

2. Select the generative fill style and write the prompt to describe your desired output.&#x20;
3. &#x20;Click Draw and That's it.&#x20;

Result:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F94jyP0eWefblYygRP2v5%2Fdl_1756841037283.jpg?alt=media&amp;token=27a04d1c-979d-4674-938a-913a9977cef9" alt="" width="375"><figcaption></figcaption></figure>

### Outpaint

1. Upload a black image or upload a random image and draw it to all black. Add image to the canvas

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPsTH2KSwvkhiIWX9vi5z%2FScreenshot_20250903_030045.jpg?alt=media&amp;token=87b49e51-b4f6-47af-a2e1-1bacc75543bc" alt="" width="375"><figcaption></figcaption></figure>

2. Select the generative fill style and write the prompt to describe your desired output.
3. Click Draw and That's it.

Result:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fg2niFBKATwjkbAO79f6p%2Feb7oHpXozcqHQyoLcyHb_0.png?alt=media&amp;token=5895be76-2390-4b6f-924f-a7f05b0f031f" alt="" width="375"><figcaption></figcaption></figure>


# Edit with mask

To edit a specific area of an image while keeping the rest untouched, you can use a mask. By drawing over the target area, you define exactly where the AI should apply changes and where it should remain unchanged.

When an image contains multiple subjects, such as a group of people, editing just one via text prompts alone can be challenging, as the AI may inadvertently alter others. By using a mask, you provide the AI with precise spatial guidance, ensuring the modifications are restricted only to your selected subject.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FmLKaXOzRbiMamGHI1WGi%2FScreenshot_20251229_030051.jpg?alt=media&amp;token=c14a6a32-37f1-46d9-8b51-a48fa52ffd1f" alt="" width="375"><figcaption></figcaption></figure>

The result is as below:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F498oGu0F2GPxqM8Dk8Yi%2FJbYWj8u7Lzj8vCDivMl8_0.png?alt=media&amp;token=24b29926-8223-4453-91e6-f43ccc581f91" alt=""><figcaption></figcaption></figure>


# Z Image

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FCZh56OylxkxfF7x7Rwrb%2Fshowcase_realistic.png?alt=media&amp;token=64a825c7-c58a-4e0d-9a9e-608dad78feed" alt=""><figcaption></figcaption></figure>

Z-Image is a powerful and highly efficient image generation model with **6B** parameters.

**Model Highlights**:

* **Photorealistic Quality**: Delivers strong photorealistic image generation while maintaining excellent aesthetic quality
* **Accurate Bilingual Text Rendering**: Excels at accurately rendering complex Chinese and English text
* **Prompt Enhancing & Reasoning**: Prompt Enhancer empowers the model with reasoning capabilities
* **Sub-second Inference**: Achieves fast generation speed on supported hardware


# Image to Video

Currently, we have three models for Image-to-Video: [**Hunyuan Video**](/video/hunyuan-video/image-to-video), [**Wan2.1 Video**](/video/wan2.1-video), and **Kling Video**. Please upgrade to the latest version to get all three models. Please visit [www.dreamerland.ai](https://docs.dreamerland.ai/video/www.dreamerland.ai) for details.

| Model         | iOS | Android (Google Play) | Android (APK) |
| ------------- | --- | --------------------- | ------------- |
| Kling         | ✅   | ✅                     | ✅             |
| Wan2.1 Video  | ✅   | ❌                     | ✅             |
| Hunyaun Video | ✅   | ✅                     | ✅             |

* **Kling Video** produces the highest-quality output but has restrictions on sensitive content and lacks LoRA support.
* [**Wan2.1 Video**](/video/wan2.1-video) is the best alternative to Kling. While its quality is slightly lower, it offers more creative freedom.
* [**Hunyuan Video**](/video/hunyuan-video/image-to-video) is the fastest among the three, generating decent video output in just 1–2 minutes. It also supports LoRA styles.


# Hunyuan Video

We are thrilled to announce the addition of Hunyuan Video to our platform! This cutting-edge text-to-video model represents a significant leap forward in the realm of video generation, and we can't wait for you to explore its incredible capabilities. Please download the latest version of Dreamerland on app store or download the latest android APK.&#x20;

### <mark style="background-color:orange;">What is Hunyuan Video?</mark>

Hunyuan Video is currently the most parameter-rich and high-performance Text-to-Video and  [Image-to-Video](/video/hunyuan-video/image-to-video) model in the open-source domain. This immense capacity enables it to generate videos with exceptional physical accuracy, remarkable scene consistency, and the ability to seamlessly transform static images into dynamic, lifelike videos. Whether starting from text or an image, Hunyuan delivers unparalleled creative possibilities.

### <mark style="background-color:orange;">**How it works**</mark>

For Image to Video feature, please refer to [Hunyaun Image to Video](/video/hunyuan-video/image-to-video)

You can find the Hunyuan Video model in the Video tab. We offer various video lengths, ranging from 2 seconds to 4 seconds. Simply input your prompt and optionally select the Lora you wish to apply for styling. The processing time for the video is approximately 1 to 2 minutes, depending on the length you choose.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FoY6XfOKu0ImY1dn9xcQd%2FIMG_1495.jpg?alt=media&amp;token=209636fa-4c07-4e57-abd7-c1b9840939d7" alt="" width="375"><figcaption></figcaption></figure>

### <mark style="background-color:orange;">Key Elements of a Good Prompt</mark>

1. **Start with the Main Subject**:
   * **Example**: "A talented guitarist strumming a classic acoustic guitar."
2. **Set the Scene**:
   * **Example**: "On a sunlit beach with gentle waves lapping at the shore."
3. **Detail the Action**:
   * **Example**: "The guitarist passionately plays a lively tune, fingers dancing over the strings."
4. **Incorporate Camera Instructions**:
   * **Example**: "The camera slowly pans from the ocean to focus on the guitarist’s expressive face."
5. **Define the Mood and Lighting**:
   * **Example**: "Golden hour sunlight bathes the scene, casting a warm glow and long shadows in the sand."

### <mark style="background-color:orange;">Tips for Crafting Vivid Scenes</mark>

1. **Choose Descriptive Language**:
   * **Weak**: "A busy city" → **Strong**: "A bustling metropolis alive with energy and color."
2. **Ensure Visual Cohesion**:
   * **Example**: Keep the lighting warm and inviting, with hues of gold and orange reflecting throughout the scene.
3. **Use Clear and Direct Descriptions**:
   * **Example**: "The camera captures a close-up of the guitarist’s hands, clearly showing the intricate finger movements on the strings."

Prompt: A sleek, silver sports car races down a winding mountain road. The backdrop features lush green hills under a clear blue sky. The camera tracks alongside the car, highlighting its speed and elegance. The bright sunlight glints off the car's surface, enhancing the thrill of the moment.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FyjlzrnUx8M1JY1P6Q6Ez%2FQcEZjBQxJLA97K7QEgVj-ezgif.com-video-to-webp-converter.webp?alt=media&amp;token=f0e9b1a9-69df-4906-8cfc-2ffdab47161e" alt=""><figcaption></figcaption></figure>

Prompt: A playful puppy chasing after a fluttering butterfly in a lush garden. The setting is filled with blooming flowers and greenery. The puppy bounds excitedly, its ears flopping with each leap. The camera follows closely, capturing the joyful energy of the chase. Sunlight sparkles off the dew on the grass, adding a magical touch to the moment.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F7u84GzPbRIlt1iOecg0v%2FiBEWXx0Zb7Jc7FCPTcHv-ezgif.com-video-to-webp-converter.webp?alt=media&amp;token=94f4010f-938e-45e2-9eb4-faeff129087b" alt=""><figcaption></figcaption></figure>

### <mark style="background-color:orange;">More Examples</mark>

Below we show some examples generated from Hunyuan Video

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fzt1X4BdzCdLS5BKbHXcE%2FL8TNoBEvjllbBtemjcfm-ezgif.com-video-to-webp-converter.webp?alt=media&amp;token=3721b6a5-2c18-4b62-b9df-9f39b84cc727" alt="" width="250"><figcaption></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fl1Qif7UzOVupd8vZUNGe%2FeaLPtFqcUU2Z5QoeoeO91-ezgif.com-video-to-webp-converter.webp?alt=media&amp;token=559f0351-fe14-438e-b90c-11092182e3c5" alt="" width="250"><figcaption></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNYlyQLJW4tr61xloQVuG%2Figg2RssDgDEj1gj4xCLI1-ezgif.com-video-to-webp-converter%20(1).webp?alt=media&amp;token=ea6db267-a381-4096-838e-2bc791dfd3ce" alt="" width="203"><figcaption></figcaption></figure>


# Image to Video

We’re excited to introduce the **Hunyuan Image-to-Video** feature in our app! This powerful tool uses AI to turn static images into dynamic videos effortlessly. Perfect for creators and storytellers, it unlocks new ways to bring your visuals to life. Elevate your content with Hunyuan Video today!

Currently, the Hunyuan Image-to-Video feature supports **start frame input** as its primary mode of operation. Simply upload your desired start frame image, and let the AI transform it into a video.&#x20;

<mark style="color:yellow;">**Tips:**</mark> For optimal results, choose the style that best aligns with the motion you envision. This approach significantly enhances the success rate and ensures greater stability in your video output, delivering smoother and more coherent results.

Not all the styles/LoRAs in the app can deliver the desired results, as most of them are specifically trained for text-to-video generation.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FqrCG9imayLo0msVz4tvL%2F1742680066158-ezgif.com-video-to-webp-converter.webp?alt=media&amp;token=174aa8c5-4f74-4edd-8cd2-129cbceb0ba3" alt=""><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FDqlajGN7LojjEJSkqyWL%2F1742680014183-ezgif.com-video-to-webp-converter.webp?alt=media&amp;token=bf37606f-df79-4595-9f27-6c0c37456ef4" alt=""><figcaption></figcaption></figure></div>

### Travel Prompt

Seamlessly blend multiple prompts in a single generation! Specify exact start times (e.g., "0:15") to control when each prompt takes effect, creating dynamic, evolving visuals. Perfect for storytelling, scene transitions, or layered artistic effects.

Example prompts as below

0s-3s: walking, 3s-5s: waving hand, 5s-7s: adjusting hair, 7s afterward: dancing&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F63W0mvpkSGlGMFz0CVB1%2FiAhMmvWQUWV6KIYNy3WB_0.png?alt=media&amp;token=d33a365e-01ff-46e5-8ba3-8d1cfdd006ef" alt="" width="375"><figcaption><p>Input image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FrGm0JVolPf4GJDno5sSw%2FScreenshot_20250608_032206.jpg?alt=media&amp;token=2b1d8b9f-900c-4051-a19e-4eb4ad1b9ec6" alt="" width="375"><figcaption><p>Travel prompt</p></figcaption></figure></div>

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fi3ptScr23Ryx0WI2WSt6%2Fv7Z9SQw8viaKCbMZqRKA_0.mp4?alt=media&token=05494c2d-47a7-43c8-a10d-78b55b6ec94b>" %}
result video
{% endembed %}


# Wan2.1 Video

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FIb09fSAV7cEi7g1MgC3V%2FJuaHDUzpq0XxF87GdMwu%20(1).mp4?alt=media&token=99c7f0aa-4f35-47a0-b507-1ff8a6c3705a>" %}

Wan2.1 is a cutting-edge open-source video generation model that outperforms both open-source and commercial solutions in benchmarks. The model excels in Text-to-Video and Image-to-Video. Notably, it’s the first video model with robust Chinese/English visual text generation. Wan2.1 combines high performance, accessibility, and multi-task versatility, advancing open-source video AI.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FEZ79u6ZJp15wYFZnJZGl%2FIMG_1974.jpg?alt=media&amp;token=91477d1a-3172-43c4-afc5-cfe6a76867c7" alt="" width="375"><figcaption></figcaption></figure>

## <mark style="color:yellow;">**Prompt**</mark>

Writing prompts for Wan Video differs from writing prompts for Stable Diffusion models. Instead of using a list of tags, you should write in natural language. Focus on describing the actions and motions in the scene to achieve the best results for image-to-video generation.

The basic formula for crafting an effective prompt is **Subject + Motion + Scene**. Here's how it works:

1. **Subject**: Clearly define the main focus of your video, such as a person, object, or animal.
2. **Motion**: Describe the action or movement you want to emphasize, as this is crucial for image-to-video generation.
3. **Scene**: Set the context by detailing the environment, background, or setting where the action takes place.

For example:

* *"A knight (Subject) riding a horse through a forest (Scene) with a flowing cape (Motion)."*
* *"A butterfly (Subject) fluttering its wings (Motion) in a sunlit garden (Scene)."*

This structure ensures clarity and helps the AI generate more accurate and visually compelling results.

## <mark style="color:yellow;">Frames</mark>

A start frame is mandatory, while an end frame is optional. Including both a start frame and an end frame can significantly enhance the consistency and coherence of the video.

The size of the input image plays a crucial role. If the input image is too small, the quality of the generated video will suffer substantially.

High-quality start frames are essential for producing high-quality videos. The better the input, the more refined and visually appealing the output will be. Always ensure your start frame is clear, detailed, and appropriately sized for optimal results.

Below is examples of 2 frames and the final output video:

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FYPqWQwDyZ9Fp0arCBO6K%2FPZb3tux5GB3bkprPcpFv_0.png?alt=media&amp;token=c6591c1a-ef2c-4bf3-b323-813fa8e4de11" alt=""><figcaption><p>Start frame</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fjxrn4XjFzq2GBMCvde75%2FuakTVHvsyaGmj7oLI19w_1.png?alt=media&amp;token=84cf4377-2480-4275-a1b9-c9460f10094d" alt=""><figcaption><p>End frame</p></figcaption></figure></div>

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FMLmiHvfVK9B9P6dOsqfi%2FlXqcdhtEyodbCaOTHEVI.mp4?alt=media&token=754fce12-4be7-4717-8119-7021f0b304c4>" fullWidth="false" %}
Result
{% endembed %}

## <mark style="color:yellow;">**Styles**</mark>

<mark style="color:yellow;">**Tips:**</mark> For optimal results, choose the style that best aligns with the motion you envision. This approach significantly enhances the success rate and ensures greater stability in your video output, delivering smoother and more coherent results. &#x20;

Some styles are trained on lower resolutions, which may result in artifacts when used in Professional Mode. If the output appears blurry in Professional Mode, reducing the strength of the style can help improve the clarity and overall quality of the result.

Below is the example using Live wallpaper style to animate an image

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FSZQH2aAgUDYV4j6sKxKa%2FIMG_1896%202.JPG?alt=media&amp;token=3db0eac8-23c5-46f8-9976-654233b8efcb" alt="" width="375"><figcaption><p>Input image</p></figcaption></figure>

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FLZyJHzeGp0uGNMu9r6f2%2FJKeXRqBourcsyU1ZesLW%202.MP4?alt=media&token=d73dbc6f-ec44-4c8e-81c0-cd3195271ac7>" %}
Output result video
{% endembed %}


# Pose reference

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fy9RuO1wB6va8eS07d09U%2FStart%20Frame.mp4?alt=media&token=f2d6ff1b-4533-4d79-b41d-a5431b251a6b>" %}
Final result
{% endembed %}

In image to video mode, you can use a reference video to guide the pose transitions. For best results, make sure the starting pose in your reference video closely aligns with the initial frame of your input image.&#x20;

1. Upload a start frame
2. Switch on the "Pose reference video"
3. Upload a reference video for the pose

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FKi7YsR5xQamuJ57MRIQq%2FScreenshot_20250428_052220.jpg?alt=media&amp;token=058839b8-643f-419a-8c0b-6cf7e24d0f02" alt="" width="375"><figcaption><p>Upload a start frame</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FgZ2PzcARp0ykt0FQ94xg%2FScreenshot_20250428_014001.jpg?alt=media&amp;token=71b7af92-3c35-4493-981c-62ae1d31c7e3" alt="" width="375"><figcaption><p>reference video for the pose</p></figcaption></figure></div>


# Video to Video

We’ve introduced Video-to-Video in WAN 2.1, allowing you to transform your source videos with AI. Simply upload your input video, enter a text prompt describing your desired output, and let the model generate a new version while preserving motion and composition.

1. Upload a video source
2. Select Control type (Pose, Depth, Face or Canny)
3. Enter the prompt

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FxRmfmWQ1FNox7DwU2Hun%2FScreenshot_20250428_052724.jpg?alt=media&amp;token=e2fefa10-e846-4f92-a9d0-edd2d3e541a5" alt="" width="375"><figcaption></figcaption></figure>

Here is the result of the example using this sample video and prompt:

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FGHGZvqgjhrybFkYRWgzz%2FStart%20Frame%20(1).mp4?alt=media&token=37426615-a485-4130-985d-c850ded36bfb>" %}


# Reference Image

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FMuKfkzFShugCnCp2IFsn%2FStart%20Frame%20(2).mp4?alt=media&token=6ce1abb1-c2c6-41e0-baef-d441f6a135c8>" %}
Prompt: a beautiful girl in kimono. she is in forest. she adjusts hair and bent over.
{% endembed %}

In Video-to-Video mode, you can enable the Reference Image option to guide the AI's output. When activated, the system will analyze your provided reference image and incorporate its visual style, colors, and composition elements into the generated video while maintaining the original video's motion and timing.

The Attention Mask allows you to selectively focus on specific areas of your reference image. By masking a particular region, you direct the AI to prioritize and maintain detail in that area while processing the content.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fnq6GjyRbL45C0gKr6AGB%2FScreenshot_20250428_054812.jpg?alt=media&amp;token=83372f8b-0d6d-49fe-8d31-5e2bc47256ce" alt="" width="375"><figcaption><p>Reference image</p></figcaption></figure>


# Key frames

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FMwnYOEL8sbVgUV8RA0B9%2FStart%20Frame%20(3).mp4?alt=media&token=347e9df6-4969-48b0-a191-67239130b50d>" %}

The Start Key Frame allows you to establish precise initial conditions for your video generation. By setting this key frame, you ensure the AI begins processing with your exact desired composition, style, or subject placement.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FnxcGWdxoL1BbXBMneswP%2FScreenshot_20250428_061652.jpg?alt=media&amp;token=982f20e5-7d72-4dce-a77e-28a44d5905bf" alt="" width="375"><figcaption></figcaption></figure>


# Inpaint

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FvRr8oApGexcmmnPzc8il%2FStart%20Frame%20(6).mp4?alt=media&token=6636f15c-4270-424b-a7a3-b6a1668979d5>" %}

**Introducing Wan2.1’s Video Inpainting Feature!**

Effortlessly swap or remove objects in videos with Wan2.1’s powerful inpainting feature. Perfect for edits, corrections, or creative enhancements, it delivers seamless results. Transform your videos with precision—no complex tools needed.

**Steps** &#x20;

1. Upload a source video

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FUVWv9r1NTBW0Ck05lheO%2FScreenshot_20250508_005501.jpg?alt=media&amp;token=28681ea8-69f7-4928-9c38-e4bde5b640a4" alt="" width="375"><figcaption></figcaption></figure>

2. Select the object you want to replace or remove. For best results, refine the mask by adding more points to key areas—such as the arms, legs, body, and head—ensuring consistent tracking throughout the entire video.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fra4SFFN0avoeQ6LcxNnk%2FScreenshot_20250508_010728.jpg?alt=media&amp;token=b0ca843e-63bb-469d-8055-75d5f4bb7a8c" alt="" width="375"><figcaption></figcaption></figure>

3. Select Free mode or Control mode. Free mode will ignore the control type. You can see the example above for the different output.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FmBCXmkCy4J0KfvWLcVgY%2FScreenshot_20250508_011743.jpg?alt=media&amp;token=2e3edd1f-597b-46b1-8ce7-ac52552e6ac5" alt="" width="375"><figcaption></figcaption></figure>

3. Input the prompt to describe the inpainted video
4. (Optional) Add a reference Image. In the above example, we use this reference image.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F6jqpFg7vrfPlSoP7fvqr%2FStart%20Frame.jpg?alt=media&amp;token=6384e255-9f3f-4098-8e44-fc20ac5f489f" alt=""><figcaption></figcaption></figure>

5. (Optional) Add a key frames. You can add a start frame or end frame to further control the style and structure of the final output video. It is useful especially for removing object.&#x20;

Below is result without using the reference image and start frame.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fiul521v1FP2FiqerVcig%2FStart%20Frame%20(7).mp4?alt=media&token=a7f264f5-c630-4061-bb92-2eaf8fcf1e8c>" %}


# Free mode

By default, video inpaint is restricted by control type so that the inpainted object will maintain the pose or shape of the original video

If you want to completely change the structure of the inpainted object, you can use free mode to ignore the control type.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FF7ywUVq6rNCQeDScaXDZ%2FIMG_2225.jpg?alt=media&amp;token=c613932a-2be9-41fe-bed8-2d74f7d5621d" alt="" width="375"><figcaption><p>Check the "Free mode" box</p></figcaption></figure>

Here is the example of what free mode can achieve:

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F2JY2GQKW6YLXapGxWx3I%2FStart%20Frame%20(8).mp4?alt=media&token=26a93d16-4e89-4a82-af7e-3ea45c8cc908>" %}

Now, the inpainted object won't be restricted by the pose or shape. We can turn the red car into tiger, horse or woman.&#x20;


# Points and Negative points

Video masking differs from image masking because it requires tracking the target object across all frames to ensure accurate inpainting. Rather than manually drawing a mask, you simply specify the object you want to track by adding points, and the system handles the rest.

We want to change the Tony's shirt to spider-man suit in the below video.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FCPqabQfX9r1aJVa9WCQ4%2Ftmp_0iwL9igxJgN6It4NHIvB3nale0g1_1747592308402660_76362.mp4?alt=media&token=cc22f031-4b49-4095-b175-33922712dddf>" fullWidth="false" %}

We’ll mark positive and negative points to mask his shirt. Positive points indicate the areas you want to select, while negative points define regions to exclude. By placing a few points on his shirt, we can generate an mask like this.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F0z4vP4GbuzZgCGmjG2rX%2FScreenshot_20250519_021743.jpg?alt=media&amp;token=291fb07c-3310-44ae-a4b7-43f0076aef9e" alt="" width="375"><figcaption></figcaption></figure>

After placing a few points on his shirt, the system masks Tony's entire body. However, since we want to preserve his face, we’ll add negative points to exclude it from the mask. We can get an mask like this.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fn8sy06OLIuNpOdAPDXjO%2FScreenshot_20250519_021817.jpg?alt=media&amp;token=0251184b-a1dd-4974-a2a4-bc04d7e268fb" alt="" width="375"><figcaption></figcaption></figure>

Now, we enter prompt "a man wears spider man suit" and hit a Start button.&#x20;

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FTVwmNFhG7h4klo6P6TXZ%2FfT51nyq7iF32gtC8IJjf.mp4?alt=media&token=303715e2-b9c4-48a3-a367-8a10f7035bf2>" %}


# Lip sync


# Move

Move allows users to specify exactly how objects should move in generated videos by drawing the motion paths.&#x20;

1. &#x20;Upload a start frame

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fr0AKCgVQIiLfsNvOOv7T%2FScreenshot_20251216_054152.jpg?alt=media&amp;token=b51d973e-325a-4d12-9fb9-3fd9ddc4f23e" alt="" width="375"><figcaption></figcaption></figure>

2. Draw motion paths. In this example, I want to make her move her head and both hands

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FcwuZSU1LlsnkQufDMFX8%2FScreenshot_20251216_054300.jpg?alt=media&amp;token=e970c8f9-2d06-40d4-95df-4df8ee8a4ff8" alt="" width="375"><figcaption></figcaption></figure>

3. Write your prompt

   <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FuTAjy1kJNpyPpd68V6SG%2FScreenshot_20251216_054414.jpg?alt=media&amp;token=f72b2196-e4da-40ed-bca6-bdfe1dc1b328" alt="" width="375"><figcaption></figcaption></figure>

   &#x20;

And that's it. You can hit the start button and wait for the result.

You can click the show motion paths button in the result

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FJH8A0r90fgIQNjwC96p5%2FScreenshot_20251216_060446~2.jpg?alt=media&amp;token=3a5a538c-47af-4e79-8b1a-2a2996247bd7" alt="" width="375"><figcaption></figcaption></figure>

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F5ZYEeGyys07YSyiICjAE%2Fwanmove.mp4?alt=media&token=44f22498-205b-4138-b9c5-04753fb8a0b4>" %}


# Wan2.2 Video

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FKcJeqfHXfTY4B7cptveo%2Fns8Yu7PvEelnHUDUvOZF_0.mp4?alt=media&token=1187cdf7-22f6-43b4-9606-18976b883a22>" %}

We're thrilled to introduce Wan2.2, the latest generation of our AI model, now available in the app!

Experience a new level of creative control with Wan2.2's superior prompt adherence, allowing it to follow your instructions with greater precision. You’ll also notice enhanced visual quality and richer detail, bringing your ideas to life with professional-grade results.

Best of all, you can enjoy these powerful upgrades without any extra cost—the Credit and Power usage for Wan2.2 remains exactly the same as the previous 2.1 version.

Select Wan2.2 and start creating today!

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FV4YRxcRjluUx5aASo7Un%2FIMG_2975.jpg?alt=media&amp;token=db40c55a-7893-4d41-88ea-4b7aa59c453a" alt="" width="375"><figcaption></figcaption></figure>

Please note that certain styles for Wan2.1 might not be compatible with Wan2.2. We have labeled Wan2.2 accordingly. There is a 2.2 on the top left corner for Wan2.2 styles.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FBVHT3ty5e68XGwlqD0BN%2FIMG_2976.jpg?alt=media&amp;token=42a11892-7323-40a6-80b9-7ebeb107ad63" alt="" width="375"><figcaption></figcaption></figure>


# Character Animation

The model can animate any character based on a action video, precisely replicating the facial expressions and movements to generate highly realistic character videos.

It can also replace characters in a video with animated characters, preserving their expressions and movements while replicating the original lighting and color tone for seamless integration into the environment.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FQfpDtUZsEpMpHGI6M9sP%2FScreenshot_20250929_022955.jpg?alt=media&amp;token=496431b9-b338-4c04-8ddb-c7bfe7100160" alt="" width="375"><figcaption></figcaption></figure>

We now offer two animation methods for you, each serving a different purpose. Please check out our [Wan-Animate vs. SCAIL-2 comparison](/video/wan2.2-video/character-animation/wan-animate-vs-scail2) for more information.&#x20;

## **Wan-Animate**

To begin the animation process, upload two files:

1. A Character Image (The subject you wish to animate).
2. An Action Video (The driving motion/pose).

Your character will be animated to precisely match the pose and movement from the action video.

&#x20;We use this character in our example:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F3mMCp1oksWELuJNxyB77%2F0iwL9igxJgN6It4NHIvB3nale0g1_R5yMcsB6uTe8Kch4yM5y_0.webp?alt=media&amp;token=f60a9a2f-8e07-45af-abc4-5076a1c407d4" alt="" width="375"><figcaption></figcaption></figure>

And the action video:

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FlvSIMDD5wouQ7j98VXPD%2Ftmp_0iwL9igxJgN6It4NHIvB3nale0g1_1759054036033173_78786.mp4?alt=media&token=03434693-7853-4440-8ab2-8bd649e1b10a>" %}

We want to replace the woman in the video with our character.&#x20;

Now, we have uploaded character image and action video. We enabled hands, background and relighting options. for more details, you can visit  [this page](/video/wan2.2-video/character-animation/wan-animate-options)

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fruxw1wPDsp5pZQL2Dg65%2FScreenshot_20250929_033018.jpg?alt=media&amp;token=c3a43ccb-704d-47f4-bf73-f25a0886dd23" alt="" width="375"><figcaption></figcaption></figure>

Prompt can be very simple like "a girl is dancing". Below is the final result.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FfK83jXoH8NsVZ08PSz0O%2Fqdg7UyPT7j0EVDguLDPH_0.mp4?alt=media&token=4bd810ea-a8ad-4959-853c-f6b8b3eaf170>" %}


# Wan Animate vs SCAIL2

#### ⚡ TL;DR: Which one should you choose?

* 🎬 Choose Wan-Animate if: You are animating human and you want exact 1:1 pose transfer.
* 🚀 Choose SCAIL-2 if: You are animating either human or non-humans (monsters, animals, robots) or need to handle complex 3D actions like wild spins, flips, and multiple characters interacting without glitches.
* If Standard mode, better use SCAIL-2 for low res generation. Face is always degraded in Wan-Animate in low res.&#x20;

#### What is AI Motion Transfer?

In simple terms, motion transfer means "borrowing the movement from a video and applying it to a still photo." All you need to do is upload a character image (it could be a real person, an anime character, or a monster) and a "driving video" of someone dancing or moving. The AI will then make your character mimic those exact movements!

Right now, the two most powerful and trending technologies for this are **Wan-Animate** and **SCAIL-2**.

#### ⚖️ Core Comparison

| **Feature**      | **🎬 Wan-Animate (The Bone/Skeleton Route)**                                                                                                                                                                                                                                  | **🚀 SCAIL-2 (The Direct AI Route)**                                                                                                                                                              |
| ---------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| How it Works     | It first tracks the human skeleton lines and facial features in the video, then forces your image character to match that skeleton.                                                                                                                                           | No skeleton required. It drops the video and image straight into the AI's brain to match and mimic them pixel-by-pixel.                                                                           |
| Biggest Strength | <p>Lifelike expressions & perfect swapping</p><p><br></p><p>Facial details like glances, blinks, and smiles feel incredibly natural and soulful. Its "Replacement Mode" can swap a character inside a video while perfectly keeping the original lighting and background.</p> | <p>Ultimate freedom & high-difficulty action</p><p><br></p><p>Because it isn't trapped by a human skeleton, it easily handles 3D spins, multi-person interactions, and even non-human shapes.</p> |
| Weakness / Limit | When facing complex 3D spins or overlapping limbs, the skeleton tracking can get confused, causing the body to distort or glitch.                                                                                                                                             | While big actions look amazing, tiny, subtle facial expressions (like eye movements) might not feel quite as detailed as Wan-Animate.                                                             |

**🎯 Choose Wan-Animate when:**

1. Focusing on "Facial Expressions" & Emotion: If your video has lots of close-ups, talking, singing, or needs strong eye contact, Wan-Animate looks the most natural.
2. Seamless Character Swapping (Video-to-Video): If you want to replace the actor in an existing video with your own character image while keeping the exact background and studio lighting.
3. Standard Human Movements: Normal walking, dancing, talking, and standard human poses.

**🎯 Choose SCAIL-2 when:**

1. The Character is Non-Human: You want to animate a cat, a monster, a dragon, or a robot. Since they don't have human skeletons, only SCAIL-2 can handle them smoothly.
2. High-Difficulty 3D Actions: The video involves massive spins, flips, rolling on the ground, or limbs crossing over each other.
3. Multiple Characters: There are two or more people interacting, touching, or hugging in the frame. SCAIL-2 handles physical space much better.
4. Fast, Low-Res Drafts: At lower resolutions, SCAIL-2 stays highly stable and doesn't warp or glitch as easily as Wan-Animate.

#### Example:

Input:

{% columns %}
{% column %}
Character image

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FHLDsRgcFuEvc8YW5ocou%2Fdl_1756732225585.jpg?alt=media&amp;token=f38de59c-7eb0-4569-9f80-72cefa25ab23" alt="" width="375"><figcaption></figcaption></figure>
{% endcolumn %}

{% column %}
Pose Video

{% file src="/files/FfQZZxNfAUfLZsSiqtxJ" %}
{% endcolumn %}
{% endcolumns %}

#### **Character Replacement**

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FxGFv9n62xau1MP2x68fN%2FWeight%EF%BC%9A1.mp4?alt=media&token=0efb9b03-18e6-423d-a620-5bb2daae7c59>" %}

**Pose Transfer**

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FTeOs949q9pR0VURWN3ma%2FWeight%EF%BC%9A1%20(1).mp4?alt=media&token=27af6adb-3d63-4057-8968-4e6c2294c788>" %}


# Wan Animate Options

You can customized the video with different options

<div align="center"><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FrLwINF8KgY44PjCOECuT%2FScreenshot_20250929_012450.jpg?alt=media&amp;token=422c18b6-42a5-4a12-bdaa-58304c6a7e7e" alt="" width="375"><figcaption></figcaption></figure></div>

## Hands

Aligning Hands and Fingers from Action Video

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FHwFYbwhbwbwBMdwXqtlF%2FOriginal%20(1).mp4?alt=media&token=0408504d-2a93-41b9-b9f4-858c36b25718>" %}

But sometimes, you don't want your character to copy the finger movements. This usually happens when the character is non-human. In the example below, the cat with human hands and fingers looks unnatural.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F8v94WdkwL7mk9prPTprV%2FAddaheading1-ezgif.com-crop-video.mp4?alt=media&token=901c5bdd-16a7-4695-8710-96fd4fb84fca>" %}

## Facial Expression

Transfer the facial expression from action video to the character

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FV8MHa0fB69jo2hAMZ2F2%2FOriginal%20(3).mp4?alt=media&token=065530f6-9bfd-4771-a666-70a438dd19ad>" %}

## Background

Use the background of the action video. If this feature is turned off, it will show the background of the character image.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FvCZmxiVSjb73tfGzLi4c%2FOriginal%20(4).mp4?alt=media&token=6113e62d-9c17-4a7a-b5d2-68e3d3b6aedf>" %}

## Relighting

Relight the character to match the color tone and lighting of action video.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fn1wpbzHX66oE5Goambxr%2FOriginal%20(2).mp4?alt=media&token=ea98acdd-114c-4f44-b42d-083b03632b9f>" %}


# Anchor Frame

An **anchor image** is a reference image used to maintain visual consistency across different segments of the generated video. The model constantly refers back to this anchor to ensure subjects and visual style remain stable.


# Seedance 2.0

Director-Level Video Generation

Welcome to an all-new video creation experience! Our app now fully supports Seedance 2.0, bringing you a cinematic AI creation tool right at your fingertips. Whether you are starting with a simple idea, a beautiful photo, or need precise control over characters and camera movements, Seedance 2.0 turns your imagination into reality.

Let's dive into how to master its three core features: Text to Video, Image to Video, and the incredibly powerful Reference to Video.

* [Text to Video](/video/seedance-2.0/text-to-video) - Using text only to create the video
* [Image to Video](/video/seedance-2.0/image-to-video) - Using the input image as first frame to create a video
* [Reference to Video](/video/seedance-2.0/reference-to-video) - Using input images or video as reference, to create a video with the reference elements


# Text to video


# Image to video


# Reference to video


# Minimax H3

MiniMax H3 is MiniMax's latest omni-modal video model, and it's now fully available in Dreamerland. Unlike earlier video models that only read a text prompt or a single image, H3 understands **text, images, video and audio together** — you can hand it a prompt, a few reference photos, a video clip and a music track all at once, and it fuses them into a single coherent shot.

Every H3 clip comes with **native audio generated together with the picture** — dialogue, sound effects and ambience are created in the same pass, so there's no separate audio step and no audio toggle to worry about. Clips run from **4 to 15 seconds**, and you can chain them together with the Extend task to build longer scenes.

### Choosing a Task

There are 6 Minimax tasks in Dreamerland:

* Text to Video
* Image to Video
* [Reference to Video](/video/minimax-h3/reference-to-video)
* Extend Video
* [Video Inpaint](/video/minimax-h3/video-inpaint)
* [Music Video](/video/minimax-h3/music-video)

{% tabs %}
{% tab title="Text" %}
**Text to Video**

The classic starting point — describe the scene and H3 generates it from scratch, sound included. Because H3 generates audio natively, it pays off to describe what you want to *hear* as well as see.
{% endtab %}

{% tab title="Image" %}
**Image to Video**

Bring a still image to life. Upload a **start frame**, an **end frame**, or both:

* **Start frame only** — the video begins from your image and animates forward.
* **End frame only** — H3 generates a shot that lands exactly on your image.
* **Both** — H3 creates a smooth transition between the two frames. Great for morphs, reveals and before/after shots.
  {% endtab %}

{% tab title="Reference" %}
[**Reference to Video**](/video/minimax-h3/reference-to-video)

The most powerful H3 task. Instead of using an image as the literal first frame, you feed H3 **references** and it builds a new shot around them:

* **Up to 5 reference images** — lock a character's face, an outfit, a product or an art style.
* **A reference video** — borrow motion, choreography or camera work from an existing clip.
* **A reference audio** — drive the clip with a voice recording or sound. On H3, an audio reference alone is a valid job: upload a voice line and let the model perform it.
  {% endtab %}

{% tab title="Extend" %}
**Extend Video**

Continue a video you've already made. Upload the previous clip, choose how the extension should be driven (**text**, **first/last frame**, or **reference**), and H3 picks up where the clip left off — the extension automatically inherits the source clip's aspect ratio.

Turn on **Merge source video** if you want the result delivered as one combined clip (original + extension); leave it off to receive just the new part.

This is how you build stories longer than 15 seconds: generate a shot, extend it, extend again.
{% endtab %}

{% tab title="Inpaint" %}
[Video Inpaint](/video/minimax-h3/video-inpaint)

Edit an existing video with a text instruction — no manual masking needed. Upload the source clip and type a **mask prompt** describing what to change, e.g. *"replace the red car with a white horse"* or *"change her jacket to a leather one"*.

* **Control type — None:** the region is freely regenerated from your prompt.
* **Control type — Pose:** the original motion is preserved while the appearance changes — perfect for swapping characters or outfits without losing the performance.

You can also attach up to 5 reference images to tell H3 exactly what the replacement should look like. The output keeps the source clip's length and aspect ratio.
{% endtab %}

{% tab title="Music" %}
[**Music Video**](/video/minimax-h3/music-video)

Purpose-built for making videos cut to a song. Upload a full track (up to 5 minutes) and H3 generates a clip synchronized to it — visuals that move with the music.

Because each generation is still one 4–15 second clip, you build the full video piece by piece:

1. Upload your song and generate the first clip (elapsed length = 0).
2. For the next clip, set **Elapsed video length** to how many seconds you've already covered (e.g. 10).
3. Optionally attach the **previous clip** so the new one continues seamlessly from it — same characters, same scene, next part of the song.
4. Repeat until the song is covered, then stitch the clips in the built-in video editor.

Reference images and a reference video are optional here too, so your performer can stay consistent across every cut.
{% endtab %}
{% endtabs %}

### Official Prompt Guide

You can find the official prompt guide below:

Text to Video and Image to Video: <https://huggingface.co/MiniMaxAI/MiniMax-H3/blob/main/docs/VIDEO_PROMPT_WRITING_GUIDE_base_en.md>

Reference: <https://huggingface.co/MiniMaxAI/MiniMax-H3/blob/main/docs/VIDEO_PROMPT_WRITING_GUIDE_ref_en.md>

You can also use our [AI Director](/video/minimax-h3/ai-director-kumi) to help you create prompt following official prompt guide


# Reference to Video

Reference to Video is MiniMax H3's most powerful task — and the one that makes it a true omni-modal model. Instead of animating an image directly (that's Image to Video), you hand H3 **references** — images, a video clip, an audio track, or any mix of them — and it builds a brand-new shot *around* them. Your character's face, your product, a dance from another video, a recorded voice line: H3 reads them all as one context and fuses them into a single coherent video.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FH1EVCP91DDsIb9d2uaw8%2Fc3vVxXbRZGkAGGLoL9TJ_0.mp4?alt=media&token=5e457d35-d811-4ac4-9b0c-7b38fd4868b0>" %}

\
**Reference to Video vs. Image to Video**

The distinction matters, because they solve different problems:

* **Image to Video** uses your image as the *literal first frame*. The video starts from exactly that picture.
* **Reference to Video** uses your images as *ingredients*. The character from your photo can appear mid-scene, from a new angle, in a new outfit, doing something entirely new — the composition is invented fresh from your prompt, which is also why this task gives you an **aspect ratio** control while Image to Video doesn't.

Rule of thumb: if you want *this exact picture to move*, use Image to Video. If you want *this character / thing / style in a new shot*, use Reference to Video.

### The Three Reference Types

#### Image references (up to 5)

Lock the identity of anything: a character's face, an outfit, a product, a pet, a location, or an overall art style. H3 keeps them consistent throughout the clip. You can combine subjects — for example, two character photos plus one background photo — and direct them in the prompt: *"the woman from \<Picture 1> and the man from the \<Picture 2> sit across from each other in the café from the third image."*

*Use \<Picture N> in prompt to reference the image*

#### Video reference (one clip)&#x20;

Borrow **motion** from existing footage: choreography, a fight sequence, camera movement, a gesture. H3 extracts how things move and re-performs it with your subject and scene. The reference clip is trimmed to your target clip length, so pick the exact seconds of motion you want. Note that attaching a video reference raises the Standard-mode price from 6 to 7 credits per second.

*Use \<Video 1> in prompt to reference the video*

#### Audio reference (one track, 2–15 seconds)

Drive the clip with **sound**: a recorded voice line, a sound effect, a snippet of music. H3 generates the video *to* the audio — a character speaking your recorded dialogue with matching lip movement and delivery is the classic use.

On H3, an audio reference is a complete job by itself: you can generate with **only** a voice recording and a prompt, no images required. Describe who is speaking and where, and H3 invents the performer around your audio.

*Use \<Audio 1> in prompt to reference the video*

#### Mixing them

The real magic is combination — one generation can use all three at once. Character photos define *who*, a video reference defines *how they move*, an audio track defines *what they say or dance to*, and the prompt ties it together.


# Video Inpaint

Video Inpaint lets you **edit an existing video with words**. Swap a subject, change an outfit, replace an object, restyle part of the scene — while everything else in the footage stays exactly as it was. There's no frame-by-frame masking and no rotoscoping: you simply *name* what you want changed, and MiniMax H3 finds it, tracks it through the whole clip, and repaints it.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNMup4q1GDWFotXRdn1F8%2Fdownload%20(1)%20(1).mp4?alt=media&token=888fc48a-0e00-4a6a-bdc6-af4a872bb703>" %}

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fg6j8IX2Vq8k56sg6EVuy%2FScreenshot_20260827_003934.jpg?alt=media&amp;token=e0a6fccc-a172-4a0d-9b96-20923125fd64" alt="" width="375"><figcaption></figcaption></figure>

### How It Works

1. In the MiniMax H3 tab, select the **Inpaint** task.
2. **Upload your source video** — the clip you want to edit (up to 15 seconds; longer uploads can be trimmed in the picker).
3. Type the **Video Mask Prompt** — a short phrase naming what should be replaced (e.g. *"the red car"*).
4. Pick a **control type** (see below).
5. Optionally add up to **5 reference images** to show exactly what the replacement should look like.
6. Type the **Prompt** — a description of what should appear instead. Recommend to use AI Writer to help you write once and change the prompt based on the structure.&#x20;

The result keeps the source clip's **length** and **aspect ratio** automatically — that's why the duration slider and aspect ratio control disappear for this task.

### What Is the Video Mask Prompt?

In classic image inpainting, you paint a mask over the area you want to change. In video, painting a mask on every frame would be impossibly tedious — so H3 masks **from text instead**. The Video Mask Prompt is that text: it tells the model *what to find* in the footage, and H3 detects it and follows it across every frame, even as it moves, turns, or is partially hidden.

The two text fields do different jobs, and keeping them straight is the key to this task:

| Field                 | Answers                           | Example                                            |
| --------------------- | --------------------------------- | -------------------------------------------------- |
| **Video Mask Prompt** | *What in the clip gets replaced?* | `the woman's jacket`                               |
| **Prompt**            | *What appears in its place?*      | `a black leather biker jacket with silver zippers` |

Think of the mask prompt as pointing, and the prompt as describing.

More Example:

<table><thead><tr><th width="282.48828125">Use Case</th><th>Video Mask Prompt</th></tr></thead><tbody><tr><td>Replace the entire person</td><td>person</td></tr><tr><td>Change the face and hair of a person</td><td>head, hair</td></tr><tr><td>Replace the woman on the right</td><td>woman on the right</td></tr><tr><td>Replace a red car</td><td>red car</td></tr></tbody></table>

### Control Type

* **None** — the masked region is freely regenerated from your prompt. Use this when replacing an object with something that moves differently (a car → a horse, a coffee cup → a crystal ball).
* **Pose** — the original motion is preserved as much as possible while the appearance changes. Use this when the *performance* matters: swapping a person's identity or outfit while keeping their exact dance, or gestures.


# Music Video

The Music Video task turns a song into a video. Upload a track, and MiniMax H3 generates footage that's **synchronized to the music** — cuts, motion and mood that follow the beat, with your track as the soundtrack. Unlike every other H3 task, the audio here isn't generated: it's *your* song, and the video is built to fit it.

Because each H3 generation still produces one clip of 4–15 seconds, a full music video is made **piece by piece** — and this task is designed exactly for that: it keeps track of where you are in the song, so every new clip picks up at the right beat.

Below example is a full song with a one character reference image. combine with 5 x 15 sec video.

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fj5BbZLXCHDceAgJgJNVw%2Fmusic_video_1.mp4?alt=media&token=b892fe3b-07a5-428a-98c7-34724fe6c500>" %}

### How It Works

1. In the MiniMax H3 tab, select the **Music Video** task.
2. **Upload the full track** — this is the one required input. Songs up to 5 minutes are supported.
3. Set the **Elapsed video length** (see below). For your first clip, leave it at 0.
4. Upload the **previous video** to continue if it is not your first clip. so the joint between clips is seamless
5. Optionally attach **references** — up to 5 images and a video reference — to keep your performer, band or visual style consistent across every clip.
6. Write a prompt describing the visuals for *this* part of the song, choose the duration (4–15s), and generate.
7. Repeat for the next section of the song, then stitch the clips together in the built-in video editor.

### What Is "Elapsed Video Length"?

It's the task's position marker in the song: **how many seconds of the track your earlier clips already cover**. H3 uses it to know which part of the song this clip belongs to, so the visuals sync to the right section — the verse gets verse energy, the drop gets the drop.

* **First clip:** elapsed length = 0. The clip opens the song.
* **Second clip:** if your first clip was 10 seconds, set elapsed length to **10**. The new clip is generated against seconds 10–20 of the track.
* **And so on** — after each generation, add the clip's length to the running total.

You type the value rather than slide it, because you read it off what you've already rendered: it's simply the total length of the clips you've made so far.

### The Previous Video

Once elapsed length is above 0, a **Previous video** box appears. Attach the clip that came before, and H3 continues it *visually* — same characters, same scene, same lighting — so the joint between clips is seamless.

It's optional on purpose: a music video often cuts between unrelated scenes (performance shot → street scene → close-up), and each new scene is a fresh generation that only needs to sync to the song, not to the previous picture. Attach the previous clip when you want **continuity**; leave it out when you want a **cut**.

One detail to know: when you attach a previous clip, the new clip inherits its aspect ratio — the ratio control only applies while you're starting fresh.

### Music Video vs. Extend

Both tasks make clips that follow earlier clips, so it's fair to ask when to use which. The difference is **what anchors the continuation**:

|                  | **Extend**                                        | **Music Video**                                       |
| ---------------- | ------------------------------------------------- | ----------------------------------------------------- |
| Anchored to      | The previous **clip** — it continues that footage | The **song's timeline** — it continues the track      |
| Required input   | The source video                                  | The full audio track                                  |
| Previous clip    | Required — it's the whole point                   | Optional — attach for continuity, skip for a cut      |
| Audio            | Generated by H3, fresh for each clip              | Your uploaded song, synced                            |
| Position control | None — it always picks up where the clip ends     | Elapsed video length — jump to any point in the song  |
| Merge option     | Yes — can return source + extension as one clip   | No — returns the new clip; you assemble in the editor |

Rule of thumb: if the **story** is the backbone — one continuous scene unfolding — use **Extend**. If the **music** is the backbone — visuals serving a track, with freedom to cut between scenes — use **Music Video**. (And note that Music Video can do continuity too, via the previous-clip box; Extend just can't do song sync.)<br>


# AI Director (Kumi)

Writing a good video prompt is a skill — H3 responds best to prompts that follow the official prompt structure including the shot, the camera, the action *and* the audio. The **Prompt Writer** does that work for you: tell it your idea in a sentence, and it writes a production-ready H3 prompt.

You'll find it as the **✨ Prompt Writer** button next to the prompt field in the MiniMax H3 tab.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FuDGjtG47KFEN1v7Dcvks%2FIMG_6310.jpg?alt=media&amp;token=1d7cc281-b350-4db0-9dd6-c68148160ac5" alt="" width="375"><figcaption></figcaption></figure>

#### How it works

1. **Type your idea — in any language.** A rough one-liner is enough (e.g. *"a girl dancing in the rain"*, or the same in Japanese or Spanish). The finished prompt always comes back in English, which is what H3 understands best. If you've already typed something in the prompt field, it's carried over automatically.
2. **Check the context card.** The writer already knows everything you've set up on the tab — the selected task, any reference or frame images you've uploaded, a video reference, the clip duration, whether this is an inpaint edit or a music-video continuation. It reads all of that automatically, so you never have to restate it; the card at the top shows exactly what it's working from.
3. **Add extra instructions (optional).** Steer the style without rewriting your idea — e.g. *"night scene, cool tones, no dialogue, change the subject to the new reference image"*.
4. **Pick a mode:**
   * **Single** — one polished prompt for one clip..
   * **Storyboard** — breaks your idea into a sequence of **2 to 6 connected clip prompts**, each written to flow into the next. Costs 1 credit per clip. This pairs perfectly with the **Extend** task: generate clip 1, then extend it with clip 2's prompt, and so on, to build a full scene far longer than 15 seconds.
5. **Apply.** Review the result (in Storyboard mode, switch between clips with the chips), then tap **Apply** on the prompt you want. It fills the prompt field but doesn't start generating — you can still adjust duration, mode or images before you hit Generate.

Not happy with the result? **Rewrite** takes you back to the input with everything pre-filled, so you can tweak your idea before spending another credit.

#### History

Your last results are saved in the writer's **History** (the clock icon). This matters most for storyboards: generate clip 1 today, and tomorrow you can reopen the same storyboard and apply clip 2's prompt to continue exactly where you left off.


# What is Kumi?

your creative guide in Dreamerland

Kumi is the conversational AI agent powering Dreamerland — your creative companion for bringing imagination to life. Instead of writing technical prompts, just tell Kumi what you want: a character, a scene, a mood. Kumi listens, asks the right questions, and turns your words into beautiful AI-generated images and videos.

Chat naturally, share reference images, and tweak anything — a different outfit, softer light, a slower camera move. Kumi remembers your conversation, so each round gets closer to what you imagined.

From original characters and fan art to mood boards and short videos, Kumi is for anyone who's thought, "I wish I could see this."

For detail, you can look at [Chat with Kumi](/kumi/chat-with-kumi)

You can also create your own [Persona](/kumi/persona)

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FTJGFEPOINgLE0Ax84zQw%2FIMG_5207.jpg?alt=media&amp;token=760deddc-7b2c-4335-84cb-c0be97fb8580" alt="" width="375"><figcaption></figcaption></figure>


# Chat with Kumi

Chatting with Kumi is simple — just open a conversation and start talking. Here's what you need to know to get the most out of it.

#### Daily Free Chats

* You get **25 free chats every day**, refreshed daily.
* Once you've used them up, each additional message costs **1 credit**.
* Free chats are the easiest way to explore, experiment, and refine ideas without worrying about cost.

#### Managing Your Chats

Open the **drawer** (side menu) to manage your conversations:

* **Create a new chat** anytime with the "New Chat" button. Use a fresh chat when you're starting a new idea or character — it keeps the context clean.
* **Browse past sessions** in the drawer list. Every conversation is saved, so you can jump back in, continue where you left off, or revisit an old creation.

#### Choose Your Model Checkpoint First

Before you start chatting, **pick a model**. Each model is built for different tasks, so the one you pick decides what Kumi can actually do in that chat.

**SDXL-type models**

* Text-to-image
* Inpaint: edit or replace parts of an existing image

**Z-Image-type models** — for realistic image generation

* Text-to-image

**Seedance-type models** — for video creation

* Text-to-video: turn a description into a short clip
* Image-to-video: use the first frame / last frame to create video
* Reference-to-video: use a reference images and reference viddeo to guide the style or subject of a video
* Extend video: continue an existing clip into a longer scene

#### Tips

* **Start fresh for new ideas.** Don't pile unrelated requests into one chat — a new session keeps Kumi focused.
* **Stay in one chat for refinement.** When you're iterating on the same character or scene, the same chat helps Kumi remember context.
* **Save your credits.** Use free chats for exploration, and lean on credits when you're polishing something you really want to finish.


# Text to Image


# Inpaint


# Reference to Video


# Persona

A **persona** is the character Kumi becomes when you chat. By default, Kumi is a warm 22-year-old creative guide — but personas let you decide who's really on the other side.

Each persona has a name, personality, appearance, and an example message that shapes how they speak, feel, and respond. Build a poetic muse, a cheeky idol, or an original character from your own story. Switch between them anytime, share favorites with friends, and refine them as you go.

The image and video magic stays the same — but the voice wrapped around it is now entirely yours to design.

To create your persona, click the Persona in the New Chat Page.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FBsIem2pjmGXtgn1iNO5B%2FIMG_5207.jpeg?alt=media&amp;token=9a18e2c0-7002-4a70-90b9-d120ee63eb43" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FntObP55sOgxmySLwYorL%2FIMG_5210%202.jpg?alt=media&amp;token=1d35f4a2-94ba-4533-9d76-564eb47f267e" alt="" width="375"><figcaption></figcaption></figure></div>

<br>


# New persona

When you create a persona, you're filling in a few key fields that together bring your character to life. Here's what each one does — and how to write a great one.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fg3ivFTcPWvBdHrgOcrYq%2FIMG_5211.jpg?alt=media&amp;token=a3a3a6bc-352c-4cb7-9e2f-6a438072b601" alt="" width="375"><figcaption></figcaption></figure>

#### Persona

This is the **personality and identity** of your character — who they are, how they think, how they behave. It's the heart of the persona.

**Tips:**

* Describe their personality traits, speaking style, and attitude (e.g. *playful, sarcastic, gentle, mysterious*).
* Add background or role if it matters (*a retired knight, a pop idol, your childhood friend*).
* Mention how they treat the user — affectionate, teasing, formal, protective.
* Keep it focused. A tight 3–6 sentence description works better than a long essay.

#### Appearance

This is what your character **looks like** — used to keep their visual identity consistent across generated images.

**Tips:**

* Cover the essentials: hair color and style, eye color, age range, body type, signature outfit or accessories.
* Be specific where it matters (*long silver hair with a braid*) and loose where it doesn't (*usually wears casual streetwear*).
* Avoid contradictions — if you say "short black hair," don't also say "long blonde curls."
* Skip technical art jargon; plain description works best.

#### Example Message

This is a **sample line your character might say** — it shows Kumi how this persona actually talks.

<mark style="color:$primary;">Wrap actions in asterisks\*. For example: \*</mark>*<mark style="color:$primary;">leans against the doorway with a lazy smile\*</mark>* <mark style="color:$primary;"></mark><mark style="color:$primary;">Oh? You're back already. \*</mark>*<mark style="color:$primary;">tilts head\*</mark>* <mark style="color:$primary;"></mark><mark style="color:$primary;">I was starting to think you'd forgotten about me.</mark>

**Tips:**

* Write it in your character's natural voice, as if they're greeting you or reacting to something.
* Match the tone you want: cheerful, sultry, reserved, dramatic.
* Include their speech quirks — pet names, slang, emoji habits, sentence rhythm.
* Three or four examples is enough. Show, don't explain.


# Share and import persona

### Sharing Your Persona

Built a persona you love? You can share them with friends so they can chat with the same character in their own Dreamerland.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FCbTOw9AuBTAYyR12X22R%2FIMG_5208.jpg?alt=media&amp;token=c76ed007-2606-4748-b5a6-8b6ba96424bc" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FZCzTyXNeN0HaNOfv9bRE%2FIMG_5209.PNG?alt=media&amp;token=1d561d5e-1c34-4d62-8438-8ed10e0b813a" alt="" width="375"><figcaption></figcaption></figure></div>

#### How It Works

1. **Generate a share code.** Open the persona you want to share and tap the share button. Kumi creates a short, unique code tied to that persona.
2. **Send the code to a friend.** Copy the code and send it however you like — message, social, in person.
3. **Your friend imports it.** In their persona library, they paste the code and import. A copy of your persona lands in their library, ready to chat with.

#### What Gets Shared

* The persona's **name**, **personality**, **appearance**, and **example message** — everything that defines the character.
* The avatar, if you've set one.

#### Important Things to Know

* **Sharing creates a copy.** Once imported, it's their persona to keep and customize. Edits they make won't affect yours.
* **Your edits don't sync back.** If you update your persona later, friends who already imported it keep the original version. Share a fresh code if you want them to get the latest.
* **Share codes can expire.** For safety, codes have a limited lifetime. If a code stops working, just generate a new one.
* **Be thoughtful about what you share.** Personas go through the same safety checks on import as when they're created, so anything that breaks the rules won't make it through.

#### Tips

* **Polish before sharing.** Chat with your persona a few times and refine the fields so the first impression matches your vision.
* **Add a good example message.** This is what really sells the personality — make sure it captures their voice.
* **Name them memorably.** A distinct name helps friends find them in a growing library.


# Live Portrait

Animates the face of your character in one click

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FRFq6bRZxAm1nTwCXtSTg%2Flive_portrait.gif?alt=media&amp;token=0f8aad4e-0641-43d7-ad03-ddd5c317b7a4" alt=""><figcaption></figcaption></figure>

You can find the "Live Portrait" tool on the Tools page to upload your image, or use the action menu to animate your existing artwork.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fb5DpTiYsSFHyoQWzSQGq%2FIMG_1656.jpg?alt=media&amp;token=f5f62789-89d2-46b9-bbb9-0bd2dbab0449" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FwgwmRTYgY0GfEcoTFAXh%2FIMG_1657%202.jpg?alt=media&amp;token=0d809c47-d136-444a-908e-0447a7ac0229" alt="" width="375"><figcaption></figcaption></figure></div>

After adding an image, you need to choose a facial expression or upload your own.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FG3ajxyRZy2toiUFYs266%2FIMG_1663.jpg?alt=media&amp;token=7567d609-0190-4790-a80b-5c821758d21c" alt="" width="375"><figcaption><p>Choose a expression</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Ff13LAMQhswqZeraP1m2g%2FIMG_1661.jpg?alt=media&amp;token=45cface1-bdba-493b-949c-e6f293728cf4" alt="" width="375"><figcaption><p>Upload your own video</p></figcaption></figure></div>

Hit Start Now to see the result. Here are some results with this image:

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FqpvSChKxqf03DYCD9Ajz%2Fb49b1a30-c25f-107a-a056-f73aae63a25f_1720618331837.gif?alt=media&amp;token=05ebcd6f-ba64-4ca3-be9a-44bf7aabd9be" alt=""><figcaption><p>My video</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FzYPY6NMQUhsjqxxRBn1G%2F2ce28cf0-c0ab-107a-a056-f73aae63a25f_1720618143878.gif?alt=media&amp;token=5a6e6227-d04b-480e-91ba-4c13f86dde52" alt=""><figcaption><p>Blinking</p></figcaption></figure></div>

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FdeuZBnnSTILfiDQOoOa4%2F090517e0-c15e-107a-a056-f73aae63a25f_1720618220798.gif?alt=media&amp;token=4d5d6864-dd96-450e-86f8-638319356311" alt=""><figcaption><p>Smile</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FV77sm9cwyDu5Y01iDQYV%2Fd7e73eb0-c08e-107a-a056-f73aae63a25f_1720618132212.gif?alt=media&amp;token=b576dcf9-180e-471e-becc-0e66aa33e92e" alt=""><figcaption><p>Shocked</p></figcaption></figure></div>


# Motion brush

Draw and animate any image

Motion brush is a tool that animate any image you generated. It transforms static pictures into dynamic visual narratives, where colors blend and objects come alive. Unleash your creativity and captivate audiences with this groundbreaking tool.

In this example, we want to animate this image:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fh5quKuGClYxnLdqUyyPp%2FIMG_9705%202.JPG?alt=media&amp;token=b61ebdc9-ac77-44fb-b4ce-bf484f304a10" alt=""><figcaption></figcaption></figure>

In the bottom bar, Select Animate -> Motion brush to start drawing a mask in your image.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FrNVcISPP5e7bfqQB0FHy%2FIMG_9713.jpg?alt=media&amp;token=0b930d7c-f2d9-4ca3-8aaa-b561c3c41d2f" alt="" width="375"><figcaption></figcaption></figure>

Draw a mask on the area where you would like to add motion. Afterwards, you may edit the settings if needed. In this particular example, we are animating water and clouds, so we will choose the "Liquid motion" option and change FPS to 12.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F63iL3B0gQSo6N1MhJ7U2%2FIMG_9702.jpg?alt=media&amp;token=22819c47-d619-49a0-8e4a-8e4cb5f2bd0d" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FeC2HpzmY8N40jeoO5iZu%2FIMG_9714.jpg?alt=media&amp;token=25e37272-095d-405c-afc9-edcd7a5c7742" alt="" width="375"><figcaption></figcaption></figure></div>

Hit the "Animate now" button and see the result:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fbyd8egh9FydZrLGSI0SC%2Fezgif-3-304ee3e3e6.gif?alt=media&amp;token=a17bd6a3-560a-4264-8de1-1eab5b744c5a" alt=""><figcaption></figcaption></figure>

We can also use text to mask to mask objects that we want to animate. We choose "Bounce motion" in this example.&#x20;

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fuct5ToLVpzQTKFlWht5H%2FIMG_9715.jpg?alt=media&amp;token=68f7bd72-f933-4c7e-a256-76adcfafa6f6" alt="" width="375"><figcaption></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FkqIAKzo7BQQPHqOyfNI3%2FIMG_9717.jpg?alt=media&amp;token=3b0d1105-9c5f-4d21-b0e1-2f7baf817a99" alt="" width="375"><figcaption></figcaption></figure></div>

Hit the "Animate now" button and see the result. You can also apply face detailer to the result:&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FtCgqR2OXF11lsdElVVMT%2Fezgif-3-47e24cfb43.gif?alt=media&amp;token=bb01676e-0504-47f7-bbdc-f067f376aec7" alt=""><figcaption></figcaption></figure>


# Sampling method

There are several sampling methods are available in Dreamerland including Euler A, Euler, DDIM, DPM++ 2M Karras, DMP++2M SDE Karras and UniPC

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FIdmr1nYlDYUhleB1itzh%2FIMG_7752.jpg?alt=media&amp;token=687f8c7e-a394-4de7-8f7d-a19cc2bac56e" alt="" width="375"><figcaption></figcaption></figure>

In order to understand what sampling method is, we have to know how Stable Diffusion generate an image from scratch.

To generate an image, Stable Diffusion begins by generating a completely random image in the latent space. Then, the noise predictor estimates the noise within the image, which is subsequently subtracted. This iterative process is repeated multiple times, resulting in a final output of a clean image.&#x20;

The process to remove noise and generate new images at each step is referred to as **sampling**. The method used in sampling is called the sampler or sampling method. The sampling method remove noise and generate a cleaner image each step.&#x20;

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FARKlpwl1unyYO4sO4o3S%2Fcat_euler_15.webp?alt=media&amp;token=f8ea4586-fdf6-48f5-9114-d06948243108" alt="" width="256"><figcaption><p>Sampling process step by step</p></figcaption></figure>

**What the difference between sampling methods?**

They are different mathematic method to predict noise. We will give you a big picture of each one but we won't go into technical here.

**Euler A and Euler**

A stands for Ancestral. Ancestral sampler will add noise to the image at each step. Therefore the result of Euler A will be more creative. However, Euler A would not converge because noise will be added at each step to introduce randomness.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FHrBLPQQ7jNhlWHJvgZsi%2Feuler-2-40.webp?alt=media&amp;token=3c6cbd65-617b-4f7a-9001-d0d6d70854c2" alt="" width="256"><figcaption><p>Euler</p></figcaption></figure>

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FcRy8t8WHHhLIWxymCekh%2Feuler-a-2-40.webp?alt=media&amp;token=5b115561-d0ef-4dfb-8ab4-892990a4b5b9" alt="" width="256"><figcaption><p>Euler A</p></figcaption></figure>

**DDIM**

DDIM (Denoising Diffusion Implicit Model) is one of the first samplers designed for diffusion models. DDIM only takes eight steps to achieve incredible images

**DPM++**

DPM++ trades speed for quality. It normally take more steps than other sampling methods to get high quality images. It’s better suited for highly tuned prompts.

**UniPC**&#x20;

UniPC (Unified Predictor-Corrector) Framework for Fast Sampling of Diffusion Models is introduced in 2023 by Wenliang Zhao, Lujia Bai, Yongming Rao, Jie Zhou, Jiwen Lu. it can achieve high-quality image generation in **5-10 steps**.


# Guidance scale

The Guidance Scale Stable Diffusion, or Classifier-Free Guidance Scale (CFG), is used in AI to decide how much an AI art creation follows the text prompt. It's basically a number that shows how important the text or image description is when generating AI art.

If you crank up the guidance scale, the generated images will stick closely to the provided text prompts, but they might lack that spark of creativity. So, it's better to aim for a lower CFG value when creating images, but not too low either. Usually, keeping the numbers between seven and nine will give you high-quality results, unless you really know what you're doing with a high CFG setting.


# Negative embeddings

<mark style="background-color:orange;">**What is embedding?**</mark>

Embedding is a method used to introduce new keywords or concepts into a model without modifying the model itself. A new keyword is defined for the desired object or style that is not already present in the model. This new keyword is tokenized. the token is then converted into a unique embedding vector, which is a numerical representation used by the model for image generation.

Overall, embedding offers a way to expand the capabilities of a model by introducing new keywords and associated embedding vector, thereby enabling the generation of images or outputs in different styles or with new objects.

<mark style="background-color:orange;">**What is negative embedding?**</mark>

This is an embedding used in the negative field to avoid styles or objects that you don't want to see, such as a poorly-formed hand. Negative embedding is actually trained using images of undesirable contents. For instance, the negative hands embedding is trained using images of hands with missing fingers, extra fingers, or deformed shapes, with the aim of creating an embedding that can represent undesirable hands. When this negative embedding is employed in the negative field, it introduces the concept of bad hands to the model and attempts to avoid generating them.

<mark style="background-color:orange;">**How to use it?**</mark>

Click on "Negative embeddings" in creation page.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FI7yywalMkJCuAgGB8MOy%2FIMG_7753.jpg?alt=media&amp;token=9ec16e32-83e9-48cc-a0cc-bc7beb7ce5d6" alt="" width="375"><figcaption></figcaption></figure>

If you are unfamiliar with all these negative embedding models, you can click on the model's name. This will take you to the model detail page, where you can find the model's introduction and view example images.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FcmwslGaRsmxvT6dbKgjY%2FIMG_7754.jpg?alt=media&amp;token=acfec498-8983-499c-8566-2678563f44ad" alt="" width="375"><figcaption></figcaption></figure>


# CLIP skip

<mark style="background-color:orange;">**What is CLIP skip?**</mark>&#x20;

Clip Skip is a feature that allows users to selectively bypass certain layers of the CLIP model during the image generation process. By skipping layers, users can achieve more creative and less specific results, as the CLIP model can sometimes provide overly precise descriptions.

The choice of CLIP skip value depends on the desired outcome and the specific image being generated. Lower values yield more specific results, while higher values promote greater creative freedom.

It is important to note the following considerations when using CLIP skip:

1. Higher CLIP skip values result in more abstract images.
2. Higher CLIP skip value results in less adherence to your prompt.
3. Certain models may not perform well with high Clip Skip values.


# Model sampling shift

Model sampling shift adjusts the time step 'shift' during sampling. A higher shift emphasizes overall composition, while a lower shift focuses on details.

Below is the comparison of different shift value.&#x20;

| Shift: 1.0                                                                                                                                                                                                                                                                                                 | Shift: 3.0                                                                                                                                                                                                                                                                                                 | Shift: 5.0                                                                                                                                                                                                                                                                                                 |
| ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FmMTbWW3j82o74g1Qfz8b%2Fshift1.jpg?alt=media&amp;token=f9dae6dd-62e5-4aae-aa21-63c437bece39" alt=""><figcaption></figcaption></figure></div>                 | <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fx7Q9EIauagdFas6kRpY8%2Fshift3.jpg?alt=media&amp;token=a077c09e-3381-490c-b029-8aeb5bb50496" alt=""><figcaption></figcaption></figure></div>                 | <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FTG3dotqcJxj8ygZjeJGx%2Fshift5.jpg?alt=media&amp;token=4b57aec4-56c9-4bd1-a28e-886bd150696b" alt=""><figcaption></figcaption></figure></div>                 |
| <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPzeTGyFdM4Phjx74SfKg%2Fshift1.jpg?alt=media&amp;token=47018a24-bcdf-401b-bb88-cf6444c5ca59" alt=""><figcaption></figcaption></figure></div>                 | <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FKUvaqQUQqsk6AP7bMMAZ%2Fshift3.jpg?alt=media&amp;token=2a31f19a-d449-4e92-ac3a-0ecce71af603" alt=""><figcaption></figcaption></figure></div>                 | <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fl6TjXRic0dNYbG2mxa38%2Fshift5.jpg?alt=media&amp;token=0d8ad2a8-e25e-4020-ac78-ff7dc7f1f8e5" alt=""><figcaption></figcaption></figure></div>                 |
| <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPqwZJb4QyvleRIIzAxG3%2Fabd3Zv4PCOfsDx61BgsV_1.jpg?alt=media&amp;token=e1d79937-0569-4eef-860b-1ed75288a09a" alt=""><figcaption></figcaption></figure></div> | <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F27VU48zMun1rBR0FnHPo%2F3PGTEBdT0eMfQh1BvXmv_1.jpg?alt=media&amp;token=0cf3e1fb-2c28-49a0-ac61-15e25bcb738d" alt=""><figcaption></figcaption></figure></div> | <div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FcaKVTW6pyL9LZGVefldX%2FE0bduTQVSxI9AUXdmvU8_1.jpg?alt=media&amp;token=b06dd630-2638-48d0-b5fa-082deb1cee22" alt=""><figcaption></figcaption></figure></div> |


# Motion Amplitude

**Boosts Motion Dynamics:** Reduces slow-motion drag, increasing motion amplitude by 15% to 50%.

**Enhanced Responsiveness:** Camera movements are more responsive to prompts and greater amplitude.

Below is the comparison of value 1.0, 1.15 and 1.3

{% embed url="<https://files.gitbook.com/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FSQ8lCAzAAAgunolgjGPW%2FStart%20Frame%20(10).mp4?alt=media&token=56ae7903-fad1-43ff-a4aa-29155ecc0522>" %}


# SD Prompt syntax

### Adjusting Prompt Weight with Syntax

> Note: This syntax applies specifically to Stable Diffusion (SD) and SDXL. Other AI models may use different weighting formats.

#### 1. Increasing Weight: `()`

Use parentheses to emphasize a tag, making it more prominent in the generated image.

* Nesting Syntax: Nesting parentheses increases weight exponentially.
  * `(keyword)` = $$1.1$$
  * `((keyword))` = $$1.1 \times 1.1 = \mathbf{1.21}$$
  * `(((keyword)))` = $$1.1 \times 1.1 \times 1.1 = \mathbf{1.33}$$
* Explicit Weight Syntax: You can also define exact numerical values directly, such as `(keyword:1.1)` or `(keyword:1.25)`.

#### 2. Decreasing Weight: `[]`

Use brackets to de-emphasize a tag, reducing its influence without removing it entirely.

* Nesting Syntax: Nesting brackets reduces weight exponentially.
  * `[keyword]` = $$0.9$$ (Equivalent to `(keyword:0.9)`)
  * `[[keyword]]` = $$0.9 \times 0.9 = \mathbf{0.81}$$
  * `[[[keyword]]]` = $$0.9 \times 0.9 \times 0.9 = \mathbf{0.73}$$

#### Quick Reference Table

| **Syntax**      | **Type**           | **Multiplier** | **Explicit Equivalent** |
| --------------- | ------------------ | -------------- | ----------------------- |
| `(((keyword)))` | Strong Emphasis    | $$1.33\times$$ | `(keyword:1.33)`        |
| `((keyword))`   | Medium Emphasis    | $$1.21\times$$ | `(keyword:1.21)`        |
| `(keyword)`     | Light Emphasis     | $$1.10\times$$ | `(keyword:1.1)`         |
| `keyword`       | Neutral            | $$1.00\times$$ | `(keyword:1.0)`         |
| `[keyword]`     | Light De-emphasis  | $$0.90\times$$ | `(keyword:0.9)`         |
| `[[keyword]]`   | Medium De-emphasis | $$0.81\times$$ | `(keyword:0.81)`        |
| `[[[keyword]]]` | Strong De-emphasis | $$0.73\times$$ | `(keyword:0.73)`        |


# Krea2 Prompt Weight

### Adjusting Prompt Weight in Krea 2

> Note: This syntax applies specifically to Krea 2. Unlike SD/SDXL, Krea 2 does not support nested brackets or parentheses like `((word))` or `[[word]]`.

#### 1. Weight Syntax: Explicit Numerical Values `(word:weight)`

Instead of nesting brackets, Krea 2 uses explicit numerical ratios inside single parentheses to adjust prompt influence.

* Emphasis (Increase Weight): Use values greater than `1.0`.
  * `(word:1.2)` = Increases prompt weight to 1.2×
* De-emphasis (Decrease Weight): Use values between `0.0` and `1.0`.
  * `(word:0.5)` = Reduces prompt weight to 0.5×

#### 2. Negative Weights: Direct Replacement for Negative Prompts

Krea 2 allow you to handle negative prompting directly within the main prompt line using negative numbers.

*

```
Negative Weight Syntax: `(word:-weight)`
```

```
* `(word:-0.5)` = Lightly deprioritizes the concept.
* `(word:-1.0)` = Standard negative suppression (equivalent to traditional Negative Prompt).
* `(word:-2.0)` = Strong/Aggressive suppression (useful for stubborn artifacts, bad quality, or unwanted styles).
```

> Key Benefit: You don't need a separate "Negative Prompt" text box; you can control both positive and negative attributes within a single prompt line.

For example, If you don't want to generate a woman as Japanese girl, you can add (japanese girl:-1) in your prompt.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FsAXx57X9Q4yjYEuaGvxz%2FScreenshot_20260725_064636.jpg?alt=media&amp;token=4f165692-12de-4727-aca4-bc0d79d42f36" alt="" width="375"><figcaption></figcaption></figure>

If you click  $$-$$ on highlighted plain text, it will start at (word:-1.0)\
If you click  $$+$$ on highlighted plain text, it will start at (word:1.0)

#### Quick Reference Comparison (SD/SDXL vs. Krea 2)

| **Effect**      | **SD / SDXL Syntax**                    | **Krea 2 Syntax**                |
| --------------- | --------------------------------------- | -------------------------------- |
| Emphasis        | `((word))` or `(word:1.21)`             | `(word:1.2)`                     |
| De-emphasis     | `[word]` or `(word:0.9)`                | `(word:0.5)`                     |
| Negative Weight | *Requires separate Negative Prompt box* | `(word:-1.0)` *(In main prompt)* |
| Nested Syntax   | Supported `(((...)))` / `[[[...]]]`     | Not supported                    |


# Dreamerland Web app

&#x20;Here is a web app version for Dreamerland

{% embed url="<https://app.dreamerland.ai>" %}

Both free and PRO users can access the web app to browse and download their art. Image generating functions are currently available only for PRO users in the web app.


# Bad quality image or deformed image


# High res. fix vs tiled upscale

High-resolution fix and tiled upscale are both super-resolution workflows used to enhance images. However, they have different pros and cons.

In the case of high-resolution fix, it aims to fix the image but tends to smooth out the details. While this approach may work well for anime images, it may not be suitable for realistic photographs where preserving fine details is crucial.

On the other hand, tiled upscale focuses on preserving more details and slightly fixing artifacts. However, if the original image is of very low quality, tiled upscale may not be powerful enough to completely eliminate all artifacts, unlike high-resolution fix.

Let's go to some examples:

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FSiH24ypsorNfHa9k6l5Z%2FjGpRaZXBgmD6De1a4rn9_0.png?alt=media&amp;token=194a2e9e-96a8-47ef-9e4d-db25b84683ff" alt="" width="256"><figcaption><p>Original image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FkjR8u2gw0vIyO5lBpSDU%2FLfTOzM26YuSTHBCtdhUT_0.png?alt=media&amp;token=8afe6787-699b-470b-9365-06dfb9959319" alt="" width="375"><figcaption><p>2X High res. fix image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FizJvEFQpbVvAtOzCdNP4%2FVcFJPoMZVDRBQyOFvr1o_0.png?alt=media&amp;token=a0e9a0fd-63e5-4b03-ae34-3caeec5685b6" alt="" width="375"><figcaption><p>2X Tiled upscale image</p></figcaption></figure></div>

Obviously, high res. fix makes the skin smooth because of smoothing out details. Tiled upscale preserve more detail.

&#x20;Here is an example of anime image:

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FKvvo4ePDrooyDLx6AYPa%2FIMG_1523.JPG?alt=media&amp;token=7305e9c6-f8c1-499c-8351-3e3222320b71" alt="" width="256"><figcaption><p>Original image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FNaIh77QOAec2XuY3HlGN%2FIMG_1522.JPG?alt=media&amp;token=f46d6b67-df89-4a4f-a498-299b84630017" alt="" width="375"><figcaption><p>2X High res. fix image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F6YDl9Pyb5cBYo2RL9he6%2FIMG_1524.JPG?alt=media&amp;token=1e3f4bac-13c1-4160-bc75-d504a0b49926" alt="" width="375"><figcaption><p>2X Tiled upscale image</p></figcaption></figure></div>

But sometimes, we may prioritize fixing over preserving details.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FMseIzD3uJwlhCzL4pL9E%2FSl9sRtUI8cUfSQpmxKAE_1.png?alt=media&amp;token=a5cc1541-1e44-4e22-b580-0457f4ffcadd" alt="" width="256"><figcaption><p>Original image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FvxBBFt7RPV5jEuxAqwGI%2Fzd5d6qBVjQnvlIpI6IOp_0.png?alt=media&amp;token=e2e8540b-3fdf-48b8-a072-e31f2dc6db88" alt="" width="375"><figcaption><p>2X High res. fix image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2F3QrkDUt4tChcK41B329s%2FiXxvMcGPrBfdFD4VdIiL_0.png?alt=media&amp;token=0aae4b37-9517-4b86-b687-8d71ac482c10" alt="" width="375"><figcaption><p>2X Tiled upscale image</p></figcaption></figure></div>

As you can see, the face in original image is too bad. High res fix does better job on fixing the face. Tiled upscale can slightly fix it while preserving most detail of the sweater. In this case, we can directly go for high res. fix only or tiled upscale then face detailer

Both High res. fix and tiled upscale support 4X. The difference is much more obvious. Look at the skin, hair and sweater.

<div><figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FV9FYWj1bam89otSRoOJ2%2FVcKG4GClIe3KETcjYGIX_0.jpg?alt=media&amp;token=eb144f33-d7b9-4049-93b6-457d1ce9ac83" alt="" width="256"><figcaption><p>Original image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FugAvwPblUcVXjIeG2f3M%2FXrT9Qo5MKEWfeDJMI3tJ_0.jpg?alt=media&amp;token=e879f268-16ed-4ef4-8ef4-50c03a7dbf33" alt="" width="375"><figcaption><p>4X High res. fix image</p></figcaption></figure> <figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fr0bHVxZiwwrDXZ4uuQYW%2FbQpCJ9sHEOfZ2N96uqB4_0%20(1).jpg?alt=media&amp;token=a04658f0-14e3-436f-90f5-f4d5c6bb4b48" alt="" width="375"><figcaption><p>4X Tiled upscale image</p></figcaption></figure></div>

Sometimes you may see the edge of tile in 4X tiled upscale image like this:

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FPeZCx6HQCHkANqlx7lgV%2FH4EhDA80Ou2dOJtG9mxU_0.jpg?alt=media&amp;token=daa0b5ae-9578-46e8-8733-0bca9c8ae8c4" alt="" width="375"><figcaption><p>Obvious tile edges</p></figcaption></figure>

We can easily fix the face using face detailer in this case.


# How to enable sensitive content in Android app

According to Google play store policy, sensitive content is not allowed. You can't enable this option in the android app from play store. Please visit [www.dreamerland.ai ](https://www.dreamerland.ai)for APK version.


# I can' find an option to turn off safety filter in iOS app

We don't offer an in-app option to turn off safety filter. If you have any question, please [contact us](mailto:dreamerai.art@gmail.com).


# Wildcards

Wildcard allows you to use the \_\_**name\_\_** syntax in your prompt to get a random line from the wildcards directory you define. We will go through this with an example below:

First, open the prompt window, and you will see a Wildcard option.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FsUDHifLoYZmHbsSsAMX9%2FIMG_0225.jpg?alt=media&amp;token=4b2c3c9a-47c2-4721-bfce-c3135cae40e9" alt="" width="375"><figcaption><p>Wildcard option</p></figcaption></figure>

Click + to add a new wildcard, or click [✏️](https://emojipedia.org/pencil) to edit the existing one

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FtThSXHPzQWXBWGC2QeXj%2FScreenshot_20240702_013320~2.jpg?alt=media&amp;token=71f2a3ed-56f5-448c-8158-14f743827a97" alt="" width="375"><figcaption></figcaption></figure>

You can define your wildcard now. Enter the name of your wildcard and the prompt for this wildcard. Click "Save" when you finish editing.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FpjWFYaQlvrUbBEzwE6UD%2FScreenshot_2024-07-01-19-47-30-172_art.png?alt=media&amp;token=314ae398-341c-49d5-944d-97864df920a5" alt="" width="375"><figcaption><p>edit wildcard</p></figcaption></figure>

You can use the wildcard you defined in your prompt now. Click the wildcard name, and the **name** syntax will be automatically inserted into your prompt.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2FZ5lhoggxbAJXKtpIZI4L%2FIMG_0226.jpg?alt=media&amp;token=45c4708f-35ae-4295-92b1-3e97a7f29eea" alt="" width="375"><figcaption><p>prompt</p></figcaption></figure>

Hit the start drawing button to see the result.

<figure><img src="https://2310956826-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2Ftbrc6W2n35oVxftMovDQ%2Fuploads%2Fo6cLg9PWe9A2KlhRiOBR%2FScreenshot_20240702_012558~2.jpg?alt=media&amp;token=fc80a481-fabc-4c27-a612-c7d7a95501d4" alt="" width="375"><figcaption><p>Final result</p></figcaption></figure>

The \_\_**name\_\_** syntax is replaced by the contents of the wildcard file you defined. This forms a complete prompt for you.